Data duplication while collecting logs from S3 bucket via incremental S3 input in Splunk Addon for AWS.
Available Languages
Applicability
Splunk Enterprise Splunk Cloud Splunk Addon for AWS (version 7.4.0)Description
When a user attempts to ingest logs stored in an S3 bucket into Splunk using Incremental S3 input, they may see data duplication in Splunk Addon for AWS version 7.4.0. Please refer to the sample screenshot attached below: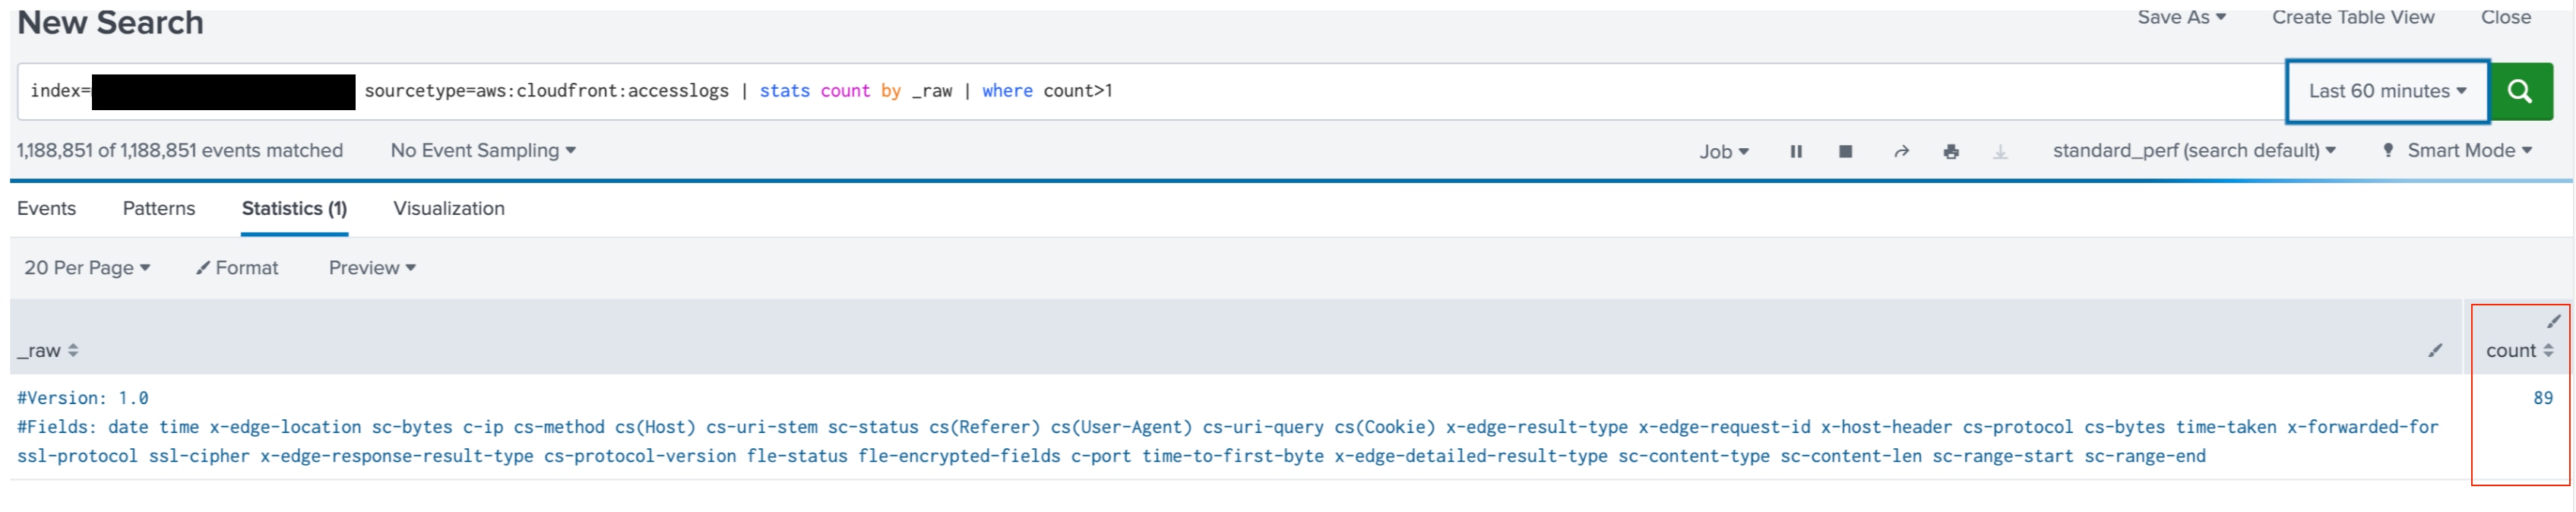
Investigation
SPL queries that can be used to find the duplicate data is below:
index=<index_name> sourcetype=<sourcetype-name> | stats count by _raw, source, host | where count>1OR
index=<index-name> sourcetype=<sourcetype-name> | stats count by _raw | sort 0 -countIn investigation, it was observed that Incremental S3 used to have file-based checkpoint mechanism to store the checkpoint data, There are multiple way’s to configure this input in Splunk Addon for AWS and both use the same checkpoint mechanism.
- For the Incremental S3 input, it will create a single file for each input based on the partition name.
- There are two types of data stored in the checkpoint file: Main checkpoint and temporary checkpoint.
- Once the input execution will be completed, all the data with the temporary checkpoint key in the checkpoint are deleted from the checkpoint file.
According to the logic implemented in the Splunk addon for AWS (when it uses file based checkpoint), the checkpoint used to store the last 500 records and will sweep off the previous entries and only the main checkpoint is migrated to KVstore and keep the existing checkpoint mechanism for the temporary checkpoint.
Splunk Addon for AWS logic after the Checkpoint mechanism moved KVstore:
- The collection is implemented based on the InputName being created.
- The sweeping checkpoint mechanism remains the same as the file-based checkpoint mechanism.
- The temporary checkpoint is maintained in the file only due to the latency issue of KVStore. The main checkpoint is maintained in the KvStore collection.
Issue identified in KV store checkpoint mechanism that could create duplicate events:
The filename stored in the KVStore to be used as a marker for checkpoint was not being stored in a sorted manner, unlike the file checkpoint. As a result, the code was not picking up the correct marker in some scenarios.
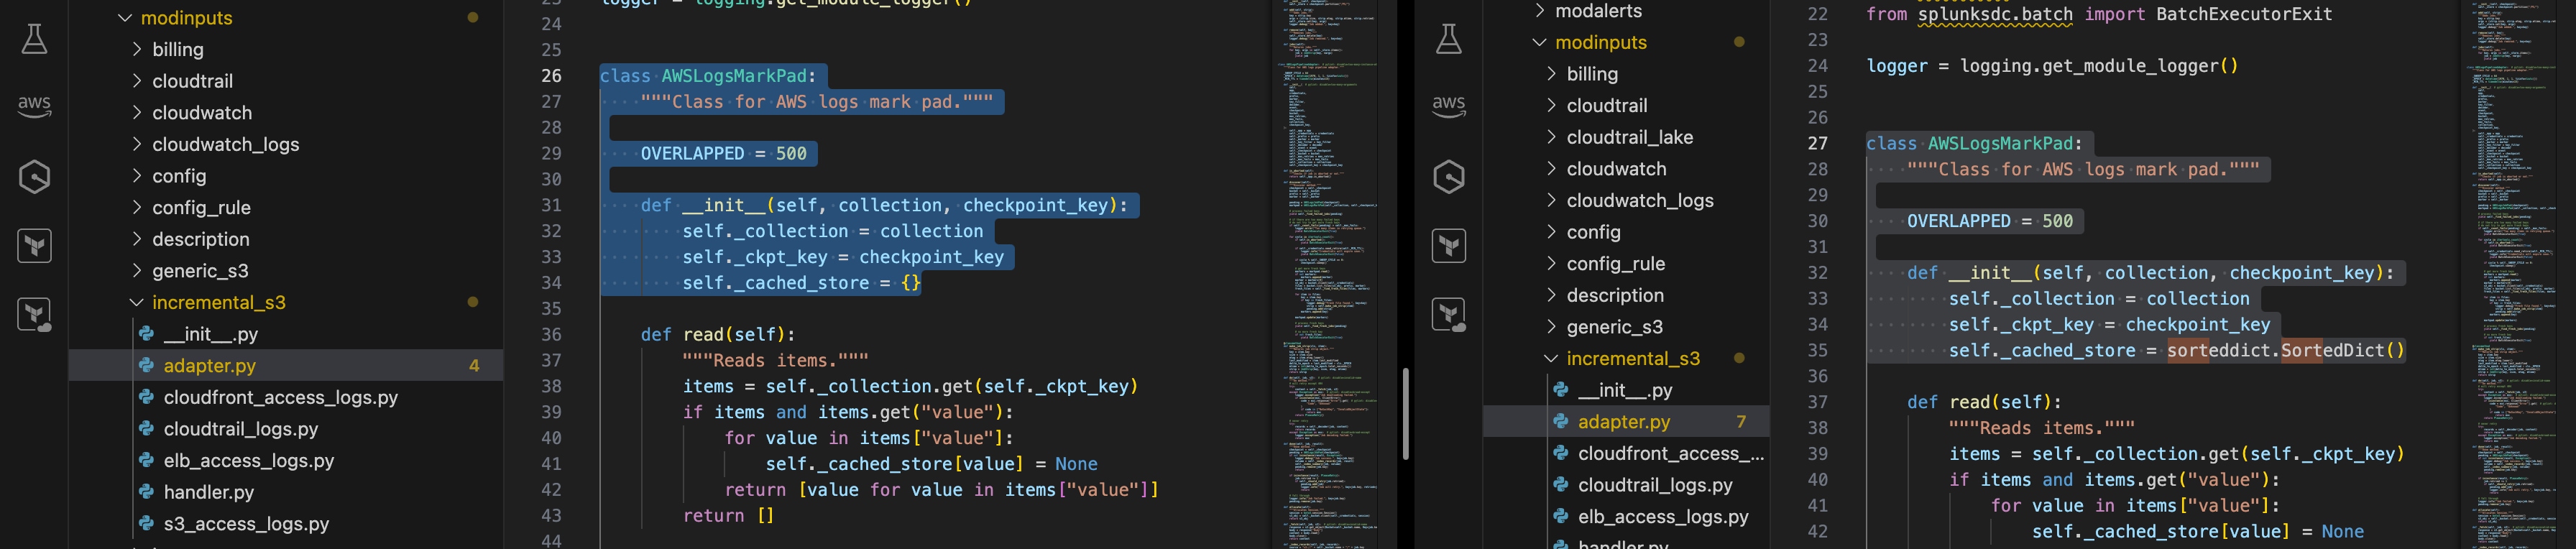
Looking at the Splunk add-on for AWS logic (Incremental S3), the last 500 files are stored in the KVStore, with the first file used as the marker. Based on this marker, the input fetches all the files that come after it in lexicographical order. If any new file gets added or any file is being modified in S3 bucket between the already ingested last 500 files which are there in KVStore, then the newly added file/updated file will be store at the end of the KVStore even though it is in between and in some scenario, if lastly added file becomes the marker then data gets duplicated. Hence, a code change was implemented in Splunk Add-on for AWS version 7.5.0 to store them in a sorted manner, as the input works based on lexicographic logic.
This logic has been implemented in version 7.5.0 in the python file called adapter.py for incremental S3. Please find the screenshot attached showing side by side comparison of version 7.4.0 (left section) and 7.5.0 (right section).
Resolution
Data duplication for incremental S3 input was a known issue in Splunk Addon for AWS version 7.4.0, however it has been resolved in Splunk Addon for AWS version 7.5.0. If a user is encountering this problem, it is recommended that they upgrade the Splunk addon for AWS to version 7.5.0.
Revision History
| Revision | Publish Date | Comments |
|---|---|---|
1.0 |
29-Sep-2026
|
Initial Release |
 Feedback
Contact Cisco
- Open a Support Case

- (Requires a Cisco Service Contract)
This Document Applies to These Products
Related Articles
- Splunk Add-on for AWS : Incremental S3 input is failing which is configured using AWS China account.
- The Splunk Add-on for AWS : Some event are missing for SQS-based-S3 input
- Generic S3 input stopped collecting new logs configured in Splunk Add-on for Amazon Web Services(AWS)
- Splunk Add-on for AWS Fails to Download Files >=10MB in size from S3 Bucket