PDF(6.0 MB) View with Adobe Reader on a variety of devices
ePub(14.9 MB) View in various apps on iPhone, iPad, Android, Sony Reader, or Windows Phone
Mobi (Kindle)(28.4 MB) View on Kindle device or Kindle app on multiple devices
Updated:March 5, 2025
Bias-Free Language
The documentation set for this product strives to use bias-free language. For the purposes of this documentation set, bias-free is defined as language that does not imply discrimination based on age, disability, gender, racial identity, ethnic identity, sexual orientation, socioeconomic status, and intersectionality. Exceptions may be present in the documentation due to language that is hardcoded in the user interfaces of the product software, language used based on RFP documentation, or language that is used by a referenced third-party product. Learn more about how Cisco is using Inclusive Language.
Clustering lets you group multiple Threat Defense Virtuals together as a single logical device. A cluster provides all the
convenience of a single device (management, integration into a network) while achieving the increased throughput and redundancy
of multiple devices.
Currently, only routed firewall mode is supported.
This section describes the clustering architecture and how it works.
How the Cluster Fits into Your Network
The cluster consists of multiple firewalls acting as a single device. To act as a cluster, the firewalls need the following
infrastructure:
Isolated network for intra-cluster communication, known as the cluster control link, using VXLAN interfaces. VXLANs, which act as Layer 2 virtual networks over Layer 3 physical networks, let the Firewall Threat Defense
Virtual send broadcast/multicast messages over the cluster control link.
Load Balancer(s)—For external load balancing, you have the following options:
Azure Gateway Load Balancer
In an Azure service chain, Firewall Threat Defense
Virtuals act as a transparent gateway that can intercept packets between the internet and the customer service. The Firewall Threat Defense
Virtual defines an external interface and an internal interface on a single NIC by utilizing VXLAN segments in a paired proxy.
Equal-Cost Multi-Path Routing (ECMP) using inside and outside routers such as Cisco Cloud Services Router
ECMP routing can forward packets over multiple “best paths” that tie for top place in the routing metric. Like EtherChannel,
a hash of source and destination IP addresses and/or source and destination ports can be used to send a packet to one of the
next hops. If you use static routes for ECMP routing, then the Firewall Threat
Defense failure can cause problems; the route continues to be used, and traffic to the failed Firewall Threat
Defense will be lost. If you use static routes, be sure to use a static route monitoring feature such as Object Tracking. We recommend
using dynamic routing protocols to add and remove routes, in which case, you must configure each Firewall Threat
Defense to participate in dynamic routing.
Note
Layer 2 Spanned EtherChannels are not supported for load balancing.
Individual interfaces
You can configure cluster interfaces as individual interfaces.
Individual interfaces are normal routed interfaces, each with their own local IP address. The IP address for the interface
will be configured automatically via DHCP. Static IP configuration is not supported.
Control and data node roles
When you add a cluster in the Firewall Management
Center , you choose one firewall to be the control node, and all additional firewalls to be data nodes. When you first create the
cluster, the control node you specify will become the control node simply because it is the first node added to the cluster.
Later, if multiple cluster nodes come online at the same time, the control node is determined by the priority setting; the
priority is set between 1 and 100, where 1 is the highest priority.
When you create the cluster and deploy the cluster configuration, the Firewall Management
Center deploys a special bootstrap configuration to each node that includes fundamental settings such as the cluster control link
configuration. The bootstrap configuration lets each node join the cluster. Most bootstrap settings are defined in the cluster
wizard; however, you define the cluster control link interface hardware configuration (for example, creating an EtherChannel
or setting the Ethernet speed) on the control node before you create the cluster. The cluster control link settings are copied
to the bootstrap configuration for each node.
All nodes in the cluster share the same policy configuration. The node that you initially specify as the control node will
overwrite the configuration on the data nodes when they join the cluster, so you only need to perform initial configuration
on the control node before you form the cluster. After you create the cluster, all configuration changes are made at the cluster
level and are shared by all nodes.
Some features do not scale in a cluster, and the control node handles all traffic for those features.
Cluster Control Link
Each node must dedicate one interface as a VXLAN (VTEP) interface for the cluster control link.
VXLAN Tunnel Endpoint
VXLAN tunnel endpoint (VTEP) devices perform VXLAN encapsulation and decapsulation. Each VTEP has two interface types: one
or more virtual interfaces called VXLAN Network Identifier (VNI) interfaces, and a regular interface called the VTEP source
interface that tunnels the VNI interfaces between VTEPs. The VTEP source interface is attached to the transport IP network
for VTEP-to-VTEP communication.
VTEP Source Interface
The VTEP source interface is a regular Firewall
Threat Defense Virtual interface with which you plan to associate the VNI interface. You can configure one VTEP source interface to act as the cluster
control link. The source interface is reserved for cluster control link use only. Each VTEP source interface has an IP address
on the same subnet. This subnet should be isolated from all other traffic, and should include only the cluster control link
interfaces.
VNI Interface
A VNI interface is similar to a VLAN interface. It is a virtual interface that keeps network traffic separated on a given
physical interface by using tagging. You can only configure one VNI interface. Each VNI interface has an IP address on the
same subnet.
Peer VTEPs
Unlike regular VXLAN for data interfaces, which allows a single VTEP peer, Firewall
Threat Defense Virtual clustering allows you to configure multiple peers.
Cluster control link traffic overview
Cluster control link traffic includes both control and data traffic.
Control traffic includes:
Control node election.
Configuration replication.
Health monitoring.
Data traffic includes:
State replication.
Connection ownership queries and data packet forwarding.
Configuration replication
All nodes in the cluster share a single configuration. You can only make configuration changes on the control node (with the
exception of the bootstrap configuration), and changes are automatically synced to all other nodes in the cluster.
Management network
You must manage each node using the management interface. Management from a data interface is not supported with clustering.
Licenses for Threat Defense Virtual clustering
You assign feature licenses to the cluster as a whole, not to individual nodes. However, each node of the cluster consumes
a separate license for each feature. The clustering feature itself does not require any licenses.
Note
APEX, PLUS, and VPN-Only licenses are not supported for clustering. Before you create a cluster, remove unsupported license
assignments from the devices that will become cluster nodes.
Performance tier license requirements
Each Firewall Threat Defense Virtual cluster node requires the same performance tier license. We recommend using the same number of CPUs and memory for all members,
or else performance will be limited on all nodes to match the least capable member. The throughput level will be replicated
from the control node to each data node so they match.
When you add the control node to the Firewall Management
Center, you can specify the feature licenses you want to use for the cluster. You can modify licenses for the cluster in the Devices > Device Management, Cluster > License area.
Note
If you add the cluster before the Firewall Management
Center is licensed (and running in Evaluation mode), then when you license the Firewall Management
Center, you can experience traffic disruption when you deploy policy changes to the cluster. Changing to licensed mode causes all
data units to leave the cluster and then rejoin.
Requirements and Prerequisites for Threat Defense Virtual Clustering
Model Requirements
FTDv5, FTDv10, FTDv20, FTDv30, FTDv50, FTDv100
Note
FTDv5 and FTDv10 do not support Azure Gateway Load Balancer.
Must be in the same performance tier. We recommend using the same number of CPUs and memory for all nodes, or else peformance
will be limited on all nodes to match the least capable node.
The Firewall Management
Center access must be from the Management interface; data interface management is not supported.
Must run the identical software except at the time of an image upgrade. Hitless upgrade is supported.
Cluster control link interfaces of all units must be in the same subnet.
MTU
Make sure the ports connected to the cluster control link have the correct (higher) MTU configured. If there is an MTU mismatch,
the cluster formation will fail. When a node joins the cluster, it checks MTU compatibility by sending a ping to the control node with a packet size matching
the cluster control link MTU. If the initial ping fails, the node tries a ping using a smaller packet size (the MTU divided
by 2, then by 4, then by 8) until a ping succeeds. A notification is generated so you can fix the MTU mismatch on connecting
switches and try again.
The cluster control link MTU should be 154 bytes higher than the data interfaces. Because the cluster control link traffic
includes data packet forwarding, the cluster control link needs to accommodate the entire size of a data packet plus cluster
traffic overhead (100 bytes) plus VXLAN overhead (54 bytes).
For Azure with GWLB, the data interface uses VXLAN encapsulation. In this case, the entire Ethernet datagram is being encapsulated,
so the new packet is larger and requires a larger MTU. You should set the cluster control link MTU to be the source interface
MTU + 80 bytes.
Note
For Threat Defense Virtual clusters on Azure, modifying the cluster control link (CCL) MTU via FlexConfig in Management Center
is not recommended, as it may cause cluster stability issues.
We do not recommend setting the cluster control link MTU between 2561 and 8362; due to block pool handling, this MTU size
is not optimal for system operation.
The following table shows the default values for the cluster control link MTU and the data interface MTU.
Table 1. Default MTU
Public Cloud
Cluster Control Link MTU
Data Interface MTU
Azure with GWLB
1454
1374
Azure
1454
1300
Guidelines for Threat Defense Virtual Clustering
High Availability
High Availability is not supported with clustering.
IPv6
The cluster control link is only supported using IPv4.
Multi-zone clustering
Multi-zone clustering is supported for up to three zones.
Additional Guidelines
When significant topology changes occur (such as adding or removing an EtherChannel interface, enabling or disabling an interface
on the Firewall Threat
Defense or the switch, adding an additional switch to form a VSS or VNet) you should disable the health check feature and also disable
interface monitoring for the disabled interfaces. When the topology change is complete, and the configuration change is synced
to all units, you can re-enable the interface health check feature.
When adding a node to an existing cluster, or when reloading a node, there will be a temporary, limited packet/connection
drop; this is expected behavior. In some cases, the dropped packets can hang your connection; for example, dropping a FIN/ACK
packet for an FTP connection will make the FTP client hang. In this case, you need to reestablish the FTP connection.
Do not power off a node without first disabling clustering on the node.
For decrypted TLS/SSL connections, the decryption states are not synchronized, and if the connection owner fails, then decrypted
connections will be reset. New connections will need to be established to a new node. Connections that are not decrypted (they
match a do-not-decrypt rule) are not affected and are replicated correctly.
Dynamic scaling is supported from Secure Firewall version 7.3.
Perform a global deployment after the completion of each maintenance window.
Ensure that you do not remove more than one device at a time from the scale set (Azure). We also recommend that you run the
cluster disable command on the device before removing the device from the scale set (Azure).
If you want to disable data nodes and the control node in a cluster, we recommend that you disable the data nodes before disabling
the control node. If a control node is disabled while there are other data nodes in the cluster, one of the data nodes has
to be promoted to be the control node. Note that the role change could disturb the cluster.
In the customized day 0 configuration scripts given in this guide, you can change the IP addresses as per your requirement,
provide custom interface names, and change the sequence of the CCL-Link interface.
If you experience CCL instability issues, such as intermittent ping failures, after deploying a Threat Defense Virtual cluster
on a cloud platform, we recommend that you address the reasons that are causing CCL instability. Also, you can increase the
hold time as a temporary workaround to mitigate CCL instability issues to a certain extent. For more information on how to
change the hold time, see Edit Cluster Health Monitor Settings.
When you are configuring your security firewall rule or security group for the Management Center virtual, you must include
both Private and Public IP addresses of the Firewall Threat Defense
Virtual in the Source IP address range. Also, ensure to specify the Private and Public IP addresses of the Firewall Management Center
Virtual in the security firewall rule or security group of the Firewall Threat Defense
Virtual. This is important to ensure proper registration of nodes during clustering deployment.
Defaults for Clustering
The cLACP system ID is auto-generated, and the system priority is 1 by default.
The cluster health check feature is enabled by default with the holdtime of 3 seconds. Interface health monitoring is enabled
on all interfaces by default.
The cluster auto-rejoin feature for a failed cluster control link is unlimited attempts every 5 minutes.
The cluster auto-rejoin feature for a failed data interface is 3 attempts every 5 minutes, with the increasing interval set
to 2.
Connection replication delay of 5 seconds is enabled by default for HTTP traffic.
Deploy the cluster in Azure
You can use the cluster with the Azure Gateway Load Balancer (GWLB), or with a non-native load balancer. To deploy a cluster
in Azure, use Azure Resource Manager (ARM) templates to deploy a Virtual Machine Scale Set.
Sample topology for GWLB-based cluster deployment
Sample topologies for deploying Gateway Load Balancer (GWLB) clusters are given below.
Figure 1. Inbound traffic use case and topology with GWLB
Figure 2. Outbound traffic use case and topology with GWLB
Azure gateway load balancer and paired proxy
In an Azure service chain, Threat Defense Virtuals act as a transparent gateway that can intercept packets between the internet
and the customer service. The Threat Defense Virtual defines an external interface and an internal interface on a single NIC
by utilizing VXLAN segments in a paired proxy.
The figure shows traffic forwarded to the Azure Gateway Load Balancer from the Public Gateway Load Balancer on the external
VXLAN segment. The Gateway Load Balancer balances traffic among multiple Threat Defense Virtuals, which inspect the traffic
before either dropping it or sending it back to the Gateway Load Balancer on the internal VXLAN segment. The Azure Gateway
Load Balancer then sends the traffic back to the Public Gateway Load Balancer and to the destination.
Figure 3. Azure gateway load balancer with paired proxy
End-to-end process for deploying Threat Defense Virtual cluster in Azure with GWLB
Provides a workflow to help users successfully deploy and verify a Threat Defense Virtual cluster on Azure with GWLB using
either template-based or manual deployment processes.
Template-based Deployment
The following flowchart illustrates the workflow for template-based deployment of the Threat Defense Virtual cluster in Azure
with GWLB.
Complete these prerequisite tasks before deploying the Azure GWLB cluster.
To allow the cluster to auto-register to the management center, create a user with Network Admin & Maintenance User privileges
on the management center. Users with these privileges can use REST API. Refer to the Cisco Secure Firewall Management Center Administration Guide.
Add an access policy in the management center that matches the name of the policy that you will specify during template deployment.
Ensure that the Management Center Virtual is licensed appropriately.
Perform these steps after the cluster is added to the Management Center Virtual:
Configure platform settings with the health check port number in the Management Center. For more information on configuring
this, see Platform Settings.
Create a static route for data traffic. For more information on creating a static route, see Add a Static Route.
Sample static route configuration:
Network: any-ipv4
Interface: vxlan_tunnel
Leaked from Virtual Router: Global
Gateway: vxlan_tunnel_gw
Tunneled: false
Metric: 2
Note
vxlan_tunnel_gw is the data subnet's gateway IP address.
Deploy cluster on Azure with GWLB using an Azure resource manager template
This task creates a clustered deployment of Firewall Threat Defense Virtual instances on Azure using Gateway Load Balancer
(GWLB) through Azure Resource Manager templates.
Deploy the Virtual Machine Scale Set for Azure GWLB using the customized Azure Resource Manager (ARM) template. The templates
mentioned in the steps below are available on GitHub.
In the Basics tab, choose the Subscription and Resource Group from the drop-down lists.
Choose the required Region.
Step 4
Create a virtual network with three subnets: Management, Data, and Cluster Control Link (CCL).
Create the virtual network.
In the Basics tab, choose the Subscription and Resource Group from the drop-down lists.
Choose the required Region. Click Next: IP addresses.
In the IP Addresses tab, click Add subnet and add the following subnets – Management, Data, and Cluster Control Link.
Add the subnets.
Step 5
Deploy the custom template.
Click Create > Template deployment (deploy using custom templates).
Click Build your own template in the editor.
Click Load File, and upload azure_ftdv_gwlb_cluster.json.
Click Save.
Step 6
Configure the Instance details.
Enter the required values and then click Review + create.
Click Create after the validation is passed.
After the instance is running, verify the cluster deployment by logging into any one of the nodes and entering the show cluster info command.
Figure 4. Show cluster info
Step 7
In the Azure Portal, click the Function app to register the cluster with the Firewall Management
Center.
Note
If you do not want to use the Function app, you can alternatively register the control node to the Firewall Management
Center directly by using Add > Device (not Add > Cluster). The rest of the cluster nodes will register automatically.
Step 8
Create FTPS Credentials by clicking Deployment Center > FTPS credentials > User scope > Configure Username and Password, and then click Save.
Step 9
Upload the Cluster_Function.zip file to the Function app by executing the following curl command in the local terminal.
curl -X POST -uusername--data-binary @"Cluster_Function.zip" https:// Function_App_Name.scm.azurewebsites.net/api/zipdeploy
Note
The curl command might take few minutes (~2 to 3 minutes) to complete command execution.
The function will be uploaded to the Function app. The function will start, and you can see the logs in the storage account's
outqueue. The device registration with the Management Center will be initiated.
places the Threat Defense Virtual cluster between internal and external load balancers,
uses a Management Center Virtual instance to manage the cluster, and
depicts both inbound and outbound traffic flow patterns.
Traffic flow patterns
This topology shows how traffic moves through the network components:
Inbound traffic: Traffic from the internet goes to the external load balancer, which transmits the traffic to the Threat Defense Virtual
cluster. After the traffic has been inspected by a Threat Defense Virtual instance in the cluster, it is forwarded to the
application virtual machine (VM).
Outbound traffic: Traffic from the application VM is transmitted to the internal load balancer. Traffic is then forwarded to the Threat Defense
Virtual cluster and then sent out to the internet.
End-to-end process for deploying Threat Defense Virtual cluster in Azure with NLB
Provides a workflow to help users successfully deploy and verify a Threat Defense Virtual cluster on Azure with NLB using
either template-based or manual deployment processes.
Template-based Deployment
The following flowchart illustrates the workflow of template-based deployment of Threat Defense Virtual cluster in Azure with
NLB.
Before deploying an Azure Network Load Balancer cluster, ensure that you complete these prerequisite tasks.
To allow the cluster to auto-register with the Management Center, create a user with Network Admin & Maintenance User privileges
on the Management Center. Users with these privileges can use REST API. Refer to the Cisco Secure Firewall Management Center Administration Guide.
Add an access policy in the Management Center that matches the name of the policy that you will specify during template deployment.
Ensure that the Management Center Virtual is licensed appropriately.
After the cluster is added to the Management Center Virtual, complete these configuration steps:
Configure platform settings with the health check port number in the Management Center. For more information on configuring
this, refer to Platform Settings.
Create static routes for traffic from outside and inside interfaces. For more information on creating a static route, refer
to Add a Static Route.
Important
Configure static routes for both interface gateway paths when Azure Load Balancer health probes are enabled on both inside
and outside interfaces of FTDv cluster nodes. Do not rely on a single default route. Azure health probes may arrive on either
interface, so FTDv must respond using the correct interface path. Missing routing configuration can cause probe drops and
load balancer health check failures. If SSH on port 22 is used as the health probe and SSH is enabled on both interfaces through
Platform Settings, verify return path routing for both interfaces. Similarly, if HTTP is used as the health probe and HTTP
or HTTPS is enabled on both interfaces through Platform Settings, verify return path routing for both interfaces.
Note
Ensure that you do not configure your virtual network using the Microsoft-owned IP address range that includes 168.63.129.16.
This configuration causes a conflict with the health probe's IP address. For more information, refer to Microsoft Azure design guidance.
Sample static route configuration for the outside interface:
Network: any-ipv4
Interface: outside
Leaked from Virtual Router: Global
Gateway: ftdv-cluster-outside
Tunneled: false
Metric: 10
Note
ftdv-cluster-outside is the outside subnet's gateway IP address.
Sample static route configuration for the inside interface:
Network: any-ipv4
Interface: inside
Leaked from Virtual Router: Global
Gateway: ftdv-cluster-inside-gw
Tunneled: false
Metric: 11
Note
ftdv-cluster-inside-gw is the inside subnet's gateway IP address.
Configure NAT rule for data traffic. For more information on configuring NAT rules, refer to Network Address Translation.
Deploy cluster on Azure with NLB using an Azure resource manager template
This task enables you to deploy a cluster for Azure NLB using the customized Azure Resource Manager (ARM) template for scalable
network security.
Deploy the cluster for Azure NLB using the customized Azure Resource Manager (ARM) template. Note that the templates mentioned
in the steps below are available on GitHub.
In the Basics tab, choose the Subscription and Resource Group from the drop-down lists.
Choose the required Region.
Step 4
Create a virtual network with 5 subnets: Management, Diagnostic, Inside, Outside, and Cluster Control Link.
Create the virtual network.
In the Basics tab, choose the Subscription and Resource Group from the drop-down lists.
Choose the required Region. Click Next: IP addresses.
Add the subnets.
In the IP Addresses tab, click Add subnet and add the following subnets – Management, Diagnostic, Inside, Outside, and Cluster Control Link.
Step 5
Deploy the custom template.
Click Create > Template deployment (deploy using custom templates).
Click Build your own template in the editor.
Click Load File, and upload azure_ftdv_nlb_cluster.json.
Click Save.
Step 6
Configure the instance details.
Enter the required values and then click Review + create.
Note
For the cluster control link starting and ending addresses, specify only as many addresses as you need (up to 16). A larger
range can affect performance.
Click Create after the validation is passed.
After the instance is running, verify the cluster deployment by logging into any one of the nodes and using the show cluster info command.
Figure 8. Show cluster info
Step 7
In the Azure Portal, click the Function app to register the cluster to the Firewall Management
Center.
Note
If you do not want to use the Function app, you can alternatively register the control node with the Management Center directly
by using Add > Device (not Add > Cluster). The rest of the cluster nodes will register automatically.
Step 8
Create FTPS Credentials by clicking Deployment Center > FTPS credentials > User scope > Configure Username and Password, and then click Save.
Step 9
Upload the Cluster_Function.zip file to the Function app by executing the curl command in the local terminal.
curl -X POST -uusername--data-binary @"Cluster_Function.zip" https:// Function_App_Name.scm.azurewebsites.net/api/zipdeploy
Note
The curl command might take a few minutes (~2 to 3 minutes) to complete command execution.
The function will be uploaded to the Function app. The function will start, and you can see the logs in the storage account's
outqueue. The device registration with the Management Center will be initiated.
Manual cluster deployment in Azure
To deploy the cluster manually, prepare the day0 configuration, deploy each node, and then add the control node to the Firewall Management
Center .
Create the Day0 configuration for Azure
You can use either a fixed configuration or a customized configuration.
Create the Day0 configuration with a fixed configuration for Azure
The fixed configuration will auto-generate the cluster bootstrap configuration.
"Cluster": {
"CclSubnetRange": "10.45.3.4 10.45.3.30",    //mandatory user input
"ClusterGroupName": "ngfwv-cluster",         //mandatory user input
"HealthProbePort": "7777",                   //mandatory user input
"GatewayLoadBalancerIP": "10.45.2.4",        //mandatory user input
"EncapsulationType": "vxlan",
"InternalPort": "2000",
"ExternalPort": "2001",
"InternalSegId": "800",
"ExternalSegId": "801"
}
Note
If you are copying and pasting the configuration given above, ensure that you remove //mandatory user input from the configuration
For the Azure health check settings, be sure to specify the HealthProbePort you set here.
For the CclSubnetRange variable, specify a range of IP addresses starting from x.x.x.4. Ensure that you have at least 16 available IP addresses
for clustering. Some examples of start and end IP addresses are given below.
Note
All cluster infrastructure subnets must use /27 CIDR
Table 2. Examples of start and end IP addresses
CIDR
Start IP Address
End IP Address
10.1.1.0/27
10.1.1.4
10.1.1.30
10.1.1.32/27
10.1.1.36
10.1.1.62
10.1.1.64/27
10.1.1.68
10.1.1.94
10.1.1.96/27
10.1.1.100
10.1.1.126
10.1.1.128/27
10.1.1.132
10.1.1.158
10.1.1.160/27
10.1.1.164
10.1.1.190
10.1.1.192/27
10.1.1.196
10.1.1.222
10.1.1.224/27
10.1.1.228
10.1.1.254
Create the Day0 configuration with a customized configuration for azure
You can enter the entire cluster bootstrap configuration using commands.
Go to the Marketplace and search for Cisco Secure Firewall Threat Defense Virtual – BYOL and PAYG and click Create.
Step 5
Fill the required details and choose Yes for Is this VM going to be part of Cluster?
Paste the following cluster-related configuration in the text box.
"Cluster": {
"CclSubnetRange": "ip_address_start ip_address_end",	//mandatory user input
"ClusterGroupName": "cluster_name",	//mandatory user input
"HealthProbePort": "port_number",	//mandatory user input
"GatewayLoadBalancerIP": "ip_address",	 //mandatory user input
"EncapsulationType": "vxlan",
"InternalPort": "internal_port_number",
"ExternalPort": "external_port_number",
"InternalSegId": "internal_segment_id",
"ExternalSegId": "external_segment_id"
}
Click Next and select the Virtual Network & Subnets.
Click Review + create. Wait for the Threat Defense Virtual deployment to complete.
Step 6
Connect to the Threat Defense Virtual device and use the show cluster info command to confirm the cluster formation is successful.
> show cluster info
Cluster ngfwv-cluster: On
    Interface mode: individual
Cluster Member Limit : 16
    This is "4" in state CONTROL_NODE
        ID        : 0
        Version   : 9.23(1)
        Serial No.: 9AC1VMGJKAQ
        CCL IP    : 169.254.200.4
        CCL MAC   : 6045.bda8.e07b
        Module    : NGFWv
        Resource  : 4 cores / 14336 MB RAM
        Last join : 05:22:55 UTC Jul 14 2025
        Last leave: N/A
Other members in the cluster:
    There is no other unit in the cluster
>
Go to the Marketplace and search for Cisco Secure Firewall Threat Defense Virtual – BYOL and PAYG and click Create.
Step 5
Fill the required details and choose Yes for Is this VM going to be part of Cluster?
Paste the following cluster-related configuration in the text box.
"Cluster": {
"CclSubnetRange": "ip_address_start ip_address_end",	//mandatory user input
"ClusterGroupName": "cluster_name"	//mandatory user input
}
Step 6
Click Next and select the Virtual Network & Subnets.
Step 7
Click Review + create. Wait until the Threat Defense Virtual deployment is completed.
Step 8
Connect to the Threat Defense Virtual device and use the show cluster info command to confirm the cluster formation is successful.
> show cluster info
Cluster ngfwv-cluster: On
    Interface mode: individual
Cluster Member Limit : 16
    This is "4" in state CONTROL_NODE
        ID        : 0
        Version   : 9.23(1)
        Serial No.: 9AC1VMGJKAQ
        CCL IP    : 169.254.200.4
        CCL MAC   : 6045.bda8.e07b
        Module    : NGFWv
        Resource  : 4 cores / 14336 MB RAM
        Last join : 05:22:55 UTC Jul 14 2025
        Last leave: N/A
Other members in the cluster:
    There is no other unit in the cluster
>
This reference provides troubleshooting guidance for resolving common issues that may occur during cluster deployment in Azure,
including traffic flow problems, cluster formation failures, and role assignment errors.
Issue: No traffic flow
Troubleshooting:
Check if the health probe status of the Threat Defense Virtual instances deployed with a GWLB is healthy.
If the Threat Defense Virtual instance's health probe status is unhealthy-
Check if the static route is configured in the Management Center Virtual.
Check if the default gateway is the data subnet's gateway IP address.
Check if the Threat Defense Virtual instance is receiving health probe traffic.
Check if the access list configured in the Management Center Virtual allows health probe traffic.
Issue: Cluster is not formed
Troubleshooting:
Check the IP address of the NVE-only cluster interface. Ensure that you can ping the NVE-only cluster interface of other nodes.
Check the IP address of the NVE-only cluster interfaces are part of the object group.
Ensure that the NVE interface is configured with the object group .
Ensure that the cluster interface in the cluster group has the right VNI interface. This VNI interface has the NVE with the
corresponding object group.
Ensure that the nodes are pingable from each other. Since each node has its own cluster interface IP, these should be pingable
from each other.
Check if the CCL subnet's start and end address mentioned during template deployment is correct. The start address should
begin with the first available IP address in the subnet. For example, if the subnet is 192.168.1.0/27. The start address should
be 192.168.1.4 (the three IP addresses at the start are reserved by Azure).
Check if the Management Center Virtual has a valid license.
Issue: Role-related error while deploying resources again in the same resource group.
Troubleshooting: Remove the roles given below by using these commands on the terminal.
Error message:
"error": {
"code": "RoleAssignmentUpdateNotPermitted",
"message": "Tenant ID, application ID, principal ID, and scope are not allowed to be
updated."}
az role assignment delete --resource-group <Resource Group Name> --role"Storage Queue Data Contributor"
az role assignment delete --resource-group <Resource Group Name> --role "Contributor"
Firewall Threat Defense
Virtual clustering autoscale solution in Azure
A typical cluster deployment in an Azure region includes a defined number of Firewall Threat Defense
Virtual instances (nodes). When the Azure region traffic varies, without dynamic scaling (autoscale) of the nodes, resource utilization
in such cluster arrangement may underutilize the resources or cause latency. Cisco offers an autoscale solution for Firewall Threat Defense
Virtual clustering in Version 7.7 and later that supports dynamic scaling of nodes in the Azure region. It allows you to scale in
or scale out nodes from the cluster based on the network traffic. It uses logic based on the resource utilization statistics
from Azure VMSS metrics such as CPU and memory metrics, to dynamically add or remove a node from a cluster.
Autoscale solution features
The Firewall Threat Defense
Virtual clustering with autoscale solution in Azure supports both Network Load Balancer (NLB or Sandwich topology) and Gateway Load
Balancer (GWLB).
Cisco provides separate Azure Resource Manager (ARM) templates for deploying Firewall Threat Defense
Virtual cluster with autoscale in Azure using NLB and GWLB, as well as infrastructure and configuration templates for deploying the
Azure services such as Function App and Logic App.
Sample topologies
The sample topologies provided here
demonstrate how Firewall Threat Defense
Virtual clustering with autoscale functions in Azure environments
provide reference implementations for different load balancing configurations, and
show automated horizontal scaling solutions for network security deployment.
Firewall Threat Defense
Virtual clustering with autoscale using sandwich topology (Network Load Balancer)
The Firewall Threat Defense
Virtual clustering with autoscale in Azure using sandwich topology (NLB) use case is an automated horizontal scaling solution that
positions the Firewall Threat Defense
Virtual scale set sandwiched between an Azure Internal load balancer (ILB) and an Azure External load balancer (ELB).
In this topology, the Firewall Threat Defense
Virtual uses only four interfaces: management, inside, outside, and CCL subnets.
This describes high-level flow on how a Firewall Threat Defense
Virtual cluster with autoscale in Azure using NLB functions:
The ELB distributes traffic from the internet to the Firewall Threat Defense
Virtual instances in the scale set, and then the firewall forwards traffic to the application.
The ILB distributes outbound internet traffic from an application to Firewall Threat Defense
Virtual instances in the scale set and then the firewall forwards traffic to the internet.
A network packet will never pass through both internal and external load balancers in a single connection.
The number of Firewall Threat Defense
Virtual instances in the scale set will be scaled and configured automatically based on load conditions.
Firewall Threat Defense
Virtual clustering with autoscale using Gateway Load Balancer
The integration of the Azure Gateway Load Balancer (GWLB) and Firewall Threat Defense
Virtual cluster using autoscale solution simplifies deployment, management, and scaling of instances in the cluster setup. The Azure
Gateway Load Balancer (GWLB) ensures that internet traffic to and from an Azure VM, such as an application server, is inspected
by secure firewall without requiring any routing changes. This integration also reduces operational complexity and provides
a single entry and exit point for traffic at the firewall. The applications and infrastructure can maintain visibility of
source IP address, which is critical in some environments.
The Firewall Threat Defense
Virtual uses only three interfaces: management, data, and CCL interface in this use case.
Note
Network Address Translation (NAT) is not required if you are deploying the Azure GWLB.
Only IPv4 is supported.
This describes high-level flow on how a Firewall Threat Defense
Virtual cluster with autoscale in Azure using GWLB functions:
Inbound traffic from the internet goes to the GWLB endpoint, which then transmits the traffic to the GWLB.
The traffic is then routed to the Firewall Threat Defense
Virtual cluster.
After the traffic is inspected by the Firewall Threat Defense
Virtual instance in the cluster, it is forwarded to the application VM.
Prerequisites for Threat Defense Virtual clustering autoscale solution on Azure
Ensure that you have the Owner role in the Azure subscription.
Create the Azure Resource Group. Ensure that the Azure Virtual Network and the necessary subnets are created.
Interfaces for the NLB-based cluster: Management, Diagnostic, Inside, Outside, CCL and the function app.
Interfaces for the GWLB-based cluster: Management, Diagnostic, Data, CCL and the function app.
Complete the following Management Center configuration tasks:
Ensure that Management Center Virtual is licensed correctly.
Create the access control policy.
Create the Security Zone (SZ) object for the interfaces. For the NLB-based cluster, create the Security Zone for the inside
and outside interfaces. For the GWLB-based cluster, create the Security Zone for the data interface.
Create a separate user name and password for the Azure function to add the Threat Defense Virtual instances to the Management
Center Virtual and configure the instances.
Install the Azure CLI on your local system.
Download the Azure Clustering Autoscale repository from GitHub to your local computer and run the command python3 make.py build to create the Azure functions zip file.
Autoscale logic for Firewall Threat Defense Virtual clustering in Azure
Scaling Policy
In a cluster with autoscale, the scaling of nodes is determined based on the
following policies:
Scaling policy 1 - When one cluster node exceeds the resource utilization
limits.
Scaling policy 2 - Overall average resource utilization of all the nodes.
Scale-out
Scale-out adds a new node to the cluster when the traffic load threshold exceeds the
configured CPU or memory limit on any cluster node.
The following is the process of adding a new node to the cluster during
scale-out:
A new Firewall Threat Defense Virtual instance is launched.
Appropriate configuration is applied to a Firewall Threat Defense Virtual .
Appropriate licenses are applied.
A new Firewall Threat Defense Virtual instance is added to the cluster.
If the configuration of the new Firewall Threat Defense Virtual instance fails (low probability) during the scale-out process, the failing
instance is terminated, and a new instance is launched and configured.
Scale-in
Scale-in removes a node from the cluster when both the configured scale-in threshold
and the total number of cluster instances exceed the minimum cluster size.
The following is the process of terminating a node in the cluster during
scale-in:
The Firewall Threat Defense
Virtual instance with the least CPU or memory usage is identified using VMSS
metrics.
If there is more than one instance with the same least utilization, then the
instance with the higher VM index in VMSS is chosen for scale-in.
Any new connections to this instance are disabled by appropriate
configuration and policies.
The instance is de-registered from smart licensing (applicable for BYOL).
The instance is terminated.
Azure Functions (Function App)
The Function application enables the Firewall Threat Defense
Virtual cluster and registers it with the management center. It also helps you select a
hosting plan for Firewall Threat Defense
Virtual clustering with autoscale deployment.
The following two types of hosting plans are offered:
Consumption
This is the default hosting plan for Firewall Threat Defense
Virtual clustering with autoscale.
This plan allows the Function app to connect to the Firewall Threat Defense
Virtual instances by opening the SSH port to the Azure data center IP
addresses of the region.
Premium
You can select this hosting plan for the Function app during
deployment.
This plan supports adding a Network Address Translation (NAT) gateway
to the Function app to control the outbound IP address of the
Function app. This plan allows SSH access to Firewall Threat Defense
Virtual instances only from a fixed IP address of the NAT gateway thereby
offering enhanced security.
For more information about overview on auto scale solution components, refer to Auto Scale Solution Components in Cisco Secure Firewall
Threat Defense Virtual Getting Started Guide.
Deployment and infrastructure templates on GitHub
Firewall Threat Defense
Virtual Clustering with Autoscale Solution Templates
Cisco provides Azure Resource Manager (ARM) templates and scripts for deploying an auto-scaling group of Firewall Threat Defense
Virtual cluster using several Azure services, including Function App, Logic App, and auto-scaling groups.
The autoscale solution for Firewall Threat Defense
Virtual cluster is an ARM template-based deployment that provides:
Completely automated Firewall Threat Defense
Virtual instance registration and de-registration with the management center using the Function App.
Automatin application of NAT policy, access control policy, and routes, to the scaled-out threat defense virtual instances.
Support for GWLB and NLB load balancers.
Works only with the management center; the device manager is not supported.
Azure Resource Manager (ARM) templates
Two sets of templates are provided for autoscale solutions based on the (NLB or GWLB) load balancer you are using in Azure
for the cluster.
Autoscale solution template for Firewall Threat Defense
Virtual clustering using NLB: azure_ftdv_nlb_cluster.json.json available in the folder arm-templates.
Autoscale solution template for Firewall Threat Defense
Virtual clustering using GWLB: azure_ftdv_gwlb_cluster.json available in the folder arm-templates.
Setting up Azure infrastructure and configuration
Function app to enable cluster on Firewall Threat Defense
Virtual instances: cluster_functions.zip.
Logic App code for the Firewall Threat Defense
Virtual deployment, scale-in and scale-out workflow: logic_app.txt.
Input parameters
The following table defines the template parameters and provides an example. Once you decide on these values, you can use
these parameters to create the
Firewall Threat Defense
Virtual when you deploy the Azure Resource Manager (ARM) template into your Azure subscription. In the clustering with autoscale solution with GWLB for Azure, networking infrastructure is also created due to which additional
input parameters have to be configured in the template. The parameter descriptions are self-explanatory.
Table 3. Template Parameters
Parameter Name
Allowed Values/Type
Description
Resource Creation Type
resourceNamePrefix
String* (3-10 characters)
All the resources are created with name containing this prefix.
Note: Use only lowercase letters.
Example:
ftdv
New
virtualNetworkRg
String
The virtual network resource group name.
Example: cisco-virtualnet-rg
Existing
virtualNetworkName
String
The virtual network name (already created).
Example: cisco-virtualnet
Existing
virtualNetworkCidr
CIDR format
x.x.x.x/y
CIDR of Virtual Network (already created)
Existing
mgmtSubnet
String
The management subnet name (already created).
Example: cisco-mgmt-subnet
Existing
dataSubnet
String
The data subnet name (already created)
Example: cisco-data-subnet
cclSubnet
String
The cluster control link subnet name.
Example: cisco-ccl-subnet
cclSubnetStartAddr
String
The starting range of CCL subnet IP address.
Example: 3.4.5.6
cclSubnetEndAddr
String
The ending range of CCL subnet IP address.
Example: 5.6.7.8
gwlbIP
String
GWLB is created in existing data subnet.
Example: 10.0.2.4
dataNetworkGatewayIp
String
The gateway IP address of the data subnet.
Example: 10.0.2.7
outsideSecurityZoneName
String
The security zone object Name created in the management center
Example: outside-sz
TDvmManagementUserName
String
TDv management administrator username.
You are not allowed provide 'admin' as the username.
diagSubnet
String
The diagnostic subnet name (already created).
Example: cisco-diag-subnet
Existing
insideSubnet
String
The inside Subnet name (already created).
Example: cisco-inside-subnet
Existing
internalLbIp
String
The internal load balancer IP address for the inside subnet (already created).
Example: 1.2.3.4
Existing
insideNetworkGatewayIp
String
The inside subnet gateway IP address (already created).
Existing
outsideSubnet
String
The outside subnet name (already created).
Example: cisco-outside-subnet
Existing
outsideNetworkGatewayIp
String
The outside subnet gateway IP (already created).
Existing
deviceGroupName
String
Device group in Firewall Management
Center (already created)
Existing
insideZoneName
String
Inside Zone name in the Firewall Management
Center (already created)
Existing
outsideZoneName
String
Outside Zone name in the Firewall Management
Center (already created)
Existing
softwareVersion
String
The
Firewall Threat Defense
Virtual Version (selected from drop-down list during deployment).
Existing
vmSize
String
Size of
Firewall Threat Defense
Virtual instance (selected from drop-down list during deployment).
The Firewall Threat Defense
Virtual VM management administrator user name.
This cannot be ‘admin’. See Azure for VM administrator user name guidelines.
New
tdVmManagementUserPassword
String*
Password for the Firewall Threat Defense
Virtual VM management administrator user.
Passwords must be 12 to 72 characters long, and must have: lowercase, uppercase, numbers, and special characters; and must
have no more than 2 repeating characters.
Note
There is no compliance check for this in the template.
New
ftdAdminUserPassword
String
Firewall Threat Defense
Virtual Admin user password.
Note
The criteria mentioned for the TDvmManagementUserPassword parameter is applicable to this parameter also.
fmcIpAddress
String
x.x.x.x
The public IP address of the Firewall Management
Center (already created)
Existing
fmcUserName
String
Firewall Management
Center user name, with administrative privileges (already created)
Existing
fmcPassword
String
Firewall Management
Center password for above Firewall Management
Center user name (already created)
Existing
policyName
String
Security Policy created in the Firewall Management
Center (already created)
Existing
clusterGroupName
String
The name of the cluster group to be used while registering the
threat defense device to the management center .
Example: tdv-cluster
healthCheckPortNumber
String
The health check port number used while creating the health probe in the Gateway Load balancer.
Example: 8080
functionHostingPlan
String
Function deployment hosting plan (consumption uses the consumption hosting plan, premium: uses the premium hosting plan).
Default: consumption
functionAppSubnet
String
The function app subnet name (already created).
Example: tdv-fapp-subnet
functionAppSubnetCIDR
String
The CIDR of the function app subnet (already created).
Example: 10.0.4.0/27
scalingMetricsList
String
The metrics used in determining the scaling the scaling decision.
Allowed: CPU & MEMORY
scalingPolicy
POLICY-1 / POLICY-2
POLICY-1 : Scale-Out will be triggered when the average load of any
Firewall Threat Defense
Virtual goes beyond the Scale Out threshold for the configured duration.
POLICY-2 : Scale-Out will be triggered when average load of all the
Firewall Threat Defense
Virtual devices in the VMSS goes beyond the Scale Out threshold for the configured duration.
In both cases Scale-In logic remains the same: Scale-In will be triggered when average load of all the
Firewall Threat Defense
Virtual devices comes below the Scale In threshold for the configured duration.
N/A
scalingMetricsList
String
Metrics used in making the scaling decision.
Allowed: CPU , MEMORY
Default: CPU
N/A
cpuScaleInThreshold
String
The scale-in threshold in percentage for CPU metrics .
Default: 10
When the
Firewall Threat Defense
Virtual metric goes below this value the scale-in will be triggered.
The minimum
Firewall Threat Defense
Virtual instances available in the scale set at any given time.
Example: 2
N/A
maxFtdCount
Integer
The maximum
Firewall Threat Defense
Virtual instances allowed in the Scale set.
Example: 10
Note
This number is restricted by the Firewall Management
Center capacity.
The Auto Scale logic will not check the range of this variable, hence fill this carefully.
N/A
metricsAverageDuration
Integer
Select from the drop-down.
This number represents the time (in minutes) over which the metrics are averaged out.
If the value of this variable is 5 (i.e. 5min) when the Auto Scale Manager is scheduled, it will check the past 5 minutes
average of metrics and based on this, it will make a scaling decision.
Note
Only numbers 1, 5, 15, and 30 are valid due to Azure limitations.
N/A
initDeploymentMode
BULK / STEP
Primarily applicable for the first deployment, or when the Scale Set does not contain any
Firewall Threat Defense
Virtual instances.
BULK: The Auto Scale Manager will try to deploy ' minFtdCount
' number of
Firewall Threat Defense
Virtual instances in parallel at one time.
Note
The launch is in parallel, but registering with the Firewall Management
Center is sequential due to Firewall Management
Center limitations.
STEP: The Auto Scale Manager will deploy the ' minFtdCount
' number of
Firewall Threat Defense
Virtual devices one by one at each scheduled interval.
Note
The STEP option will take a long time for the ‘minFtdCount’ number of instances to be launched and configured with the Firewall Management
Center and become operational, but useful in debugging.
The BULK option takes same amount of time to launch all ‘minFtdCount’ number of Firewall Threat Defense
Virtual as one Firewall Threat Defense
Virtual launch takes (because it runs in parallel), but the Firewall Management
Center registration is sequential.
The total time to deploy ‘minFtdCount’ number of Firewall Threat Defense Virtual = (time to launch One Firewall Threat Defense Virtual + time to register/configure one Firewall Threat Defense Virtual * minFtdCount ).
*Azure has restrictions on the naming convention for new resources. Review the limitations or simply use all lowercase letters.
Do not use spaces or any other special characters .
Firewall Threat Defense
Virtual Cluster with autoscale deployment - process and resources
Firewall Threat Defense
Virtual cluster with autoscale deployment process on Azure includes these steps:
Deploy the ARM template.
Build and deploy the clustering function.
Update and enable the Logic application.
The following resources are created within a resource group when you deploy Firewall Threat Defense
Virtual cluster with autoscale in Azure using the ARM template for Sandwich Topology (NLB) - azure_ftdv_nlb_cluster_autoscale.json
Virtual Machine Scale Set (VMSS)
External load balancer
Internal load balancer
Azure Function App
Logic App
Security groups for data and management interfaces
The following resources are created within a resource group when you deploy Firewall Threat Defense
Virtual cluster with autoscale in Azure using the ARM template for GWLB - azure_ftdv_gwlb_cluster_autoscale.json
Virtual Machine (VM) or Virtual Machine Scale Set (VMSS)
Gateway Load Balancer (GWLB)
Azure Function App
Logic App
Networking Infrastructure
Security groups and other miscellaneous components needed for deployment.
Deploy the Firewall Threat Defense
Virtual cluster with autoscale solution
This task deploys the Firewall Threat Defense
Virtual clustering with autoscale solution on Azure to provide automated scaling capabilities for network security infrastructure
using Azure Resource Manager templates.
Based on the topology—Sandwich (NLB) or Gateway Load Balancer (GWLB) use case—you must download and configure the appropriate
ARM template to deploy the Firewall Threat Defense
Virtual clustering with autoscale solution on Azure.
Before you begin
Download the Deployment Package from GitHub
The Firewall Threat Defense
Virtual clustering autoscale with NLB solution for Azure is an Azure Resource Manager (ARM) template-based deployment which makes
use of the serverless infrastructure provided by Azure (Logic App, Azure Functions, Load Balancers, Virtual Machine Scale
Set, and so on).
The Firewall Threat Defense
Virtual clustering autoscale with GWLB solution for Azure is an ARM template-based deployment that creates the GWLB, networking infrastructure,
threat defense virtual auto scaling group, serverless components, and other required resources.
The deployment procedures for both solutions are similar.
Download the files required to launch the Firewall Threat Defense
Virtual clustering with autoscale solution for Azure.
Deployment scripts and templates for your version are available in the GitHub repository.
Follow these steps to deploy the Firewall Threat Defense
Virtual cluster with autoscale solution:
Procedure
Step 1
Log in to the Microsoft Azure portal (https://portal.azure.com) using your Microsoft account username and password.
Step 2
Click Resource groups from the menu of services to access the Resource Groups blade. You will see all the resource groups in your subscription listed in the blade. Create a new resource group or select
an existing, empty resource group. For example, threat defense virtual_AutoScale.
Step 3
Click Create a resource (+) to create a new resource for template deployment.
The Create Resource Group blade appears.
Step 4
Click Virtual Network from the menu of services to access the Virtual network blade. Create a virtual network with subnets.
For GWLB deployment, create virtual network with management, data, CCL subnets, and the function app.
For NLB deployment, create virtual network with management, inside, outside, CCL subnets and the function app.
Step 5
In Search the Marketplace, type Template deployment (deploy using custom templates), and then press Enter.
Step 6
Click Create. There are several options for creating a template. Choose Build your own template in editor.
Step 7
In the Edit template window, delete all the default content and copy the contents from the updated azure_ftdv_gwlb_cluster_custom_image.json or azure_ftdv_nlb_cluster_custom_image.json (depending on the type of autoscale solution you are deploying on Azure) and click Save. Or Click Load file to browse and upload this file from your computer.
Step 8
In the parameter field sections, fill all the parameters. Refer to Input Parameters for details about each parameter, then click Review+Create.
Step 9
When a template deployment is successful, it creates all the required resources for the threat defense virtual auto scale
for Azure solution. See the resources in the following figure. The Type column describes each resource, including the Logic App, VMSS, Load Balancers, Public IP address, etc.
Deploy the cluster autoscale Azure Functions App to enable automatic scaling functionality for your Azure infrastructure.
When you deploy the ARM template, Azure creates the function app with the name <resourceNamePrefix>-function-app.
Procedure
Step 1
Go to the function app you created when you deployed the ARM template and do the following tasks:
Run the following command from your local computer to deploy the cluster autoscale Azure Functions to the Function app.
az functionapp deployment source config-zip -g <Resource Group Name>
-n <Function App Name> --src  <cluster_functions.zip> --build-remote true
Step 2
After the deployment of the Azure Functions, you can view the uploaded Functions in the overview section of the function application.
Update the Azure logic app
Configure the Logic App with the necessary information to function as the autoscale orchestrator for the autoscale functionality.
The Logic App acts as the orchestrator for the autoscale functionality. The Azure Resource Manager (ARM) template creates
a skeleton Logic App, which you then need to update manually to provide the information necessary for it to function as the
autoscale orchestrator.
Procedure
Step 1
From the repository, retrieve the file LogicApp.txt to the local system and edit as shown below.
Important
Read and understand all of these steps before proceeding.
These manual steps are not automated in the ARM template so that only the Logic App can be upgraded independently in the future.
Find and replace all the occurrences of "SUBSCRIPTION_ID" with your SUBSCRIPTION ID information.
Find and replace all the occurrences of "RG_NAME" with your resource group NAME.
Find and replace all of the occurrences of "FUNCTIONAPPNAME" to your function app NAME.
The following example shows a few of these lines in the LogicApp.txt file:
(Optional) Edit the trigger interval, or leave the default value (5). This is the time interval at which the Autoscale functionality
is periodically triggered. The following example shows these lines in the LogicApp.txt file:
(Optional) Edit the time to drain, or leave the default value (5). This is the time interval to drain existing connections from the Firewall Threat Defense Virtual before deleting the device during the Scale-In operation. The following example shows these lines in the LogicApp.txt file:
(Optional) Edit the cooldown time, or leave the default value (10). This is the time to perform no action after the Scale-Out is complete.
The following example shows these lines in the LogicApp.txt file:
You can also perform these steps from the Azure portal. Consult the Azure documentation for more information.
Step 2
Go to the Logic App code view, delete the default contents, paste the contents from the edited LogicApp.txt file, and click Save.
Figure 9. Logic app code view
Step 3
When you save the Logic App, it is in a 'Disabled' state. Click Enable when you want to start the autoscale manager.
Figure 10. Enable logic app
Step 4
The tasks start running once enabled. Click the 'Running' status to see the activity.
Figure 11. Logic app running status
Step 5
All deployment-related steps are complete once the Logic App starts. Verify in the virtual machine scale set (VMSS) that Firewall Threat Defense Virtual instances are being created.
In this example, three Firewall Threat Defense Virtual instances are launched because 'minFtdCount' was set to '3' and 'initDeploymentMode' was set to 'BULK' in the ARM template deployment.
Add the cluster to the Management Center (manual deployment)
This task registers a manually deployed cluster with the Firewall Management
Center to enable centralized management and configuration of the cluster units.
Use this procedure to add the cluster to the Firewall Management
Center if you manually deployed the cluster. If you used a template, the cluster will auto-register on the Firewall Management
Center.
Add one of the cluster units as a new device to the Firewall Management
Center; the Firewall Management
Center automatically detects all other cluster members.
Before you begin
All cluster units must be in a successfully formed cluster before adding the cluster to the Firewall Management
Center. You should also check which unit is the control unit. Use the Firewall Threat Defenseshow cluster info command.
Follow these steps to add the cluster to the Management Center for manual deployment:
Procedure
Step 1
In the Firewall Management
Center, choose Devices > Device Management, and then choose Add > Add Device to add the control unit using the unit's management IP address.
Figure 13. Add device
In the Host field, enter the IP address or hostname of the control unit.
We recommend adding the control unit for the best performance, but you can add any unit of the cluster.
If you used a NAT ID during device setup, you may not need to enter this field.
In the Display Name field, enter a name for the control unit as you want it to display in the Firewall Management
Center.
This display name is not for the cluster; it is only for the control unit you are adding. You can later change the name of
other cluster members and the cluster display name.
In the Registration Key field, enter the same registration key that you used during device setup. The registration key is a one-time-use shared secret.
(Optional) Add the device to a device Group.
Choose an initial Access Control Policy to deploy to the device upon registration, or create a new policy.
If you create a new policy, you create a basic policy only. You can later customize the policy as needed.
Choose licenses to apply to the device.
If you used a NAT ID during device setup, expand the Advanced section and enter the same NAT ID in the Unique NAT ID field.
Select the Transfer Packets check box to allow the device to transfer event metadata and packet data associated with intrusion events to the Firewall Management
Center.
This option is enabled by default. The transferred packet data is used for intrusion-event analysis. It does not necessarily
contain the complete original packet as transmitted on the wire or the complete traffic session. For intrusion events generated
by Snort inspection, the device can transfer only the Protocol Data Unit (PDU) or packet content associated with the intrusion-rule
match.
If you disable this option, the device sends only event information to the Firewall Management
Center; packet data is not sent.
Click Register.
The Firewall Management
Center identifies and registers the control unit, and then registers all data units. If the control unit does not successfully register,
then the cluster is not added. A registration failure can occur if the cluster was not up, or because of other connectivity
issues. In this case, we recommend that you try re-adding the cluster unit.
The cluster name shows on the Devices > Device Management page; expand the cluster to see the cluster units.
Figure 14. Cluster management
A unit that is currently registering shows the loading icon.
Figure 15. Node registration
You can monitor cluster unit registration by clicking the Notifications icon and choosing Tasks. The Firewall Management
Center updates the Cluster Registration task as each unit registers. If any units fail to register, see Reconcile Cluster Nodes.
Step 2
Configure device-specific settings by clicking the Edit () for the cluster.
Most configuration can be applied to the cluster as a whole, and not nodes in
the cluster. For example, you can change the display name per node, but you
can only configure interfaces for the whole cluster.
Step 3
On the Devices > Device Management and then choose Add, Cluster screen, you see General, License, System, and Health settings.
See these cluster-specific items:
General > Name—Change the cluster display name by clicking the Edit ().
Then set the Name field.
General > Cluster Live Status—Click the View link to open the Cluster Status dialog box.
The Cluster Status dialog box also lets you retry data unit registration by clicking Reconcile.You can also ping the cluster control link from a node. See Perform a ping on the cluster control link.
General > Troubleshoot—You can generate and download troubleshooting logs, and you can view cluster CLIs. See Troubleshoot the cluster.
Figure 16. Troubleshoot
License—Click Edit () to set license entitlements.
Step 4
On the Devices > Device Management and then click Add > Device, you can choose each member in the cluster from the top right drop-down menu and configure these settings.
General > Name—Change the cluster member display name by clicking the Edit ().
Then set the Name field.
Management > Host—If you change the management IP address in the device configuration, you must match the new address in the Firewall Management
Center so that it can reach the device on the network; edit the Host address in the Management area.
Edit cluster health monitor settings
This task allows you to modify cluster health monitor settings to control how cluster nodes monitor system health and automatically
rejoin the cluster after failures.
The Cluster Health Monitor Settings section of the Cluster page displays the settings for monitoring cluster node health. You can monitor any port-channel ID, any single physical interface
ID, and the Snort and disk-full processes. Health monitoring is not performed on VLAN subinterfaces or virtual interfaces
such as VNIs or BVIs. You cannot configure monitoring for the cluster control link. It is always monitored.
When a topology change occurs (such as adding or removing a data interface, enabling or disabling an interface on the node
or the switch, or adding an additional switch to form a VSS or vPC or VNet) you should disable the system health check feature.
Also, disable interface monitoring for any interfaces that are disabled. When the topology change is complete, and the configuration
change is synced to all nodes, you can re-enable the system health check feature and monitored interfaces.
Procedure
Step 1
Choose Devices > Device Management.
Step 2
Next to the cluster you want to modify, click Edit ().
Step 3
Click Cluster.
Step 4
In the Cluster Health Monitor Settings section, click Edit ().
Step 5
Disable the system health check by clicking the Health Check slider.
Figure 17. Disable the system health check
When any topology changes occur (such as adding or removing a data interface, enabling or disabling an interface on the node
or the switch, or adding an additional switch to form a VSS or vPC or VNet) you should disable the system health check feature
and also disable interface monitoring for the disabled interfaces. When the topology change is complete, and the configuration
change is synced to all nodes, you can re-enable the system health check feature and monitored interfaces.
Step 6
Configure the hold time and interface debounce time.
Hold Time—Set the hold time to determine the amount of time between node heartbeat status messages, between 0.3 and 45 seconds. The
default is 3 seconds.
Interface Debounce Time—Set the debounce time between 300 and 9000 ms. The default is 500 ms. Lower values allow for faster detection of interface
failures. Note that configuring a lower debounce time increases the chances of false-positives. When an interface status update
occurs, the node waits the specified number of milliseconds before marking the interface as failed and removing the node from
the cluster. If an EtherChannel transitions from a down state to an up state, such as after the switch reloads or enables
an EtherChannel, a longer debounce time can prevent the interface from appearing failed on a cluster node if another cluster
node bundles the ports more quickly.
Step 7
Customize the auto-rejoin cluster settings after a health check failure.
Figure 18. Configure Auto-Rejoin settings
Set values for the Cluster Interface, Data Interface, and System (internal failures include: application sync timeout; inconsistent application statuses; and so on):
Attempts—Sets the number of rejoin attempts, between -1 and 65535. 0 disables auto-rejoining. The default for the Cluster Interface is -1 (unlimited). The default for the Data Interface and System is 3.
Interval Between Attempts—Defines the interval duration in minutes between rejoin attempts, between 2 and 60. The default value is 5 minutes. The maximum
total time that the node attempts to rejoin the cluster is limited to 14400 minutes (10 days) from the time of last failure.
Interval Variation—Defines if the interval duration increases. Set the value between 1 and 3: 1 (no change); 2 (2 x the previous duration), or 3 (3 x the previous duration). For example, if you set the interval duration to 5 minutes, and set the variation to 2, then
the first attempt is after 5 minutes; the 2nd attempt is 10 minutes (2 x 5); the 3rd attempt 20 minutes (2 x 10), and so on.
The default value is 1 for the Cluster Interface and 2 for the Data Interface and System.
Step 8
Configure monitored interfaces by moving interfaces in the Monitored Interfaces or Unmonitored Interfaces window. You can also check or uncheck Enable Service Application Monitoring to enable or disable monitoring of the Snort and disk-full processes.
Figure 19. Configure monitored interfaces
The interface health check monitors for link failures. If all physical ports for a given logical interface fail on a particular
node, but there are active ports under the same logical interface on other nodes, then the node is removed from the cluster.
The time required to remove a member from the cluster depends on the type of interface and whether the node is established
or is joining the cluster. By default, health check is enabled for all interfaces and the Snort and disk-full processes.
You might want to disable health monitoring of non-essential interfaces.
When any topology changes occur (such as adding or removing a data interface, enabling or disabling an interface on the node
or the switch, or adding an additional switch to form a VSS or vPC or VNet) you should disable the system health check feature
and also disable interface monitoring for the disabled interfaces. When the topology change is complete, and the configuration
change is synced to all nodes, you can re-enable the system health check feature and monitored interfaces.
Step 9
Click Save.
Deploy configuration changes.
Manage cluster nodes
Explains how to add, remove, and configure cluster nodes in your deployment.
Disable clustering
Disable clustering to temporarily deactivate a node in preparation for deleting the node or for maintenance purposes.
You may want to deactivate a node to delete it or for temporary maintenance. This procedure temporarily deactivates a node,
but the node will still appear in the Firewall Management
Center device list. When a node becomes inactive, all data interfaces are shut down.
Note
Do not power off the node without first disabling clustering.
Procedure
Step 1
For the unit you want to disable, choose Devices > Device Management, click the More (), and choose Disable Node Clustering.
Step 2
Confirm that you want to disable clustering on the node.
The node will show (Disabled) next to its name in the Devices > Device Management list.
If a node was removed from the cluster, for example for a failed interface or if you manually disabled clustering, you must
manually rejoin the cluster. Make sure the failure is resolved before you try to rejoin the cluster. See Rejoining the Cluster for more information about why a node can be removed from a cluster.
Procedure
Step 1
For the unit you want to reactivate, choose Devices > Device Management, click the More (), and choose Enable Node Clustering.
Step 2
Confirm that you want to enable clustering on the node.
Reconcile Cluster Nodes
If a cluster node fails to register, you can reconcile the cluster membership from
the device to the Firewall Management
Center. For example, a data node might fail to register if the Firewall Management
Center is occupied with certain processes, or if there is a network issue.
Procedure
Step 1
Choose Devices > Device ManagementMore () for the cluster, and then choose Cluster Live Status to open the Cluster Status dialog box.
Step 2
Click Reconcile All.
Figure 20. Reconcile All
Unregister the cluster or nodes and register with a new Firewall Management
Center
This task allows you to move cluster nodes from one management center to another by safely removing them from their current
management center and re-registering them with a new one.
You can unregister the cluster from the Firewall Management
Center, which keeps the cluster intact. You might want to unregister the cluster if you want to add the cluster to a new Firewall Management
Center.
You can also unregister a node from the Firewall Management
Center without breaking the node from the cluster. Although the node is not visible in the Firewall Management
Center, it is still part of the cluster, and it will continue to pass traffic and could even become the control node. You cannot
unregister the current control node. You might want to unregister the node if it is no longer reachable from the Firewall Management
Center, but you still want to keep it as part of the cluster while you troubleshoot management connectivity.
Unregistering a cluster:
Severs all communication between the Firewall Management
Center and the cluster.
Removes the cluster from the Device Management page.
Returns the cluster to local time management if the cluster's platform settings policy is configured to receive time from
the Firewall Management
Center using NTP.
Leaves the configuration intact, so the cluster continues to process traffic.
Policies, such as NAT and VPN, ACLs, and the interface configurations remain intact.
Registering the cluster again to the same or a different Firewall Management
Center causes the configuration to be removed, so the cluster will stop processing traffic at that point; the cluster configuration
remains intact so you can add the cluster as a whole. You can choose an access control policy at registration, but you will
have to re-apply other policies after registration and then deploy the configuration before it will process traffic again.
Before you begin
This procedure requires CLI access to one of the nodes.
Procedure
Step 1
Choose Devices > Device Management, click More () for the cluster or node, and choose Unregister.
Step 2
You are prompted to unregister the cluster or node;
click Yes.
Step 3
You can register the cluster with a new (or the same) Firewall Management
Center by adding one of the cluster members as a new device.
Add one of the cluster nodes as a device. The system will discover the remaining nodes.
Connect to the CLI of a cluster node, and identify the new Firewall Management
Center using the configure manager add command.
Choose Devices > Device Management, and then click Add Device.
You can monitor the cluster in the Firewall Management
Center and at the Firewall Threat Defense CLI.
Monitor cluster status through these methods:
Cluster Status dialog box, which is available from the Devices > Device Management, More () icon or from the Devices > Device Management, click Add, choose the Cluster page General area Cluster Live Status link.
Figure 21. Cluster status
The Control node has a graphic indicator identifying its role.
Cluster member Status includes these states:
In Sync—The node is registered with the Firewall Management
Center.
Pending Registration—The node is part of the cluster, but has not yet registered with the Firewall Management
Center. If a node fails to register, you can retry registration by clicking Reconcile All.
Clustering is disabled—The node is registered with the Firewall Management
Center, but is an inactive member of the cluster. The clustering configuration remains intact if you intend to later re-enable it,
or you can delete the node from the cluster.
Joining cluster...—The node is joining the cluster on the chassis, but has not completed joining. After it joins, it will
register with the Firewall Management
Center.
For each node, you can view the Summary or the History.
Figure 22. Node summary
Figure 23. Node history
System () > Tasks page.
The Tasks page shows updates of the Cluster Registration task as each node registers.
Devices > Device Management and then click Add > Device cluster_name.
When you expand the cluster on the devices listing page, you can see all member nodes, including the control node shown with
its role next to the IP address. For nodes that are still registering, you can see the loading icon.
show cluster {access-list [acl_name] | conn [count] | cpu [usage] | history | interface-mode | memory | resource usage | service-policy | traffic | xlate count}
To view aggregated data for the entire cluster or other information, use the show cluster command.
show cluster info [auto-join | clients | conn-distribution | flow-mobility counters | goid [options] | health | incompatible-config | loadbalance | old-members | packet-distribution | trace [options] | transport { asp | cp}]
To view cluster information, use the show cluster info command.
Cluster Health Monitor Dashboard
When a Firewall Threat Defense is the control node of a cluster, the Firewall Management
Center collects various metrics periodically from the device metric data collector.
The cluster health monitor is comprised of these components:
Overview dashboard: Displays information about the cluster topology, cluster statistics, and metric charts:
The topology section displays a cluster's live status, the health of individual threat defense, threat defense node type (control
node or data node), and the status of the device. The status of the device could be Disabled (when the device leaves the cluster), Added out of box (in a public cloud cluster, the additional nodes that do not belong to the Firewall Management
Center), or Normal (ideal state of the node).
The cluster statistics section displays current metrics of the cluster with respect to the CPU usage, memory usage, input
rate, output rate, active connections, and NAT translations.
Note
The CPU and memory metrics display the individual average of the data plane and snort usage.
The metric charts, namely, CPU Usage, Memory Usage, Throughput, and Connections, diagrammatically display the statistics of
the cluster over the specified time period.
Load Distribution dashboard: Displays load distribution across the cluster nodes in two widgets:
The Distribution widget displays the average packet and connection distribution over the time range across the cluster nodes.
This data depicts how the load is being distributed by the nodes. Using this widget, you can easily identify any abnormalities
in the load distribution and rectify it.
The Node Statistics widget displays the node level metrics in table format. It displays metric data on CPU usage, memory usage,
input rate, output rate, active connections, and NAT translations across the cluster nodes. This table view enables you to
correlate data and easily identify any discrepancies.
Member Performance dashboard: Displays current metrics of the cluster nodes. You can use the selector to filter the nodes
and view the details of a specific node. The metric data include CPU usage, memory usage, input rate, output rate, active
connections, and NAT translations.
CCL dashboard: Displays, graphically, the cluster control link data namely, the input, and output rate.
Troubleshooting and Links: Provides convenient links to frequently used troubleshooting topics and procedures.
Time range: An adjustable time window to constrain the information that appears in the various cluster metrics dashboards
and widgets.
Custom Dashboard: Displays data on both cluster-wide metrics and node-level metrics. However, node selection only applies
for the threat defense metrics and not for the entire cluster to which the node belongs.
Viewing Cluster Health
The cluster health monitor provides a detailed view of the health status of a cluster and its nodes. This cluster health monitor
provides health status and trends of the cluster in an array of dashboards.
Before you begin
Ensure you have created a cluster from one or more devices in the Firewall Management
Center.
Follow these steps to view the cluster health monitor:
Procedure
Step 1
Choose System () > Health > Monitor.
Use the Monitoring navigation pane to access node-specific health monitors.
Step 2
In the device list, click Expand() and Collapse () to expand and collapse the list of managed cluster devices.
Step 3
Click on the cluster name to view the cluster health statistics.
The cluster monitor reports health and performance metrics in several predefined dashboards by default. The metrics dashboards
include:
Overview: Highlights key metrics from the other predefined dashboards, including its nodes, CPU, memory, input and output
rates, connection statistics, and NAT translation information.
Load Distribution: Traffic and packet distribution across the cluster nodes.
Member Performance: Node-level statistics on CPU usage, memory usage, input throughput, output throughput, active connection,
and NAT translation.
CCL: Interface status and aggregate traffic statistics.
Configure the time range from the drop-down in the upper-right corner.
The time range can reflect a period as short as the last hour (the default) or as long as two weeks. Select Custom from the drop-down to configure a custom start and end date.
Click the refresh icon to set auto refresh to 5 minutes or to toggle off auto refresh.
Step 5
Click on deployment icon for a deployment overlay on the trend graph, with respect to the selected time range.
The deployment icon indicates the number of deployments during the selected time-range. A vertical band indicates the deployment
start and end time. For multiple deployments, multiple bands/lines appear. Click on the icon on top of the dotted line to
view the deployment details.
Step 6
View the Health Alerts for the node in the alert notification at the top of page, directly to the right of the device name.
Hover your pointer over the Health Alerts to view the health summary of the node. The popup window shows a truncated summary of the top five health alerts. Click on
the popup to open a detailed view of the health alert summary.
Step 7
View device monitor health and performance metrics in several predefined dashboards.
The metrics dashboards include:
Overview: Highlights key metrics from the other predefined dashboards, including CPU, memory, interfaces, connection statistics;
plus disk usage and critical process information.
CPU: CPU utilization, including the CPU usage by process and by physical cores.
Memory: Device memory utilization, including data plane and Snort memory usage.
Interfaces: Interface status and aggregate traffic statistics.
Connections: Connection statistics (such as elephant flows, active connections, peak connections, and so on) and NAT translation
counts.
Snort: Statistics that are related to the Snort process.
ASP drops: Statistics related to the dropped packets against various reasons.
Click the plus sign Add New Dashboard() in the upper right corner of the health monitor to create a custom dashboard by building your own variable set from the available
metric groups.
For cluster-wide dashboard, choose Cluster metric group, and then choose the metric.
Cluster metrics
The cluster health monitor tracks statistics that are related to a cluster and its nodes, and aggregate of load distribution,
performance, and CCL traffic statistics.
Table 4. Cluster Metrics
Metric
Description
Format
CPU
Average of CPU metrics on the nodes of a cluster (individually for data plane and snort).
percentage
Memory
Average of memory metrics on the nodes of a cluster (individually for data plane and snort).
percentage
Data Throughput
Incoming and outgoing data traffic statistics for a cluster.
bytes
CCL Throughput
Incoming and outgoing CCL traffic statistics for a cluster.
bytes
Connections
Count of active connections in a cluster.
number
NAT Translations
Count of NAT translations for a cluster.
number
Distribution
Connection distribution count in the cluster for every second.
number
Packets
Packet distribution count in the cluster for every second.
number
Troubleshoot the cluster
Use these methods to troubleshoot the devices and clusters:
Use Logs to generates troubleshooting files for all nodes in the cluster. Use this option when you need one cluster-level collection
instead of generating troubleshooting files from each node separately.
Use CLI to run a predefined set of cluster diagnostic commands and displays the output. Use this option to check cluster configuration,
member state, cluster health, control-plane transport statistics, packet drops, interface status, CPU usage, memory buffers,
ARP entries, and reachability. The CLI option displays command output; it does not open an interactive CLI session.
Commands
show running-config cluster: Review the cluster group configuration, local unit, cluster interface, priority, health-check, auto-rejoin, and cLACP settings.
show cluster info: Confirm that clustering is enabled and identify the control node, member state, software version, serial number, CCL IP
address, CCL MAC address, and last join or leave state.
show cluster info health: Check unit, interface, service, and overall cluster health.
show cluster info transport cp: Review control-plane transport counters, including reliable and unreliable message counters, errors, retransmits, drops,
and buffer conditions.
show version: Capture platform, software, build, UUID, LSP, VDB, uptime, resource, and license context.
show asp drop: Identify accelerated security path packet or flow drop reasons and counters.
show counters: Review protocol, feature, and cluster CCL counters.
show arp: Verify ARP entries for interfaces that participate in cluster communication.
show int ip brief: Check interface IP addresses and administrative and line protocol status.
show blocks: Check buffer availability and failed allocations.
show cpu detailed: Check data path, control point, and total CPU usage.
show interface
ccl_interface: Review interface state, MTU, MAC address, IP address, traffic counters, errors, and drops for the cluster-related interface.
ping
ccl_ip
size
ccl_mtu
repeat 2: Test reachability to a cluster peer by using the packet size selected by the tool.
Use the CCL Ping when you need to test cluster control link connectivity between joined cluster nodes.
Troubleshooting files—If a node fails to join the cluster, a troubleshooting file is automatically generated. You can also
generate and download troubleshooting files from the Devices > Device Management and then choose Add, ClusterGeneral area.
You can also generate files from the Device Management page. Click More () and choose Troubleshoot Files.
CLI output—Choose Devices > Device Management and then choose Add, ClusterGeneral area, you can view a set of pre-defined CLI outputs that can help you troubleshoot the cluster. These commands are automatically
run for the cluster:
You can also enter any show command in the Command field.
Perform a ping on the cluster control link
When a node joins the cluster, it checks MTU compatibility by sending a ping to the control node with a packet size matching
the cluster control link MTU. If the initial ping fails, the node tries a ping using a smaller packet size (the MTU divided
by 2, then by 4, then by 8) until a ping succeeds. A notification is generated so you can fix the MTU mismatch on connecting
switches and try again. This tool lets you manually ping all nodes that have already joined the cluster in case you are having
cluster control link connectivity problems.
Procedure
Step 1
Choose Devices > Device Management, click the More () icon next to the cluster, and choose Cluster Live Status.
Figure 24. Cluster status
Step 2
Expand one of the nodes, and click CCL Ping.
Figure 25. CCL ping
The node sends a ping on the cluster control link to every other node using a packet size that matches the maximum MTU.
Upgrading the Cluster
Perform the following steps to upgrade a Firewall Threat Defense Virtual cluster:
Before you begin
Before
you upgrade a cluster in the public cloud, copy the target
version image to your cloud image repository and update the
image ID in the cluster deployment template (we actually
recommend replacing the existing template with a modified copy).
This ensures that after the upgrade, new instances — for
example, instances launched during cluster scaling — will use
the correct version. If the marketplace does not have the image
you need, such as when
the cluster has been patched, create a custom image
from a snapshot of a standalone Firewall Threat Defense Virtual instance running the correct version, with no
instance-specific (day 0) configurations.
Procedure
Step 1
Upload the target image version to the cloud image storage.
Step 2
Update the cloud instance template of the cluster with the updated target image
version.
Create a copy of the instance template with the target image
version.
Attach the newly created template to cluster instance group.
Step 3
Upload the target image version upgrade package to the Firewall Management
Center.
Step 4
Perform readiness check on the cluster that you want to upgrade.
Step 5
After successful readiness check, initiate installation of upgrade
package.
Step 6
The Firewall Management
Center upgrades the cluster nodes one at a time.
Step 7
The Firewall Management
Center displays a notification after successful upgrade of the cluster.
There is no change in the serial number and UUID of the instance after the
upgrade.
Cluster replacement upgrade procedure
Secure Firewall 7.6.4-69 or later 7.6.x versions, and 10.0.0 or later versions, use a new cluster interface addressing convention.
Existing clusters retain their legacy convention after an upgrade, but newly deployed members use the new convention and cannot
join.
To add capacity, build a replacement cluster and migrate traffic:
Procedure
Step 1
Keep the existing cluster serving traffic.
Step 2
Deploy the replacement cluster at its final size, using a new CCL subnet. Use Secure Firewall version 7.6.4-69 or later 7.6.x
versions, or version 10.0.0 or later. Keep all members on the same build, assign cluster-node-id tags from 1 to N, and enable metadata tags.
Step 3
Confirm the new cluster is healthy. Register it with the Management Center, apply the equivalent policy, and deploy.
Step 4
Edit the target group attributes before registering the replacement nodes. Under Target configuration, set Target failover strategy to No rebalance. Under Target deregistration management, set Deregistration delay (draining interval) to a value longer than your longest-lived flow. The maximum allowed value is 3600 seconds.
Note
Set target failover first: Target groups are created with Rebalance existing flows. With rebalancing enabled, deregistering
the old nodes moves their established flows to the remaining healthy targets in the replacement cluster. That cluster has
no state for those flows and drops them. No rebalance allows existing flows to drain.
Deregistration delay is a timer: The load balancer completes deregistration when the draining interval expires, regardless
of whether connections remain. A connection count of zero does not extend the interval.
Step 5
Register the new nodes with the existing target group, then deregister the old nodes. New traffic flows use the healthy replacement
nodes. Existing flows on the old nodes drain.
Step 6
After the old cluster’s connection count reaches zero, remove its targets and instances, then unregister it from the Management
Center.
Note
Check connections: Use the show conn count command on the old devices. The load balancer reports flows for the entire target group and cannot show which cluster owns
each flow while both are registered.
Rollback: Keep the old cluster until the replacement is validated. If needed, restore traffic to the old cluster before deleting
it.
Record the build: Note the replacement cluster’s release and build to select compatible versions for future nodes.
Observe the version boundary: Use version 7.6.4-69 or later 7.6.x versions, or version 10.0.0 or later versions. Older 7.6.4
builds use the legacy addressing scheme.
Plan for the overlap: Both clusters run concurrently. Confirm that Smart Licensing entitlements and vCPU quota cover the combined
node count.
Reference for Clustering
This section includes more information about how clustering operates.
Threat Defense Features and Clustering
Some Firewall Threat Defense features are not supported with clustering, and some are only supported on the
control unit. Other features might have caveats for proper usage.
Unsupported Features and Clustering
Note
To view FlexConfig features that are also not supported with clustering, for example WCCP inspection, see the ASA general operations configuration guide. FlexConfig lets you configure many ASA features that are not present in the Firewall Management
Center GUI.
Remote access VPN (SSL VPN and IPsec VPN)
Site-to-site VPN (Policy-based and route-based) is not supported in public clouds.
DHCP client, server, and proxy. DHCP relay is supported.
Virtual Tunnel Interfaces (VTIs)
High Availability
Integrated Routing and Bridging
Firewall Management
Center UCAPL/CC mode
Centralized features for clustering
These features are only supported on the control node, and are not scaled for the cluster.
Note
Traffic for centralized features is forwarded from member nodes to the control node over the cluster control link.
If you use the rebalancing feature, traffic for centralized features may be rebalanced to non-control nodes before the traffic
is classified as a centralized feature; if this occurs, the traffic is then sent back to the control node.
For centralized features, if the control node fails, all connections are dropped, and you have to re-establish the connections
on the new control node.
Note
To view FlexConfig features that are also centralized with clustering, for example RADIUS inspection, see the ASA general operations configuration guide. FlexConfig lets you configure many ASA features that are not present in the Firewall Management
Center GUI.
These application inspections are supported:
DCERPC and ESMTP
NetBIOS and PPTP
RSH
SQLNET and SUNRPC
TFTP
XDMCP
Static route monitoring
Site-to-site VPN
IGMP multicast control plane protocol processing (data plane forwarding is distributed across the cluster)
PIM multicast control plane protocol processing (data plane forwarding is distributed across the cluster)
Dynamic routing (Spanned EtherChannel mode only)
Cisco Trustsec and clustering
Only the control node learns security group tag (SGT) information. The control node then populates the SGT to data nodes,
and data nodes can make a match decision for SGT based on the security policy.
Connection settings and clustering
Connection limits are enforced cluster-wide. Each node has an
estimate of the cluster-wide counter values based on broadcast messages. Due to
efficiency considerations, the configured connection limit across the cluster
might not be enforced exactly at the limit number. Each node may overestimate or
underestimate the cluster-wide counter value at any given time. However, the
information will get updated over time in a load-balanced cluster.
Dynamic Routing and Clustering
In Individual interface mode, ECMP is used to load balance traffic between multiple equal-cost paths. External routers can
discover multiple paths to destinations through different cluster nodes.
Router A learns that there are 4 equal-cost paths to Router B, each through a node. ECMP is used to load balance traffic between
the 4 paths. Each node picks a different router ID when communicating with external routers.
You must configure a cluster pool for the router ID so that each node has a separate router ID.
FTP and Clustering
If FTP data channel and control channel flows are owned by
different cluster members, then the data channel owner will periodically send
idle timeout updates to the control channel owner and update the idle timeout
value. However, if the control flow owner is reloaded, and the control flow is
re-hosted, the parent/child flow relationship will not longer be maintained;
the control flow idle timeout will not be updated.
NAT and Clustering
For NAT usage, see the following limitations.
NAT can affect the overall throughput of the cluster. Inbound and outbound NAT packets can be sent to different Firewall Threat Defenses in the cluster, because the load balancing algorithm relies on IP addresses and ports, and NAT causes inbound and outbound
packets to have different IP addresses and/or ports. When a packet arrives at the Firewall Threat Defense that is not the NAT owner, it is forwarded over the cluster control link to the owner, causing large amounts of traffic on
the cluster control link. Note that the receiving node does not create a forwarding flow to the owner, because the NAT owner
may not end up creating a connection for the packet depending on the results of security and policy checks.
If you still want to use NAT in clustering, then consider the
following guidelines:
No Proxy ARP—For Individual interfaces, a proxy ARP
reply is never sent for mapped addresses. This prevents the adjacent
router from maintaining a peer relationship with an ASA that may no
longer be in the cluster. The upstream router needs a static route or
PBR with Object Tracking for the mapped addresses that points to the
Main cluster IP address.
PAT with Port Block Allocation—See the following guidelines for this
feature:
Maximum-per-host limit is not a cluster-wide limit, and is enforced on each node
individually. Thus, in a 3-node cluster with the
maximum-per-host limit configured as 1, if the traffic from a
host is load-balanced across all 3 nodes, then it can get
allocated 3 blocks with 1 in each node.
Port blocks created on the backup node from the backup pools are not accounted for when
enforcing the maximum-per-host limit.
On-the-fly PAT rule modifications, where the PAT pool is modified with a completely new
range of IP addresses, will result in xlate backup creation
failures for the xlate backup requests that were still in
transit while the new pool became effective. This behavior is
not specific to the port block allocation feature, and is a
transient PAT pool issue seen only in cluster deployments where
the pool is distributed and traffic is load-balanced across the
cluster nodes.
When operating in a cluster, you cannot simply change the block allocation size. The new
size is effective only after you reload each device in the
cluster. To avoid having to reload each device, we recommend
that you delete all block allocation rules and clear all xlates
related to those rules. You can then change the block size and
recreate the block allocation rules.
NAT pool address distribution for dynamic PAT—When you configure a PAT pool, the cluster
divides each IP address in the pool into port blocks. By default, each
block is 512 ports, but if you configure port block allocation rules,
your block setting is used instead. These blocks are distributed evenly
among the nodes in the cluster, so that each node has one or more blocks
for each IP address in the PAT pool. Thus, you could have as few as one
IP address in a PAT pool for a cluster, if that is sufficient for the
number of PAT’ed connections you expect. Port blocks cover the
1024-65535 port range, unless you configure the option to include the
reserved ports, 1-1023, on the PAT pool NAT rule.
Same translation object in static and dynamic NAT rules—Do not use the same network object or object group as the translated
address in both static NAT rules and dynamic NAT rules in a cluster. Similarly, avoid using network objects or object groups
with overlapping address ranges across static and dynamic NAT rules. Use separate network objects or object groups for static
translations and dynamic translations. Mixing these configurations can cause translation ownership inconsistencies in the
cluster, which can result in traffic drops or intermittent connection failures.
Reusing a PAT pool in multiple rules—To use the same PAT pool in multiple
rules, you must be careful about the interface selection in the rules.
You must either use specific interfaces in all rules, or "any" in all
rules. You cannot mix specific interfaces and "any" across the rules, or
the system might not be able to match return traffic to the right node
in the cluster. Using unique PAT pools per rule is the most reliable
option.
No round-robin—Round-robin for a PAT pool is not supported with
clustering.
No extended PAT—Extended PAT is not supported with clustering.
Dynamic NAT xlates managed by the control node—The control node
maintains and replicates the xlate table to data nodes. When a data node
receives a connection that requires dynamic NAT, and the xlate is not in
the table, it requests the xlate from the control node. The data node
owns the connection.
Stale xlates—The xlate idle time on the connection owner does not get
updated. Thus, the idle time might exceed the idle timeout. An idle
timer value higher than the configured timeout with a refcnt of 0 is an
indication of a stale xlate.
No static PAT for the following inspections—
FTP
RSH
SQLNET
TFTP
XDMCP
SIP
If you have an extremely large number of NAT rules, over ten thousand, you should enable
the transactional commit model using the asp rule-engine
transactional-commit nat command in the device
CLI. Otherwise, the node might not be able to join the cluster.
SIP Inspection and Clustering
A control flow can be created on any node (due to load balancing); its
child data flows must reside on the same node.
SNMP and Clustering
You should always use the Local address, and not the Main cluster IP
address for SNMP polling. If the SNMP agent polls the Main cluster IP address,
if a new control node is elected, the poll to the new control node will fail.
Syslog and Clustering
Each node in the cluster generates
its own syslog messages. You can configure logging so that each node
uses either the same or a different device ID in the syslog message
header field. For example, the hostname configuration is replicated and
shared by all nodes in the cluster. If you configure logging to use the
hostname as the device ID, syslog messages generated by all nodes look
as if they come from a single node. If you configure logging to use the
local-node name that is assigned in the cluster bootstrap configuration
as the device ID, syslog messages look as if they come from different
nodes.
Performance scaling factor
When you combine multiple units into a cluster, you can expect the total cluster performance to be approximately 80% of the
maximum combined throughput.
Throughput calculation
For example, if your model can handle approximately 10 Gbps of traffic when running alone, then for a cluster of 8 units,
the maximum combined throughput will be approximately 80% of 80 Gbps (8 units x 10 Gbps): 64 Gbps.
Control node election
Summary
The key components involved in the control node election process are:
Cluster nodes: Communicate over the cluster control link and participate in the election process
Election requests: Broadcast every 3 seconds by nodes when clustering is enabled
Priority values: Set between 1 and 100 where 1 is the highest priority
Control node: The elected node that coordinates cluster operations
Workflow
These stages describe how cluster nodes elect a control node:
When clustering is enabled for a node (or when it first starts up with clustering already enabled), the node broadcasts an
election request every 3 seconds.
Any other nodes with a higher priority respond to the election request. The priority is set between 1 and 100, where 1 is
the highest priority.
If after 45 seconds, a node does not receive a response from another node with a higher priority, then it becomes the control
node.
Note
If multiple nodes tie for the highest priority, the cluster node name and then the serial number is used to determine the
control node.
If a node later joins the cluster with a higher priority, it does not automatically become the control node. The existing
control node always remains as the control node unless it stops responding, at which point a new control node is elected.
In a "split brain" scenario when there are temporarily multiple control nodes, the node with highest priority retains the
role while the other nodes return to data node roles.
Note
You can manually force a node to become the control node. For centralized features, if you force a control node change, then
all connections are dropped, and you have to re-establish the connections on the new control node.
High Availability within the Cluster
Clustering provides high availability by monitoring node and
interface health and by replicating connection states between nodes.
Node health monitoring
Each node periodically sends a broadcast heartbeat packet over the cluster control link. If the control node does not receive any heartbeat packets or other packets from a data node within the configurable timeout period, then the control node removes the data node from the cluster. If the data nodes do not receive packets from
the control node, then a new control node is elected from the remaining nodes.
Split brain scenario
If nodes cannot reach each other over the cluster control link because of a network failure and not because a node has actually
failed, then the cluster may go into a "split brain" scenario where isolated data nodes will elect their own control nodes.
For example, if a router fails between two cluster locations, then the original control node at location 1 will remove the
location 2 data nodes from the cluster. Meanwhile, the nodes at location 2 will elect their own control node and form their
own cluster. Note that asymmetric traffic may fail in this scenario. After the cluster control link is restored, then the
control node that has the higher priority will keep the control node's role.
Interface Monitoring
Each node monitors the link status of all named hardware interfaces in use, and reports status changes to the control node.
All physical interfaces are monitored; only named interfaces can be monitored. You can optionally disable monitoring per interface.
A node is removed from the cluster if its monitored interfaces fail. The node is removed after 500 milliseconds.
Status After Failure
If the control node fails, then another member of the cluster with the highest priority (lowest number) becomes the control
node.
The Firewall Threat
Defense automatically tries to rejoin the cluster, depending on the failure event.
Note
When the Firewall Threat
Defense becomes inactive and fails to automatically rejoin the cluster, all data interfaces are shut down; only the Management interface can send and receive traffic.
Rejoining the Cluster
After a cluster member is removed from the cluster, how it can rejoin the cluster
depends on why it was removed:
Failed cluster control link when initially joining—After you resolve the problem with the cluster control link, you must manually
rejoin the cluster by re-enabling clustering.
Failed cluster control link after joining the cluster—The Firewall Threat Defense automatically tries to rejoin every 5 minutes, indefinitely.
Failed data interface—The Firewall Threat Defense automatically tries to rejoin at 5 minutes, then at 10 minutes, and finally at 20 minutes. If the join is not successful
after 20 minutes, then the Firewall Threat Defense application disables clustering. After you resolve the problem with the data interface, you have to manually enable clustering.
Failed node—If the node was removed from the cluster because of a node health check failure, then rejoining the cluster depends
on the source of the failure. For example, a temporary power failure means the node will rejoin the cluster when it starts
up again as long as the cluster control link is up. The Firewall Threat Defense application attempts to rejoin the cluster every 5 seconds.
Internal error—Internal failures include: application sync timeout; inconsistent application statuses; and so on. After you resolve the problem, you must manually rejoin the cluster by re-enabling clustering.
Failed configuration deployment—If you deploy a new configuration from Firewall Management
Center, and the deployment fails on some cluster members but succeeds on others, then the nodes that failed are removed from the
cluster. You must manually rejoin the cluster by re-enabling clustering. If the deployment fails on the control node, then
the deployment is rolled back, and no members are removed. If the deployment fails on all data nodes, then the deployment is rolled back, and no members are removed.
Data Path Connection State Replication
Every connection has one owner and at least one backup owner in the cluster. The backup owner does not take over the connection
in the event of a failure; instead, it stores TCP/UDP state information, so that the connection can be seamlessly transferred
to a new owner in case of a failure. The backup owner is usually also the director.
Some traffic requires state information above the TCP or UDP layer. See the following table for clustering support or lack
of support for this kind of traffic.
Table 5. Features Replicated Across the Cluster
Traffic
State Support
Notes
Up time
Yes
Keeps track of the system up time.
ARP Table
Yes
Transparent mode only.
MAC address table
Yes
Transparent mode only.
User Identity
Yes
—
Dynamic routing
Yes
—
SNMP Engine ID
No
—
How the Cluster Manages Connections
Connections can be load-balanced to multiple nodes of the cluster.
Connection roles determine how connections are handled in both normal operation
and in a high availability situation.
Connection Roles
See the following roles defined for each connection:
Owner—Usually, the node that initially receives the connection. The owner maintains the TCP state and processes packets. A
connection has only one owner. If the original owner fails, then when new nodes receive packets from the connection, the director
chooses a new owner from those nodes.
Backup owner—The node that stores TCP/UDP state information received from the owner, so that the connection can be seamlessly
transferred to a new owner in case of a failure. The backup owner does not take over the connection in the event of a failure.
If the owner becomes unavailable, then the first node to receive packets from the connection (based on load balancing) contacts
the backup owner for the relevant state information so it can become the new owner.
As long as the director (see below) is not the same node as the owner, then the director is also the backup owner. If the
owner chooses itself as the director, then a separate backup owner is chosen.
Director—The node that handles owner lookup requests from forwarders. When the owner receives a new connection, it chooses
a director based on a hash of the source/destination IP address and ports (see below for ICMP hash details), and sends a message
to the director to register the new connection. If packets arrive at any node other than the owner, the node queries the director
about which node is the owner so it can forward the packets. A connection has only one director. If a director fails, the
owner chooses a new director.
As long as the director is not the same node as the owner, then the director is also the backup owner (see above). If the
owner chooses itself as the director, then a separate backup owner is chosen.
ICMP/ICMPv6 hash details:
For Echo packets, the source port is the ICMP identifier, and the destination port is 0.
For Reply packets, the source port is 0, and the destination port is the ICMP identifier.
For other packets, both source and destination ports are 0.
Forwarder—A node that forwards packets to the owner. If a forwarder receives a packet for a connection it does not own, it
queries the director for the owner, and then establishes a flow to the owner for any other packets it receives for this connection.
The director can also be a forwarder. Note that if a forwarder receives the SYN-ACK packet, it can derive the owner directly
from a SYN cookie in the packet, so it does not need to query the director. (If you disable TCP sequence randomization, the
SYN cookie is not used; a query to the director is required.) For short-lived flows such as DNS and ICMP, instead of querying,
the forwarder immediately sends the packet to the director, which then sends them to the owner. A connection can have multiple
forwarders; the most efficient throughput is achieved by a good load-balancing method where there are no forwarders and all
packets of a connection are received by the owner.
Note
We do not recommend disabling TCP sequence randomization when using clustering. There is a small chance that some TCP sessions
won't be established, because the SYN/ACK packet might be dropped.
Fragment Owner—For fragmented packets, cluster nodes that receive a fragment determine a fragment owner using a hash of the
fragment source IP address, destination IP address, and the packet ID. All fragments are then forwarded to the fragment owner
over the cluster control link. Fragments may be load-balanced to different cluster nodes, because only the first fragment
includes the 5-tuple used in the switch load balance hash. Other fragments do not contain the source and destination ports
and may be load-balanced to other cluster nodes. The fragment owner temporarily reassembles the packet so it can determine
the director based on a hash of the source/destination IP address and ports. If it is a new connection, the fragment owner
will register to be the connection owner. If it is an existing connection, the fragment owner forwards all fragments to the
provided connection owner over the cluster control link. The connection owner will then reassemble all fragments.
Port Address Translation Connections
New connection ownership
When a new connection is directed to a node of the cluster via load balancing, that node owns both directions of the connection.
If any connection packets arrive at a different node, they are forwarded to the owner node over the cluster control link.
If a reverse flow arrives at a different node, it is redirected back to the original node.
Traffic redirection is not supported in this release. When a new connection is directed to a node of the cluster via load
balancing, that node owns both directions of the connection. All the subsequent packets for the same connection should arrive
the same node. If any connection packets arrive at a different node, they will be dropped. If a reverse flow arrives at a
different node, it will be dropped as well. For centralized features, if the connections do not arrive on the control node,
they will be dropped.
Sample Data Flow for TCP
The following example shows the establishment of a new
connection.
The SYN packet originates from the client and is delivered to one Firewall Threat Defense (based on the load balancing method), which becomes the owner. The
owner creates a flow, encodes owner information into a SYN cookie, and
forwards the packet to the server.
The SYN-ACK packet originates from the server and is delivered to a
different Firewall Threat Defense (based on the load balancing method). This Firewall Threat Defense is the forwarder.
Because the forwarder does not own the connection, it decodes
owner information from the SYN cookie, creates a forwarding flow to the owner,
and forwards the SYN-ACK to the owner.
The owner sends a state update to the director, and forwards the
SYN-ACK to the client.
The director receives the state update from the owner, creates a
flow to the owner, and records the TCP state information as well as the owner.
The director acts as the backup owner for the connection.
Any subsequent packets delivered to the forwarder will be
forwarded to the owner.
If packets are delivered to any additional nodes, it will query the
director for the owner and establish a flow.
Any state change for the flow results in a state update from the
owner to the director.
Sample Data Flow for ICMP and UDP
The following example shows the establishment of a new connection.
Figure 26. ICMP and UDP Data Flow
The first UDP packet originates from the client and is delivered
to one Firewall Threat Defense (based on the load balancing method).
The node that received the first packet queries the director node that is chosen based on a
hash of the source/destination IP address and ports.
The director finds no existing flow, creates a director flow and forwards the packet back
to the previous node. In other words, the director has elected an owner
for this flow.
The owner creates the flow, sends a state update to the director, and
forwards the packet to the server.
The second UDP packet originates from the server and is delivered to the
forwarder.
The forwarder queries the director for ownership information. For
short-lived flows such as DNS, instead of querying, the forwarder
immediately sends the packet to the director, which then sends it to the
owner.
The director replies to the forwarder with ownership information.
The forwarder creates a forwarding flow to record owner information and
forwards the packet to the owner.
The owner forwards the packet to the client.
History for Threat Defense Virtual Clustering on Azure
Table 6.
Feature
Min. Firewall Management
Center
Min. Firewall Threat
Defense
Details
MTU ping test from data node on node
join
7.6.0
7.6.0
When a node joins the cluster, it checks MTU compatibility by
sending a ping to the control node with a packet size twice
the cluster control link MTU. Previously, only the control
node sent a ping. If the ping fails, a notification is
generated so you can fix the MTU mismatch on connecting
switches and try again.
Added/modified commands: show cluster
history.
Cluster control link ping
tool
7.4.1
Any
You can check to make sure all the cluster nodes can reach
each other over the cluster control link by performing a
ping. One major cause for the failure of a node to join the
cluster is an incorrect cluster control link configuration;
for example, the cluster control link MTU may be set higher
than the connecting switch MTUs.
New/modified screens: Devices > Device Management > More > Cluster Live Status.
Troubleshooting file generation
and download available from Device and Cluster
pages
7.4.1
7.4.1
You can generate and download troubleshooting files for each device on the Device page and also for all cluster nodes on the
Cluster page. For a cluster, you can download all files as a single compressed file. You can also include cluster logs for
the cluster for cluster nodes. You can alternatively trigger file generation from the Devices > Device Management > More > Troubleshoot Files menu.
New/modified screens:
Devices > Device Management > Device > General
Devices > Device Management > Cluster > General
View CLI output for a device or device
cluster
7.4.1
Any
You can view a set of pre-defined CLI outputs that can help
you troubleshoot the device or cluster. You can also enter
any show command and see the
output.
New/modified screens: Devices > Device Management > Cluster > General
If you previously configured these settings using FlexConfig,
be sure to remove the FlexConfig configuration before you
deploy. Otherwise the FlexConfig configuration will
overwrite the management center configuration.
Cluster health monitor dashboard
7.3.0
Any
You can now view cluster health on the cluster health monitor
dashboard.
New/Modified screens: System > Health > Monitor
Clustering for the Threat Defense Virtual on Azure
7.3.0
7.3.0
You can now configure clustering for up to 16 nodes the Firewall Threat Defense Virtual in Azure for the Azure Gateway Load Balancer or for external
load balancers.

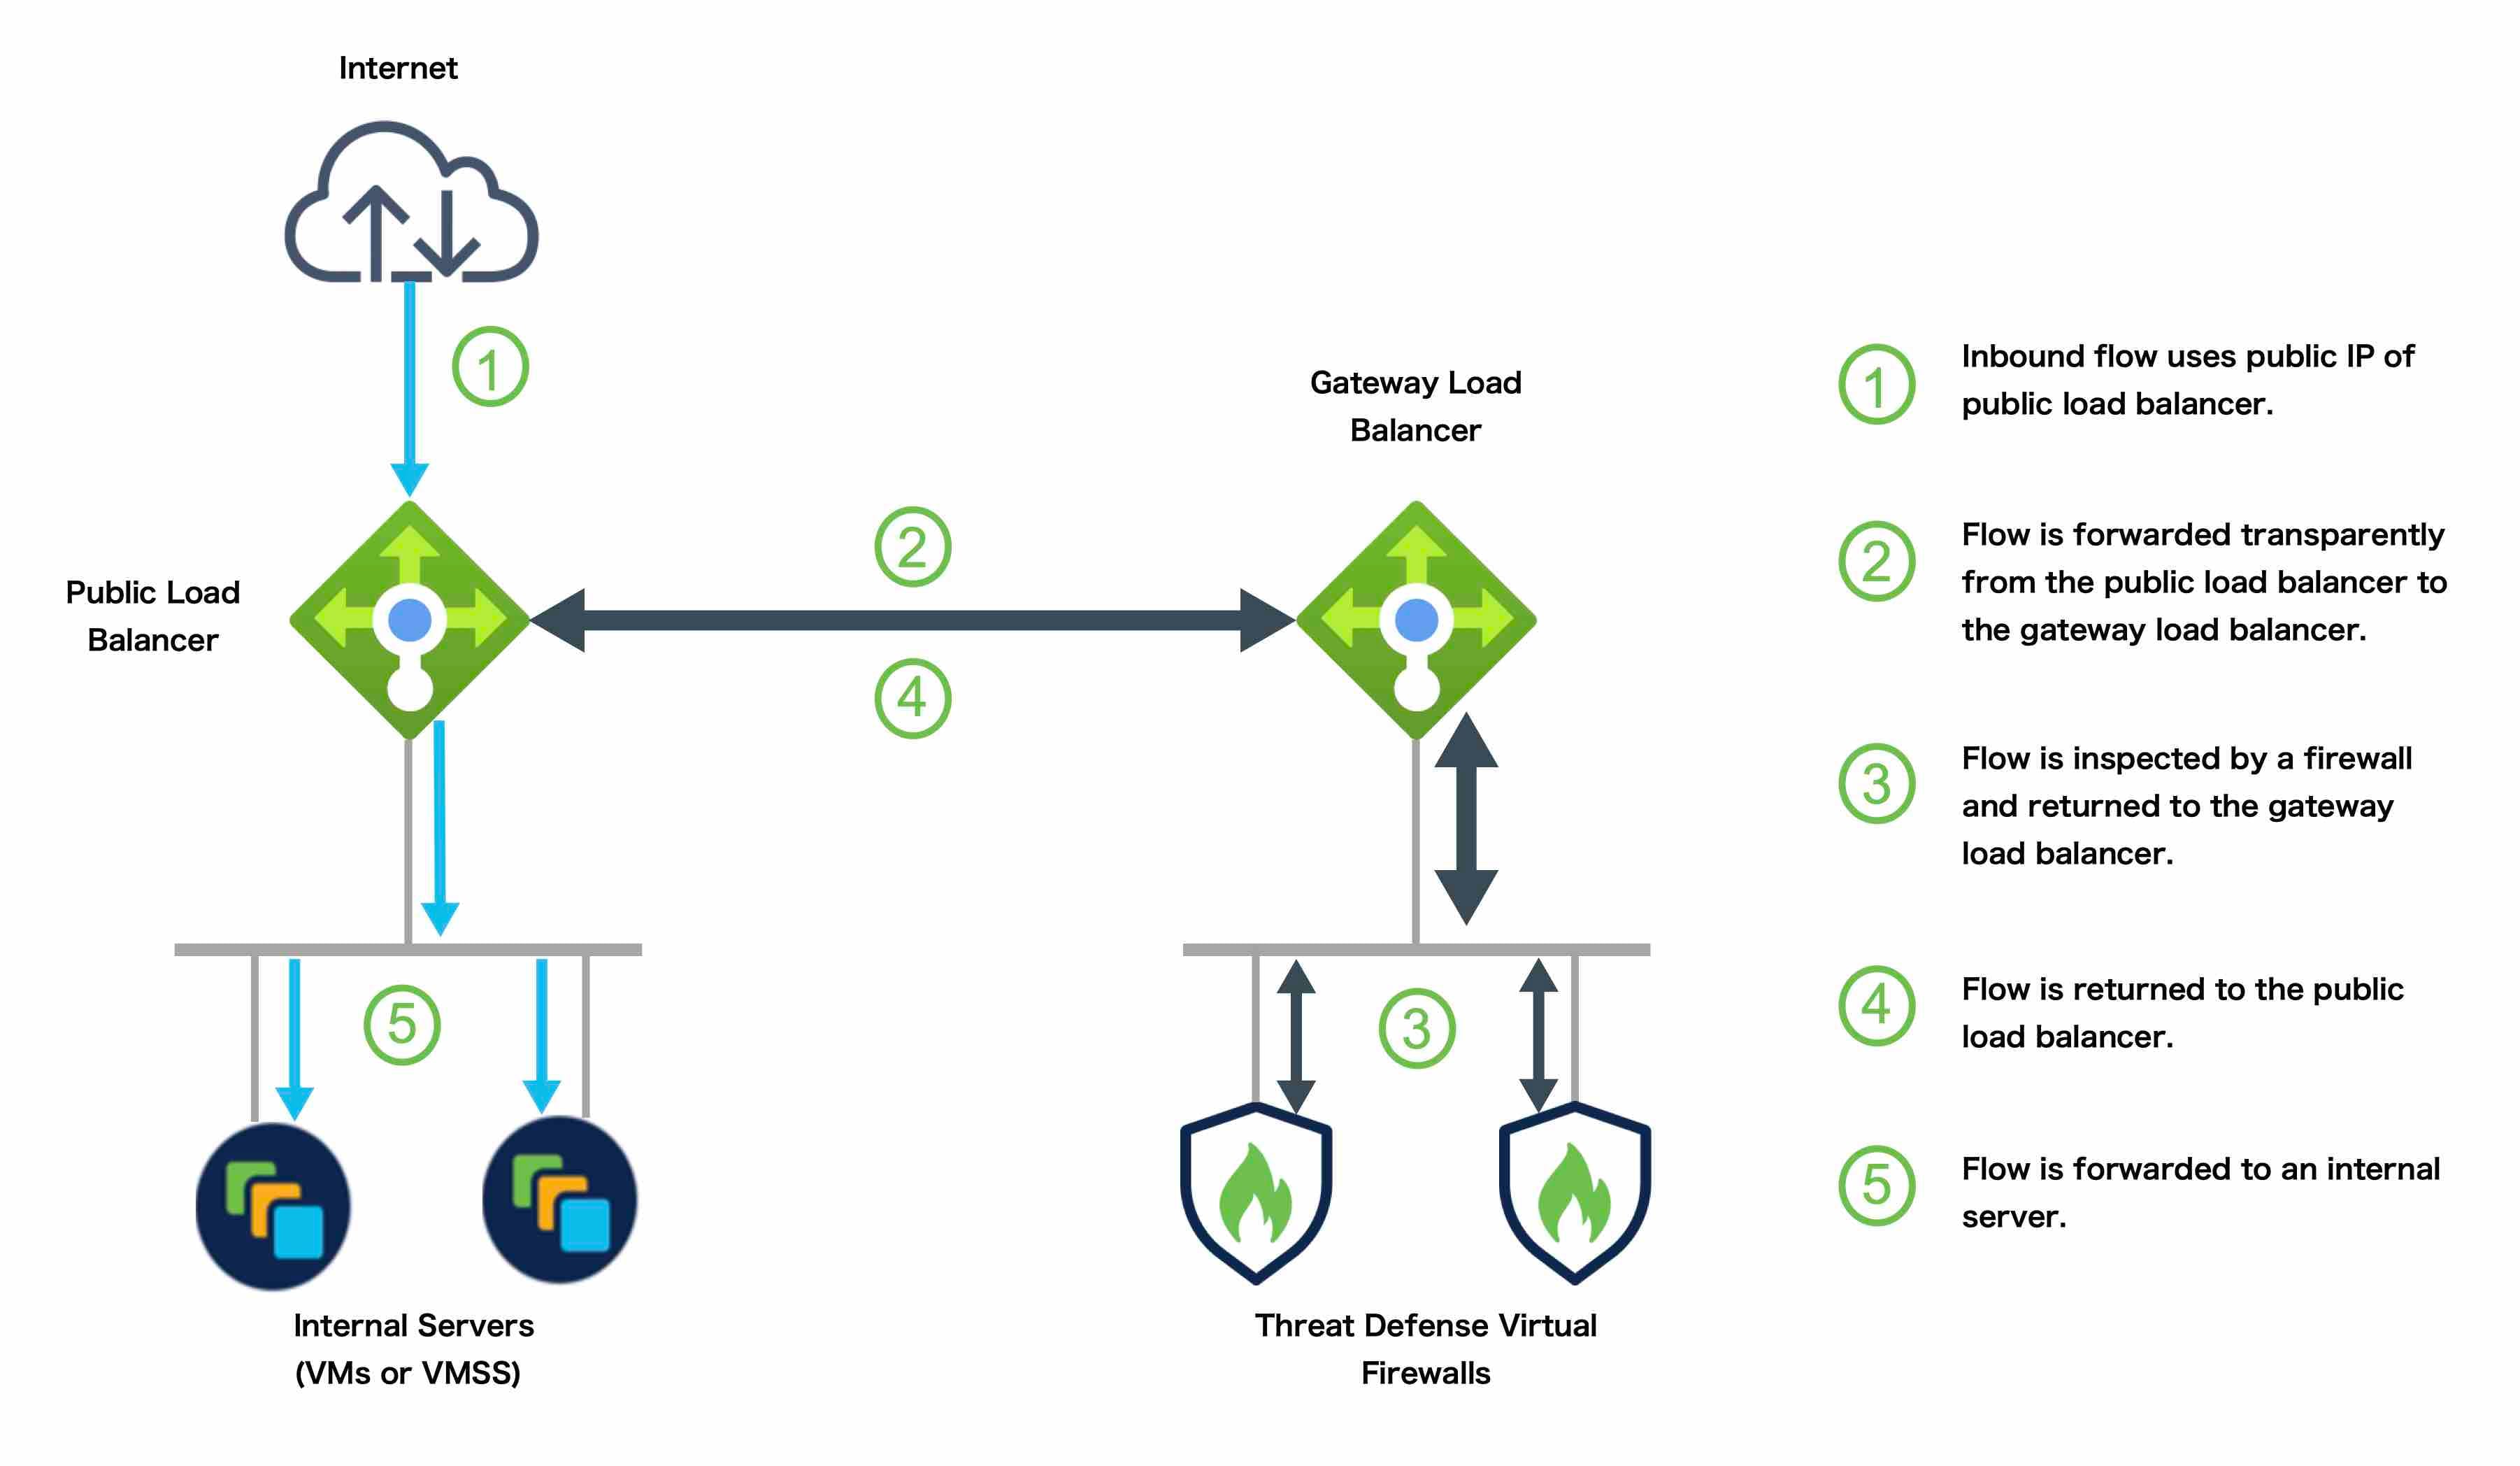
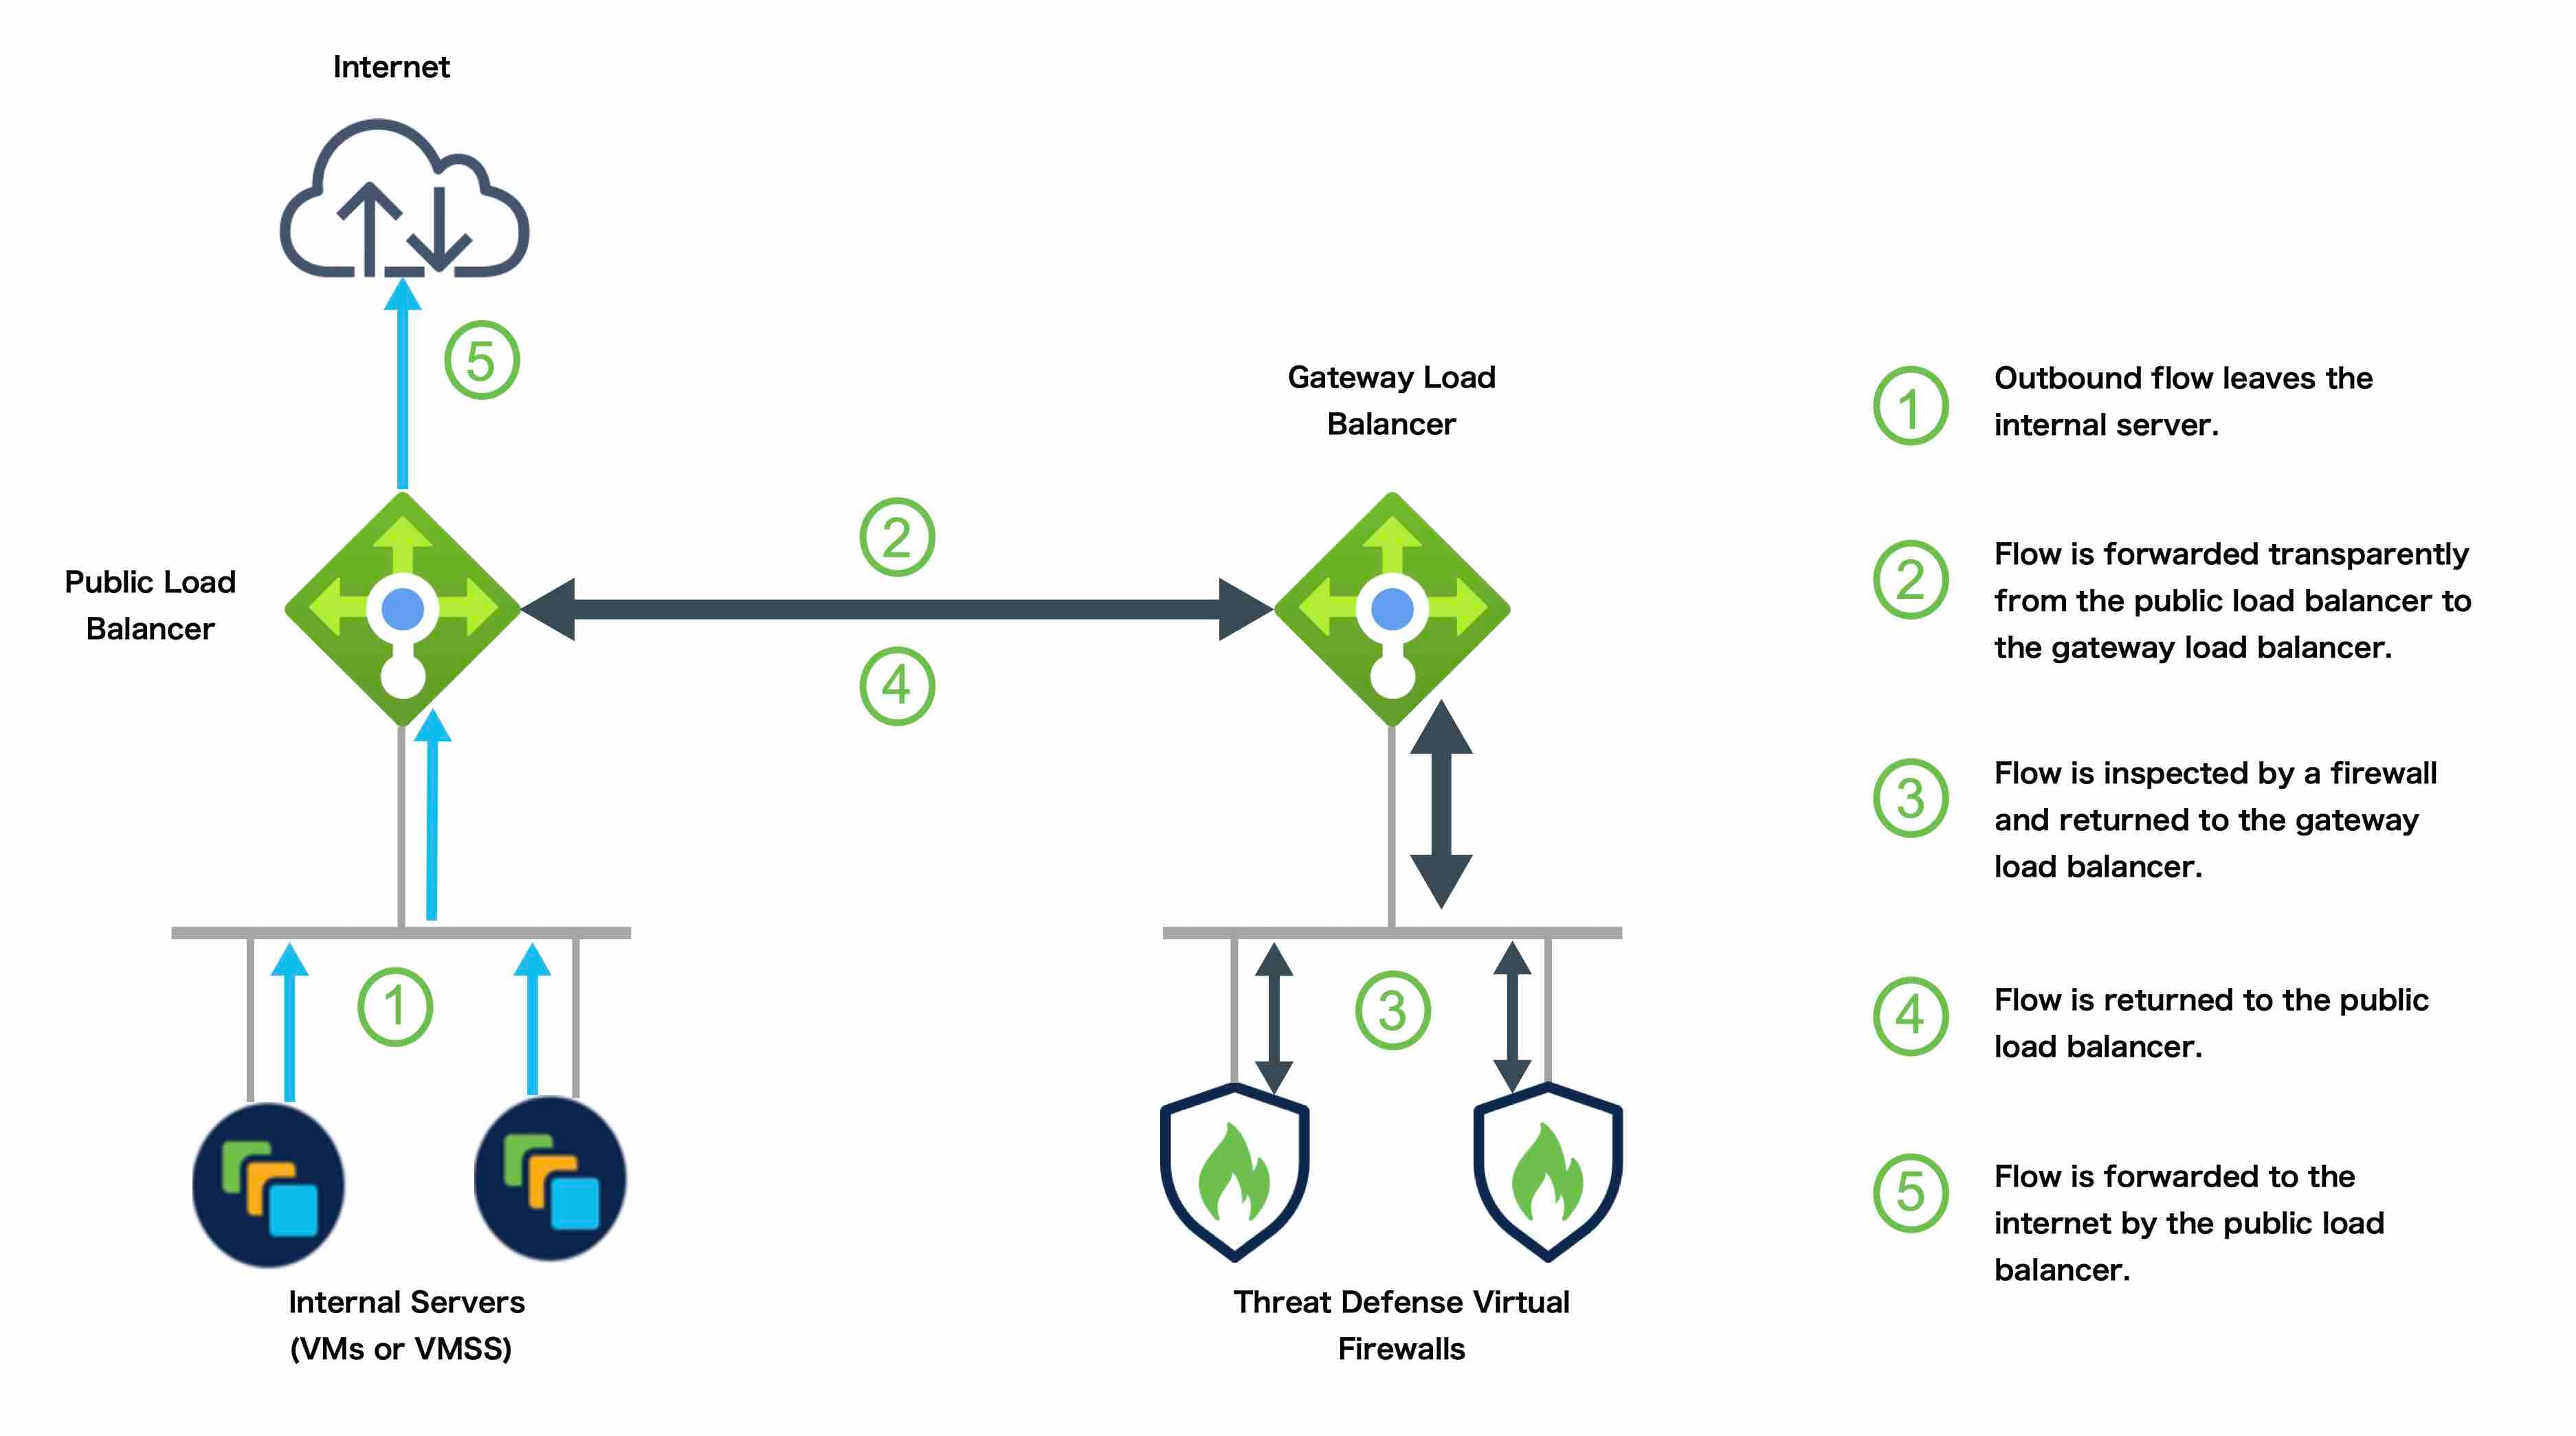
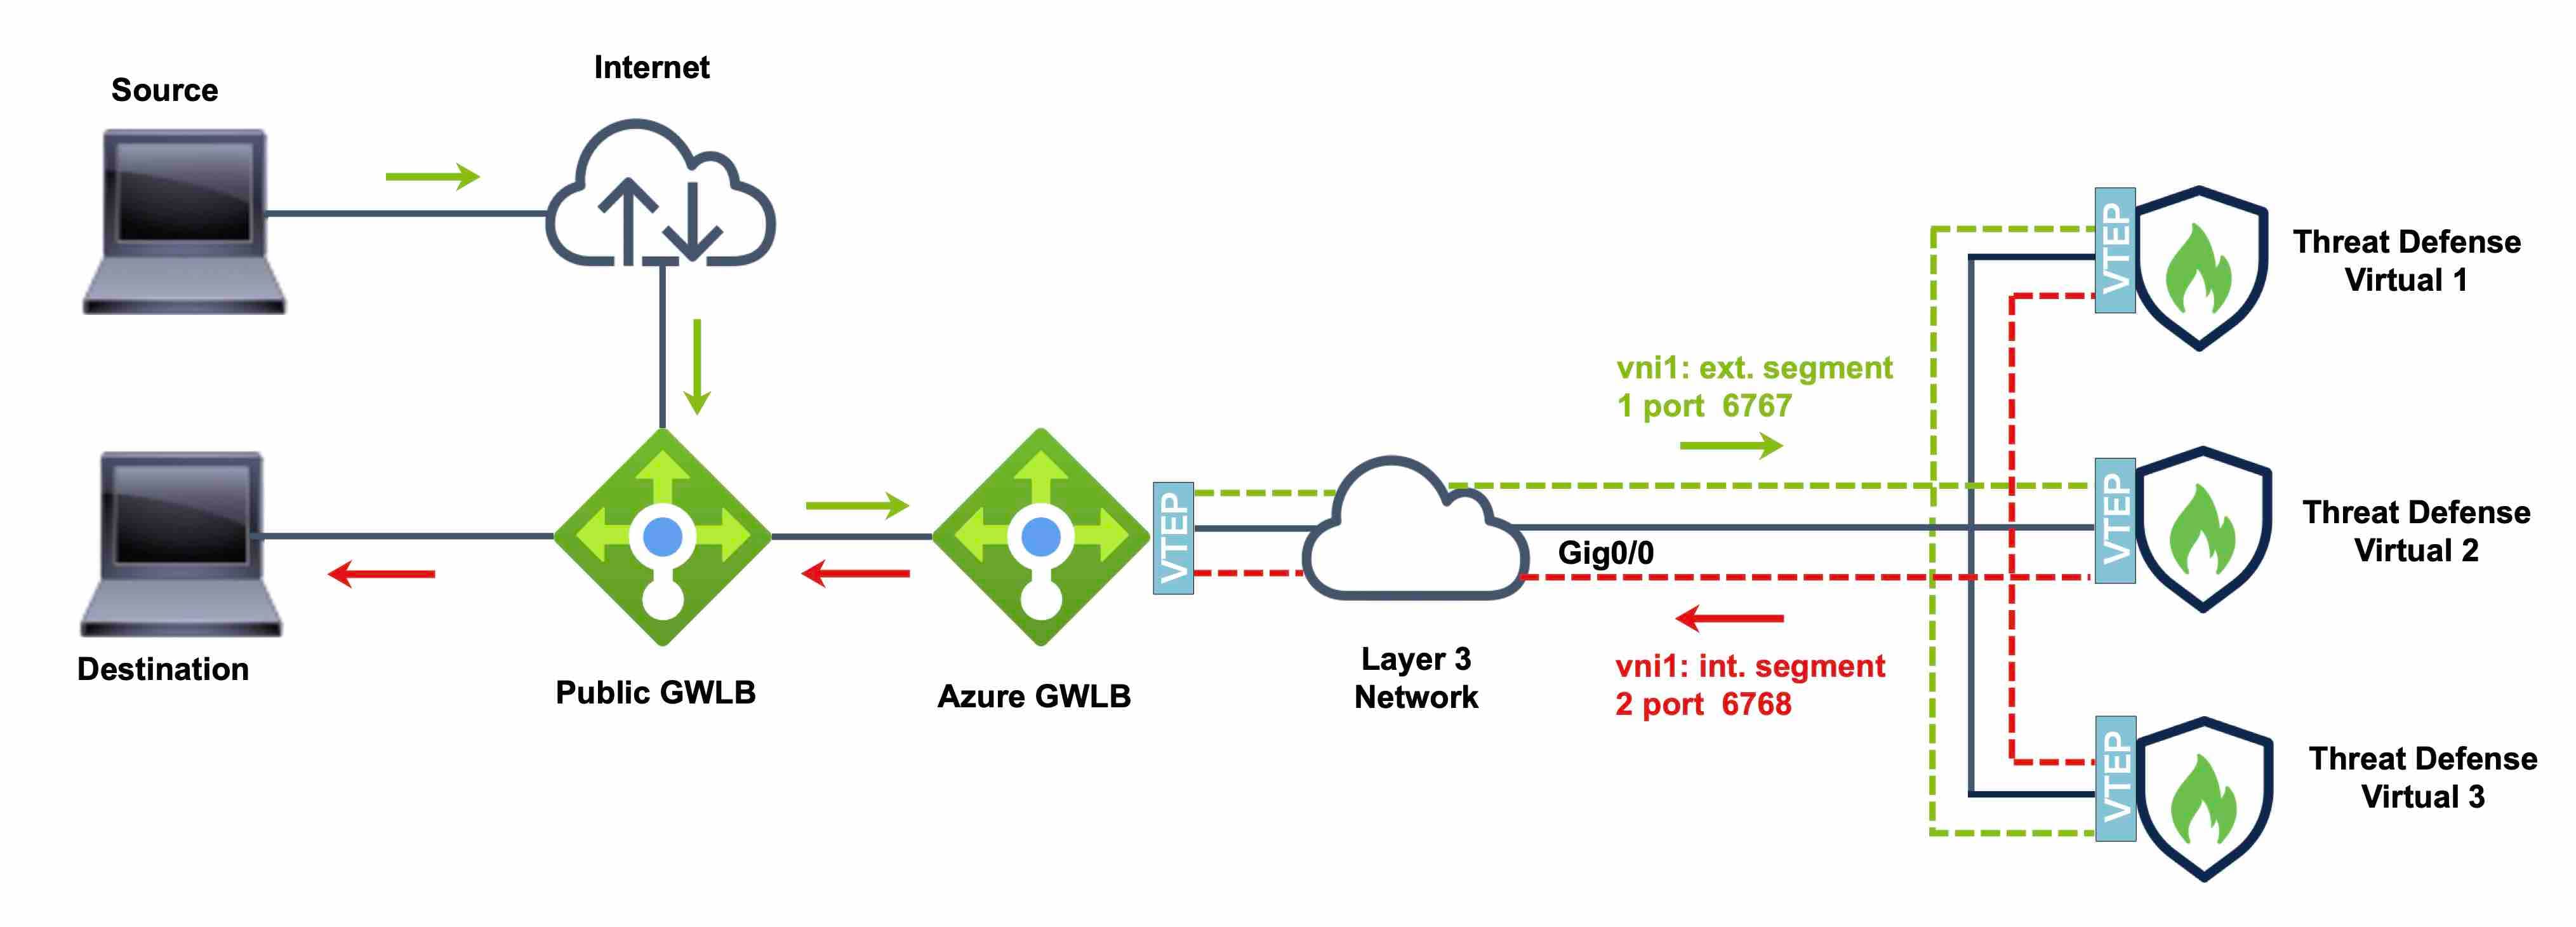
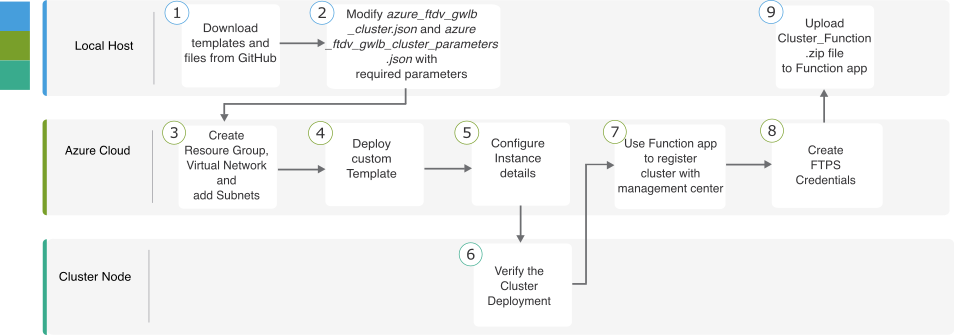


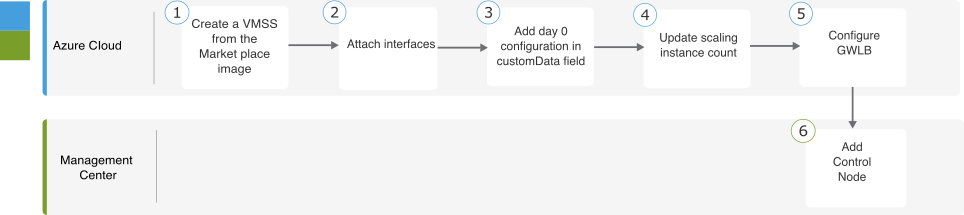


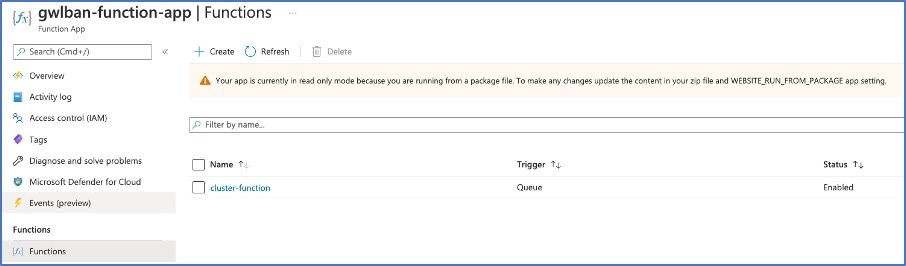
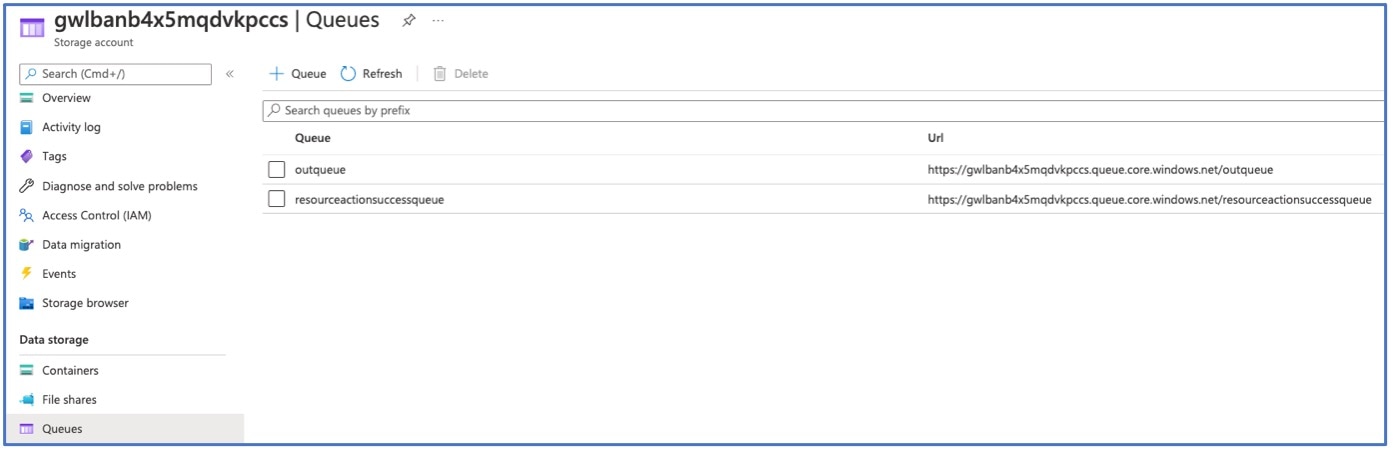
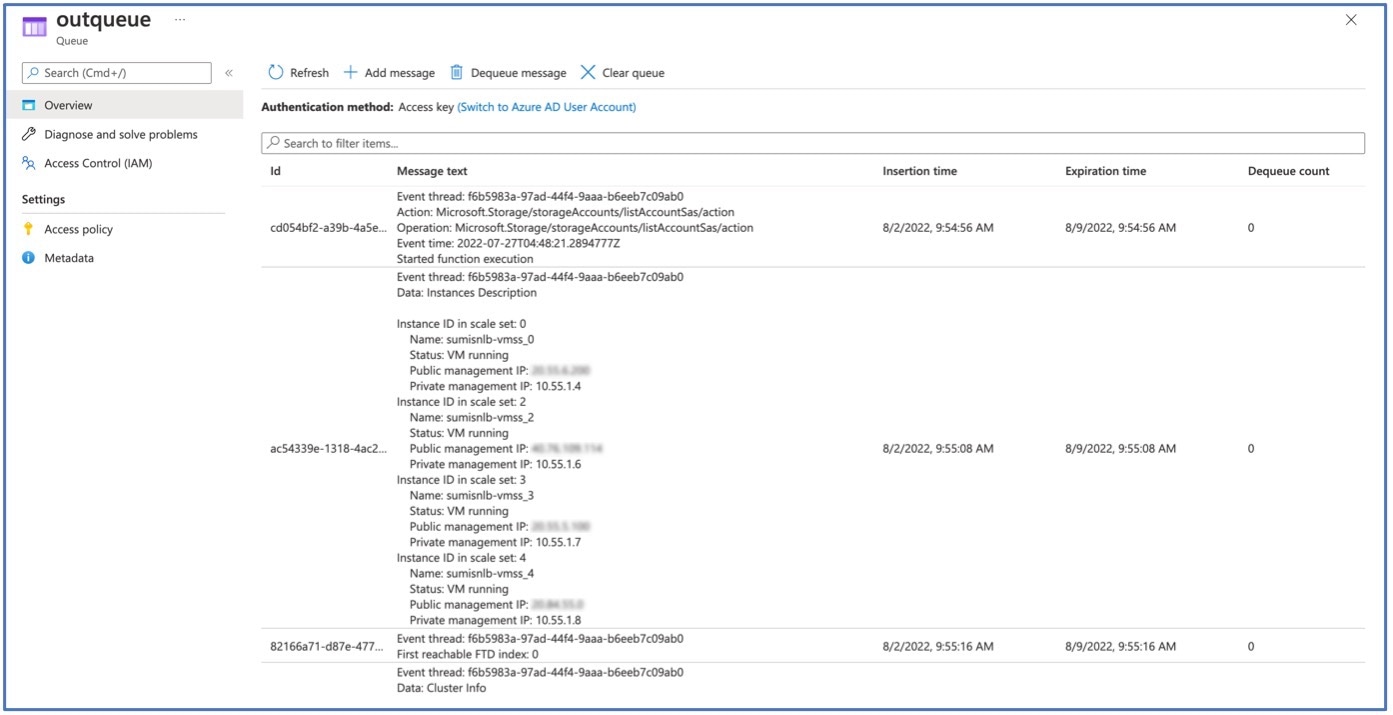
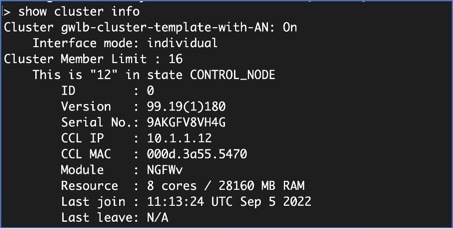
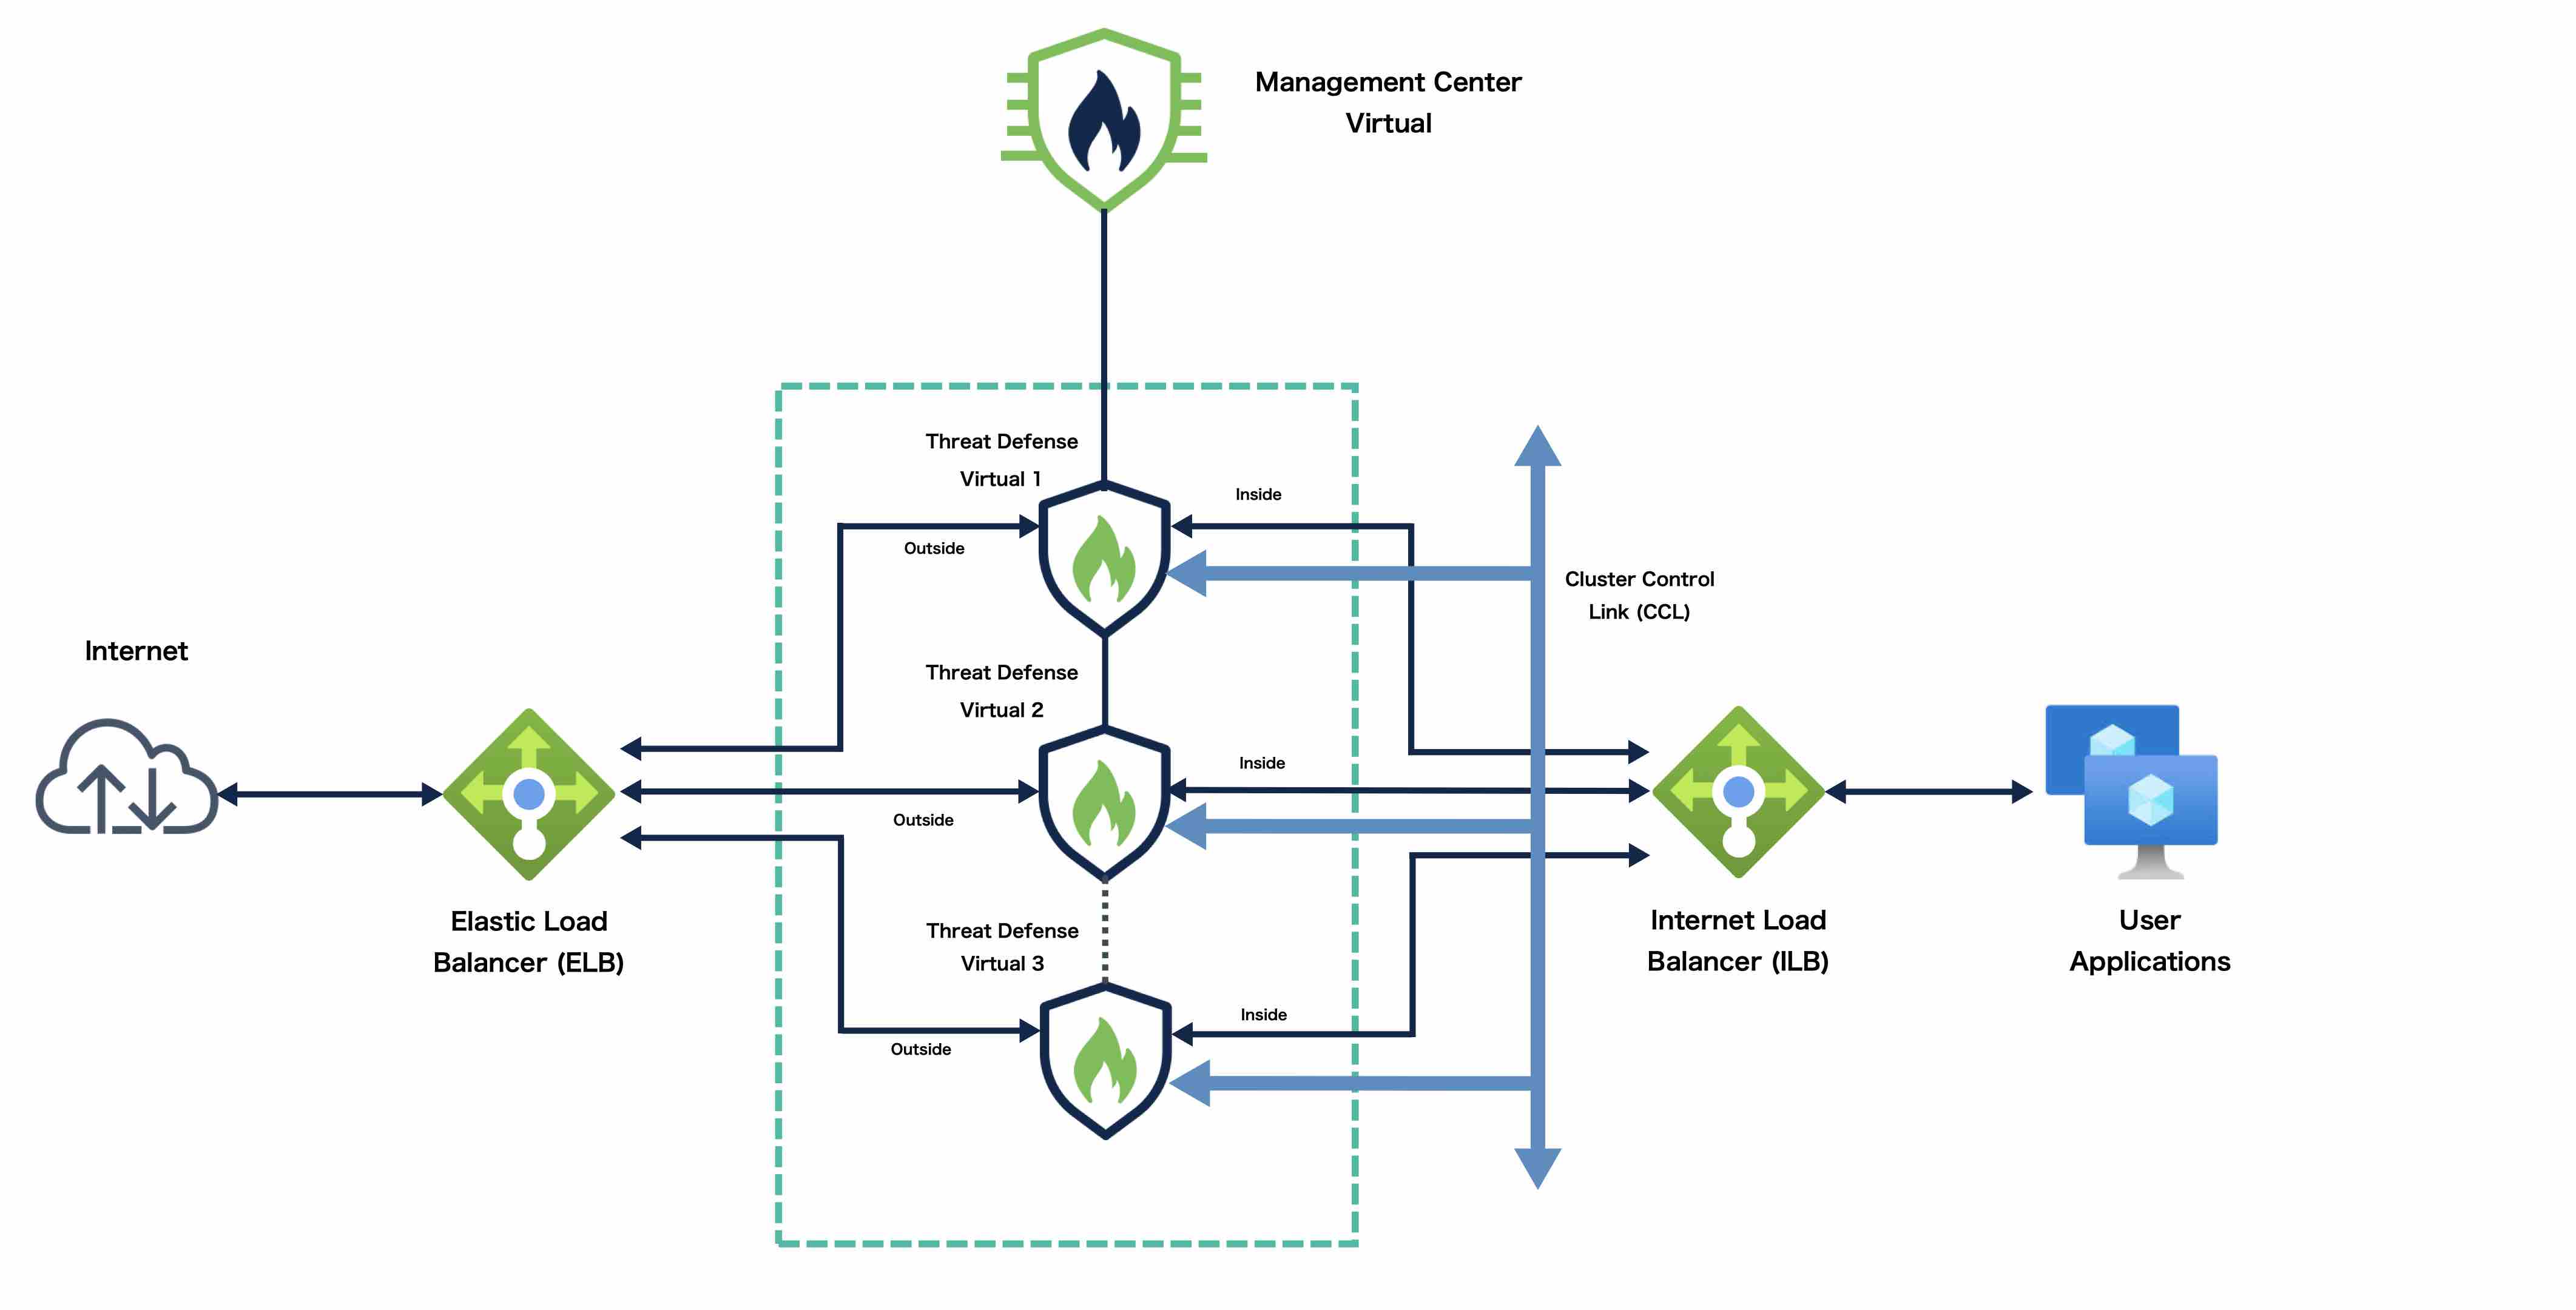
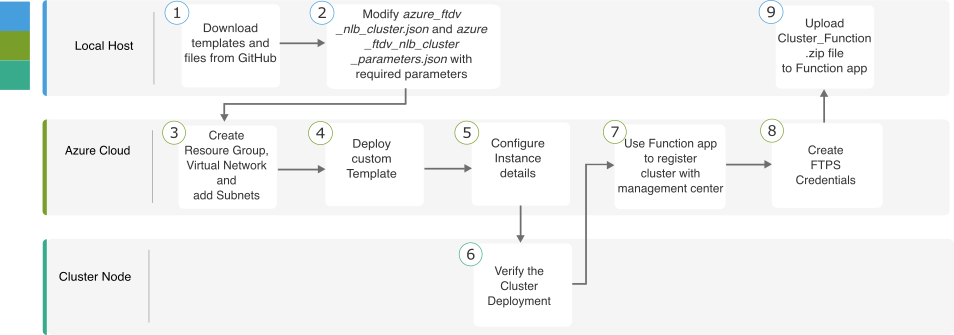
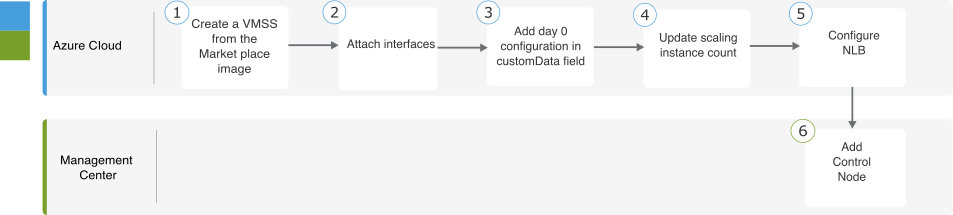
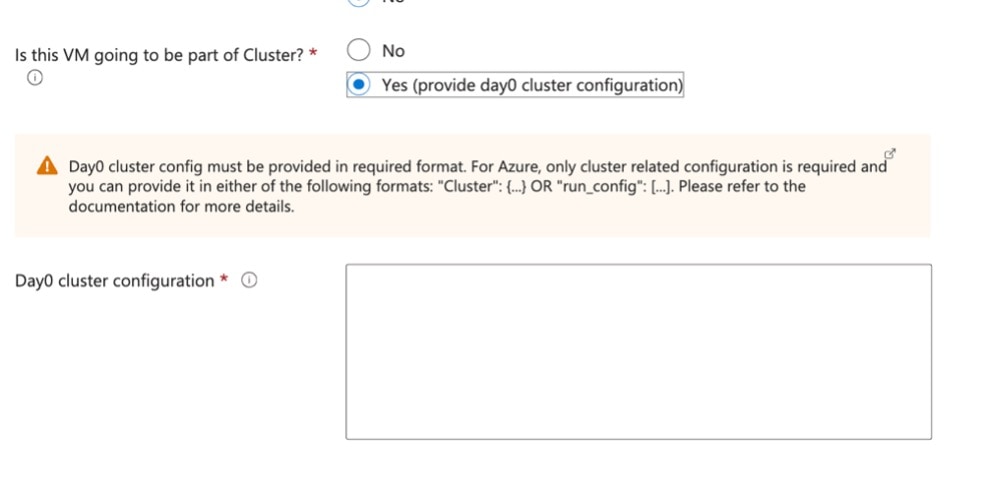
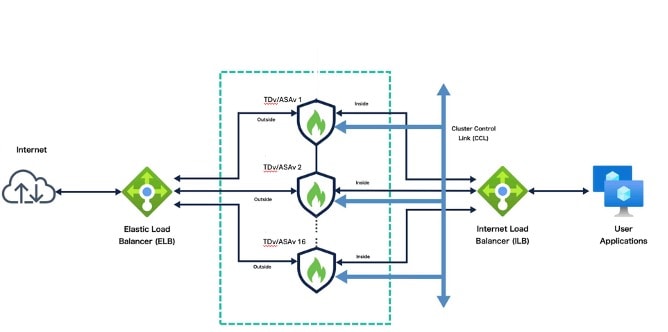

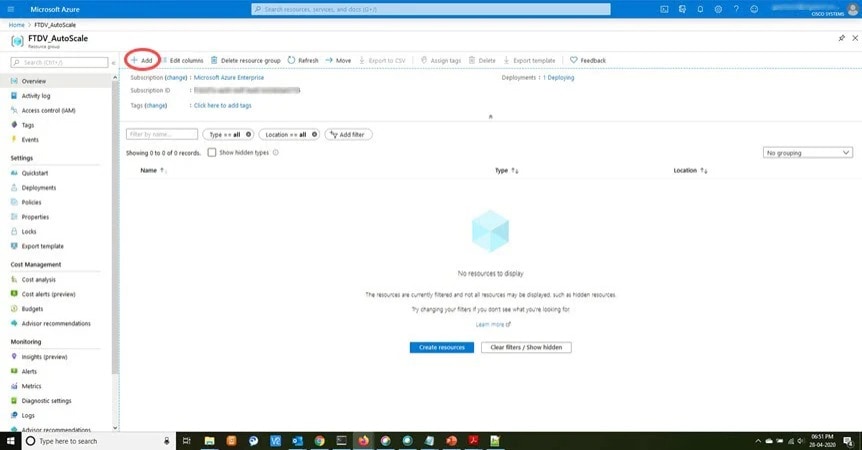
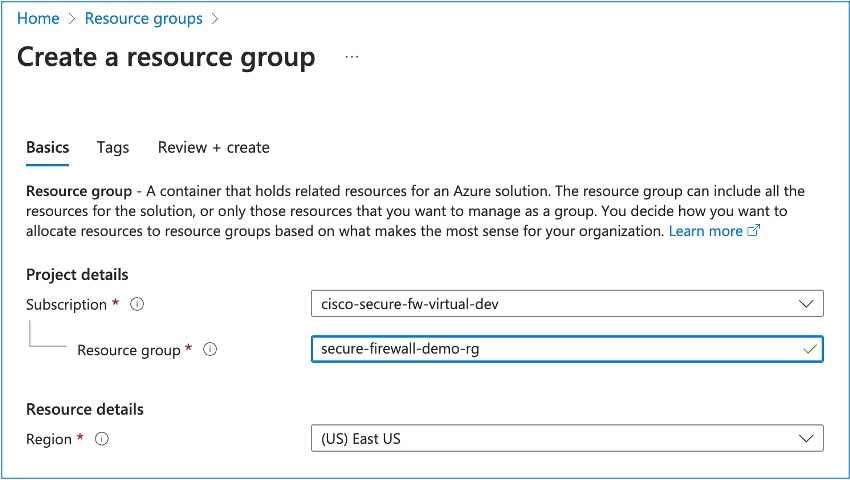
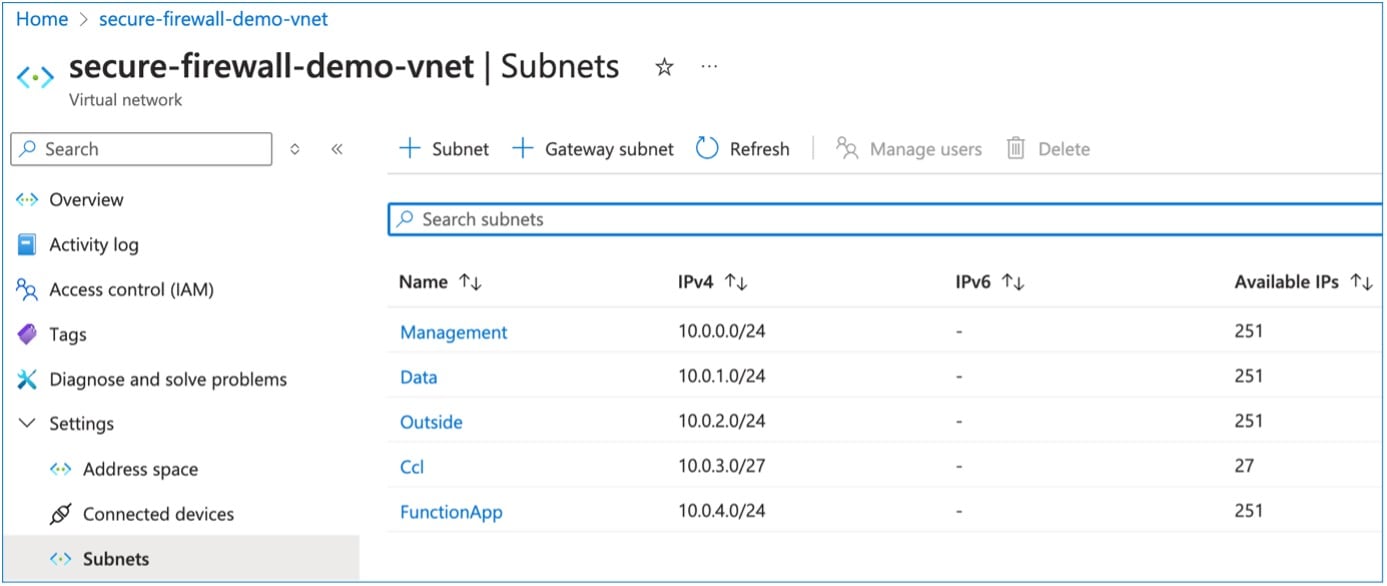
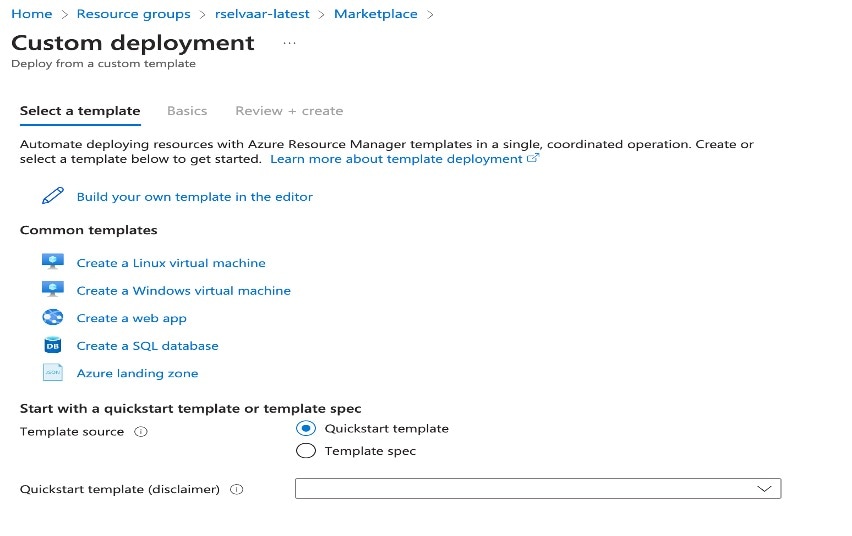
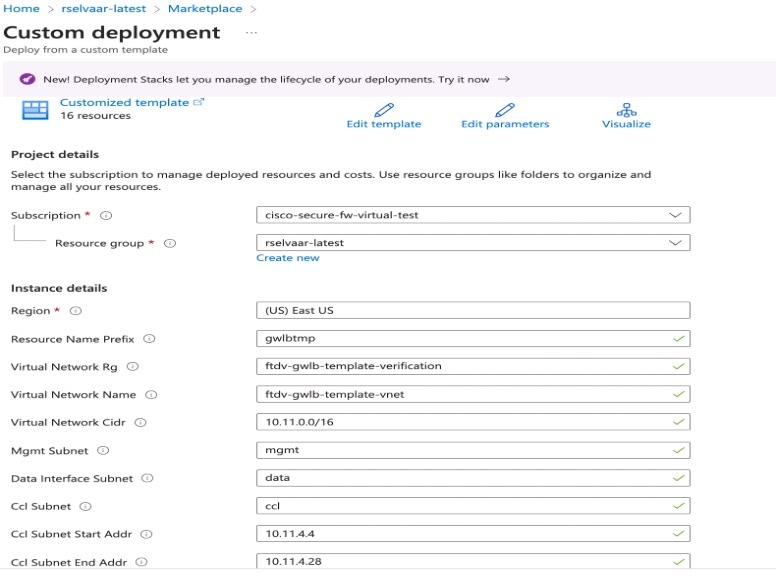
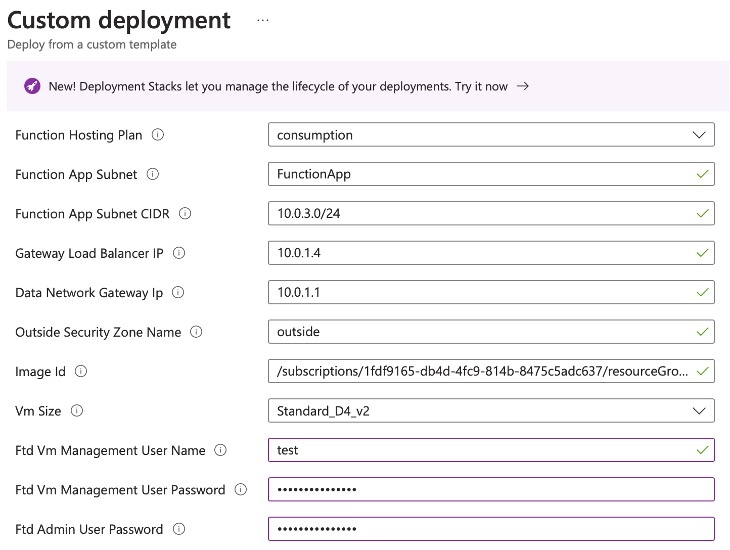
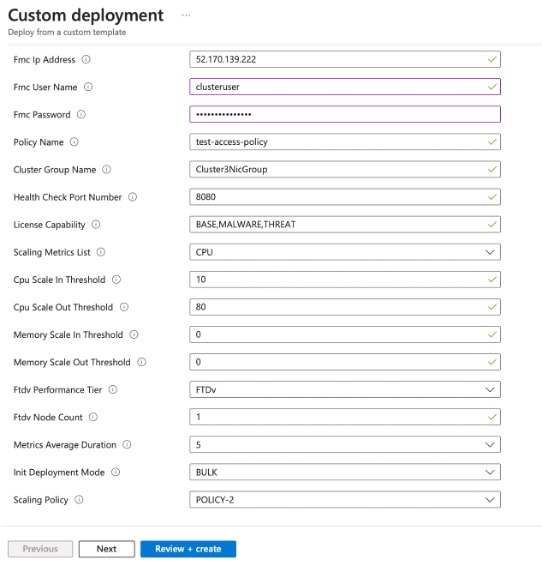
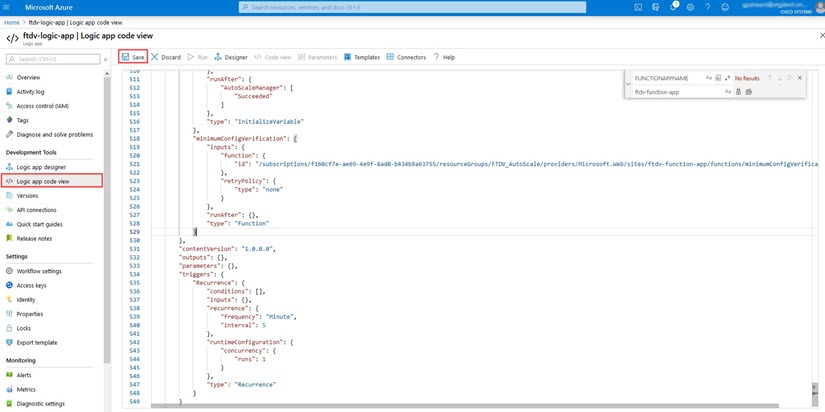
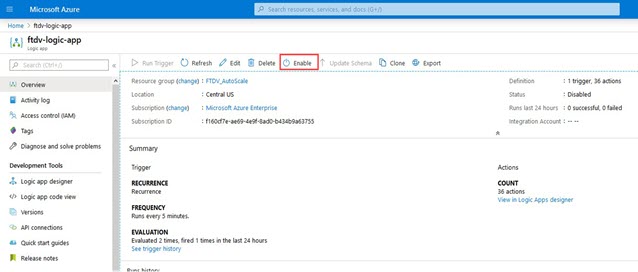
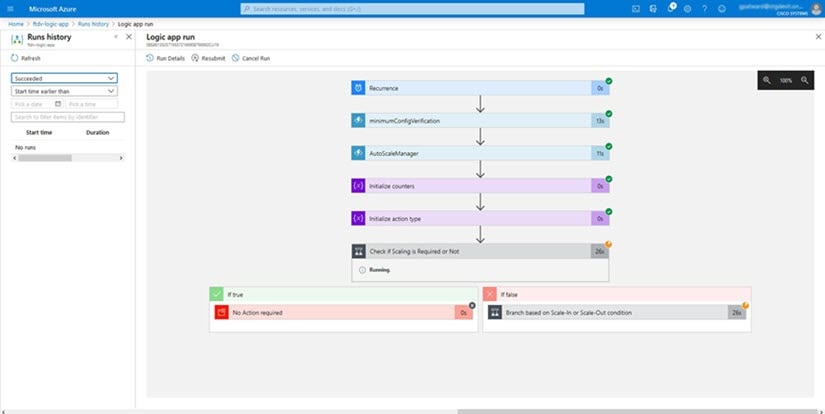
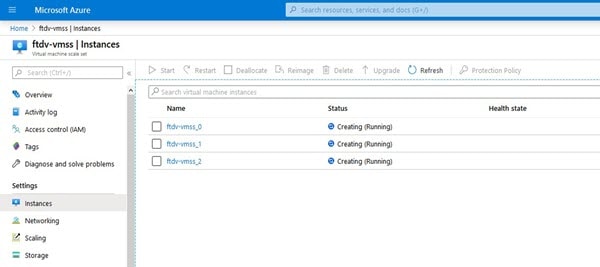
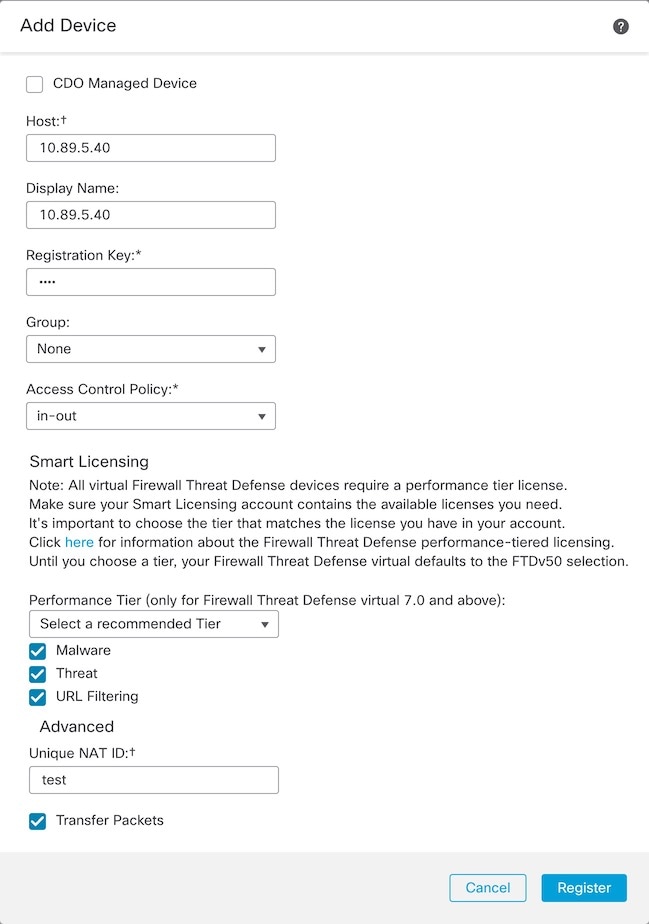
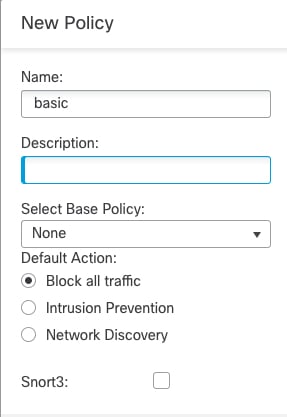
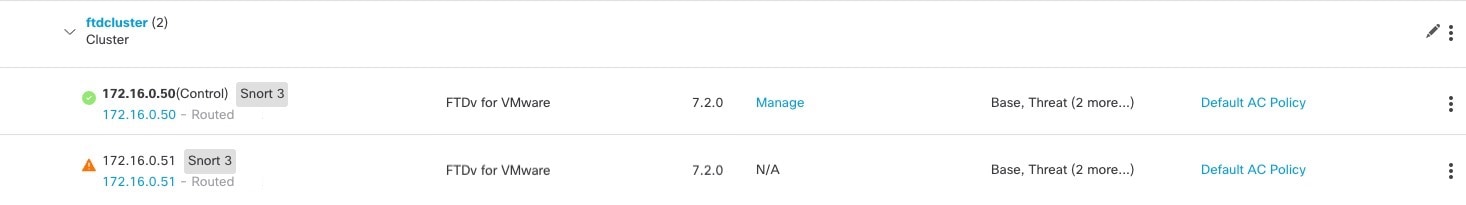
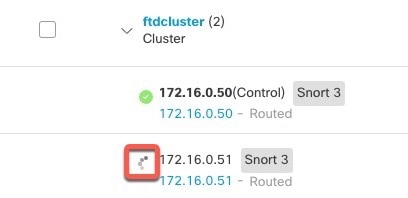
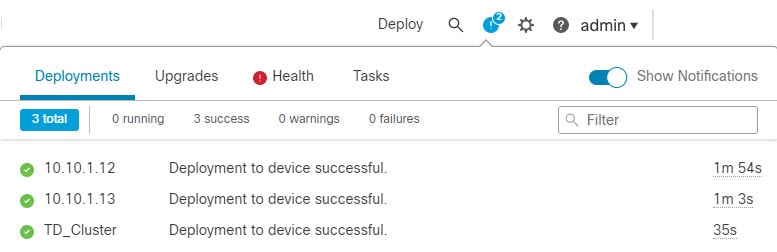

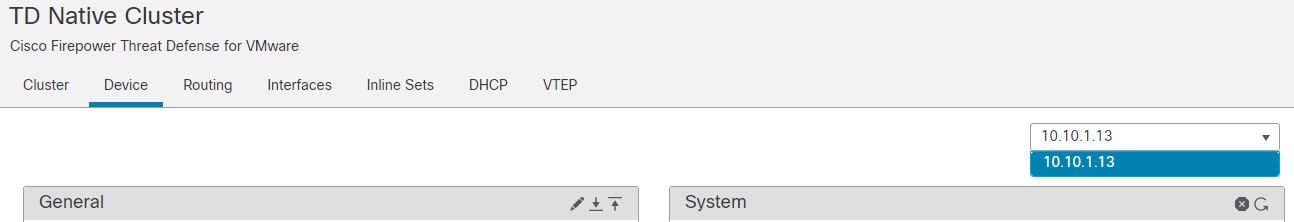
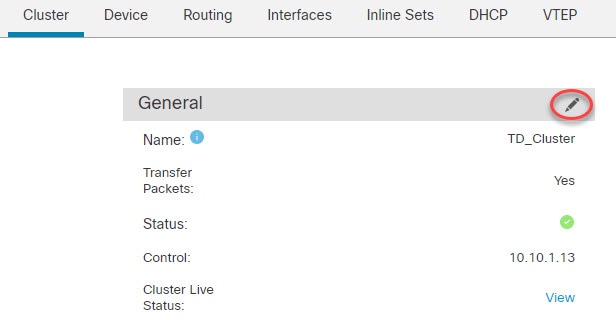
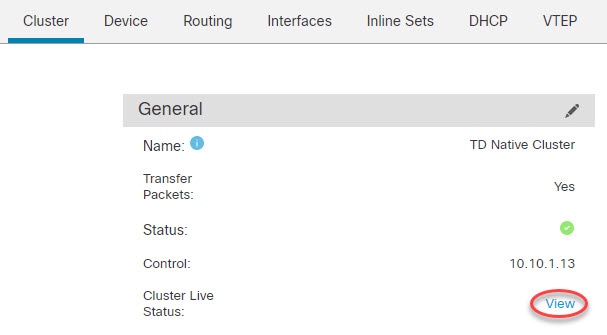
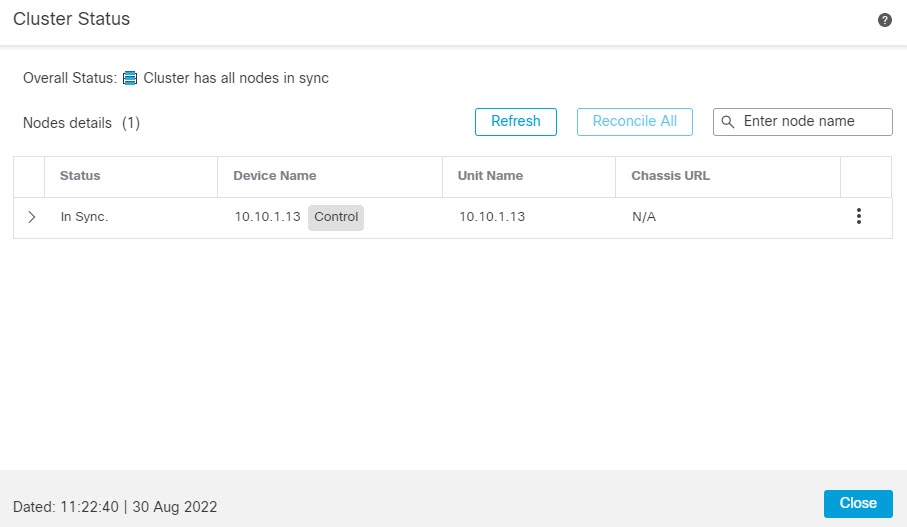
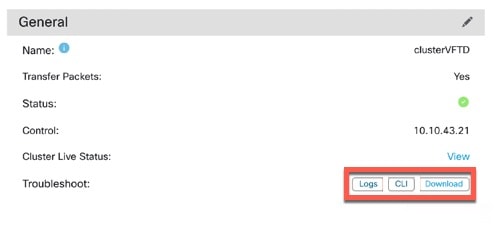
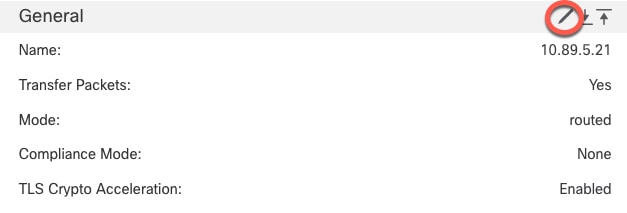
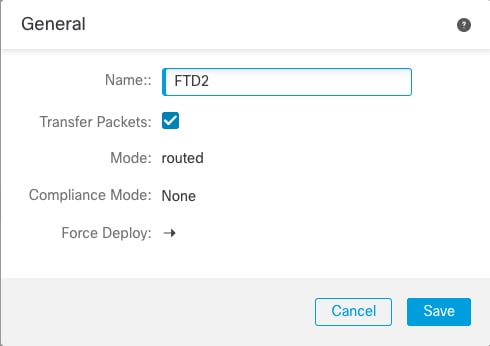
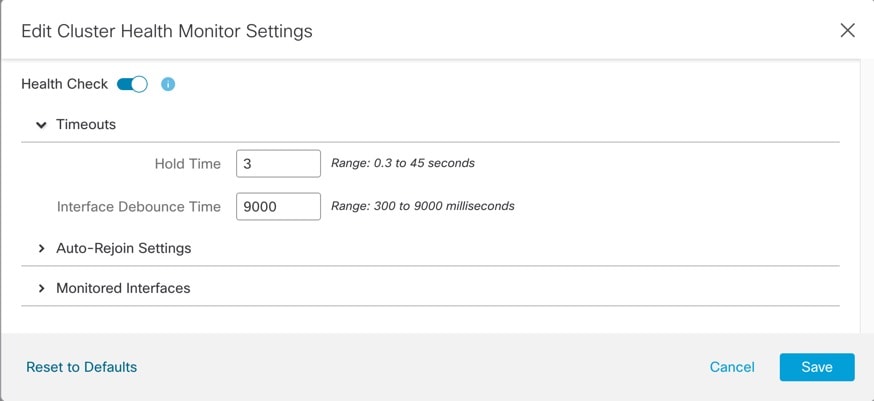
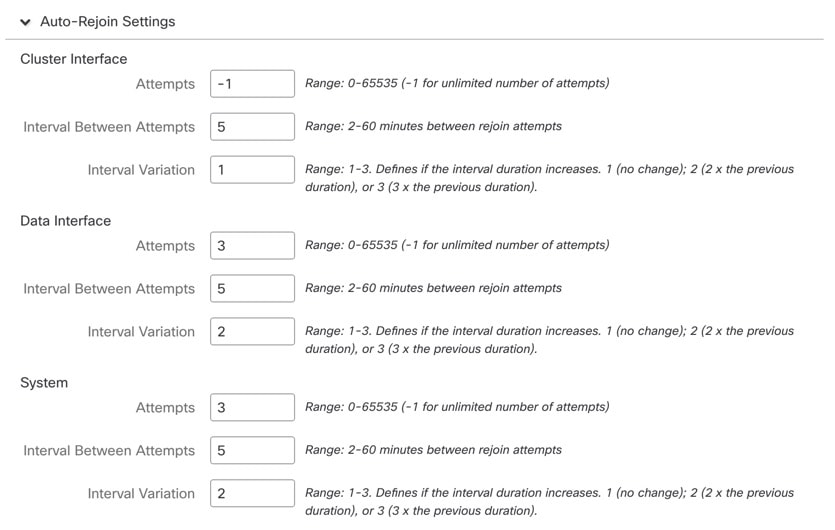
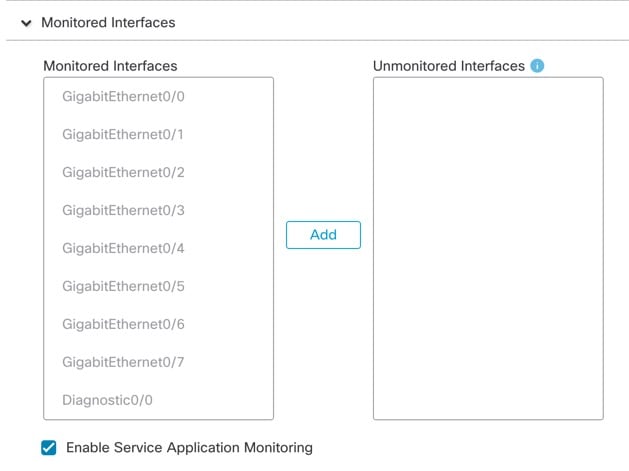
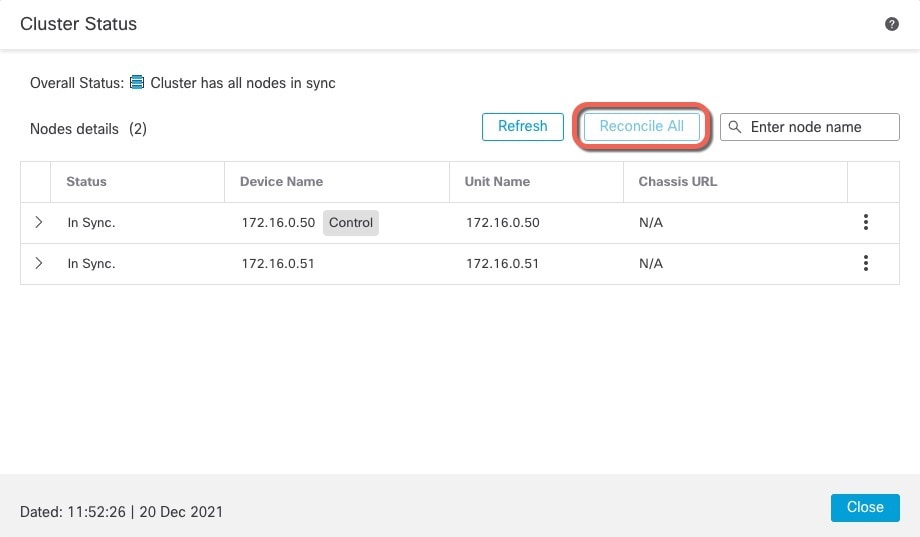
 ) icon or from the , click Add, choose the Cluster page General area Cluster Live Status link.
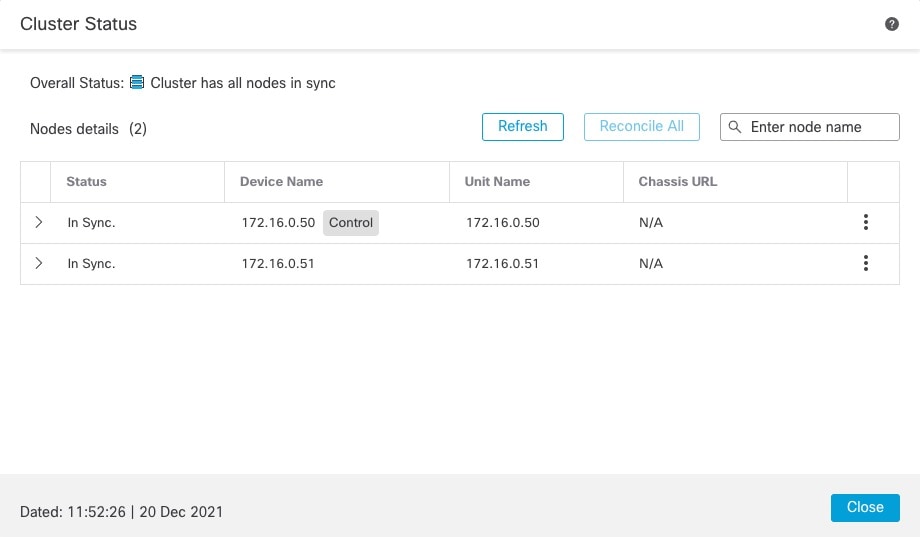
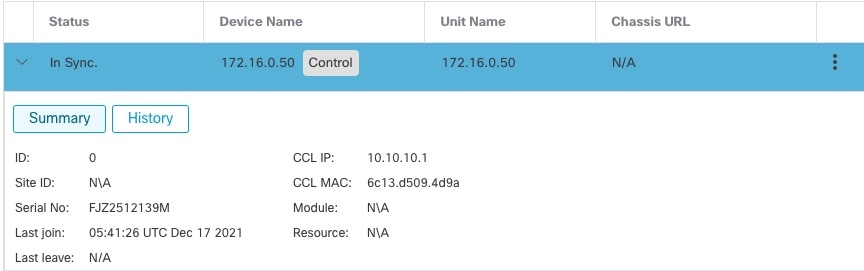
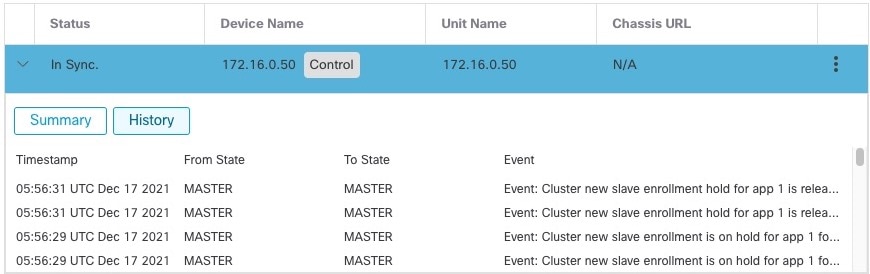
 ) > Tasks page.


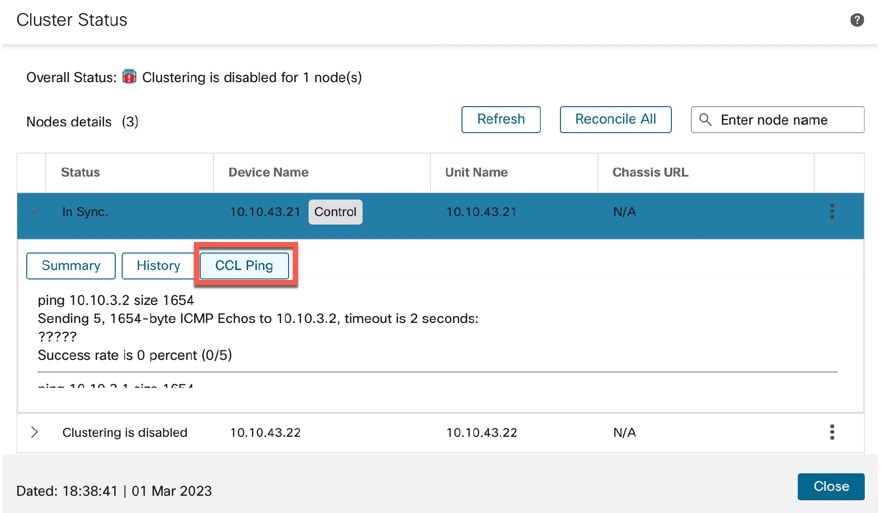
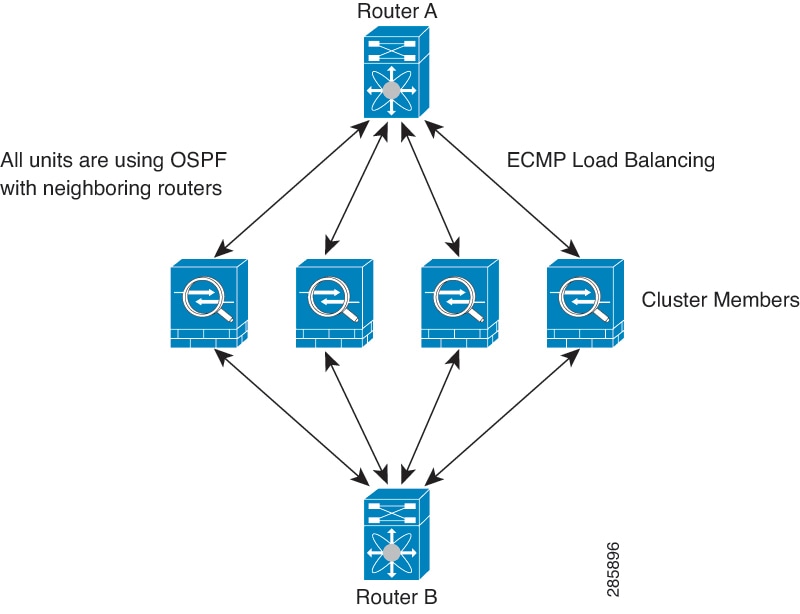
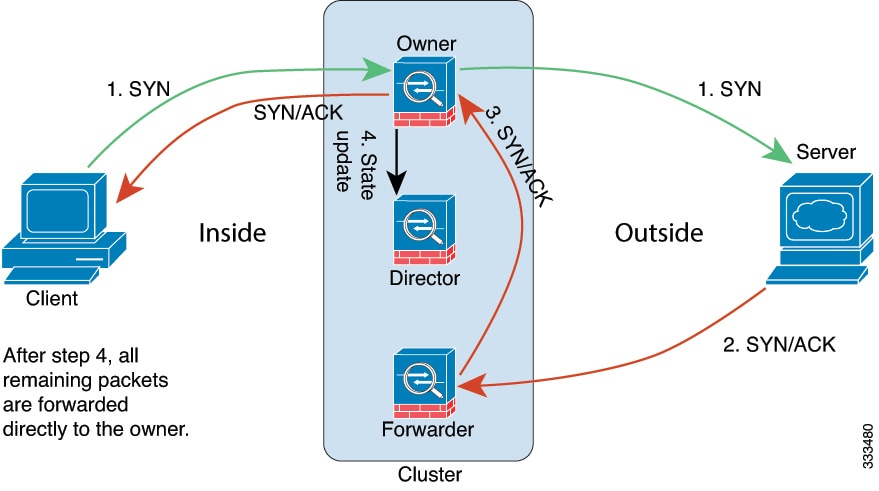
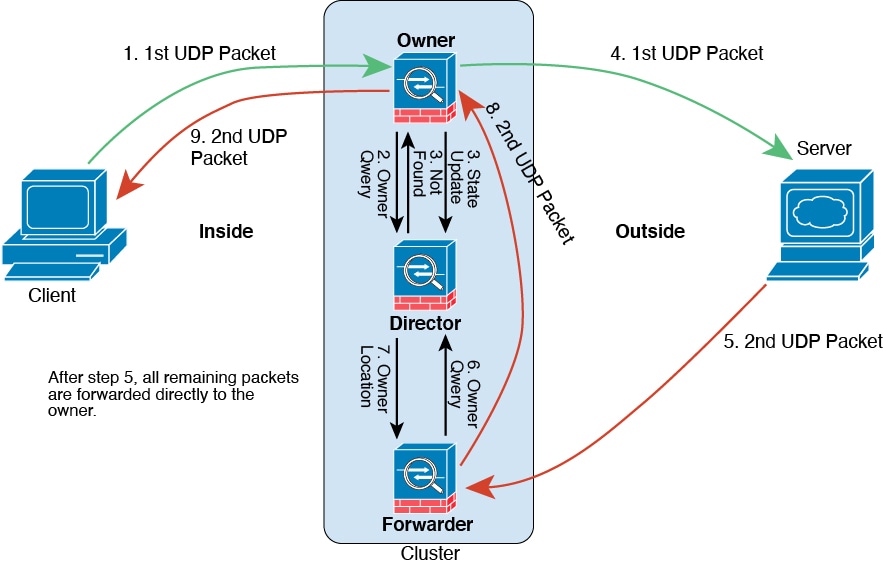
 Feedback
