Failed to read compression bits from bucket
Available Languages
Applicability
Splunk Enterprise 9.3.2Description
This error was encountered when running a search, where the following message was found:
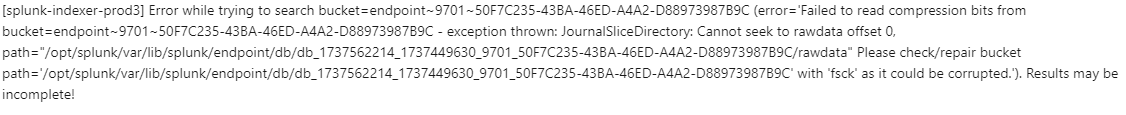
As a result, searches are unable to be completed on that specific index.
This is an indexer cluster with 10 nodes and it's only happening with one node
Investigation
Several steps were tried as to find the location of the bucket both on the web GUI and the CLI, the steps tried are shown down below:
| dbinspect index=main corruptonly=false
| where endEpoch=1737562214 AND startEpoch=1737449630
| dbinspect index=* corruptonly=true | search state!=hot
$SPLUNK_HOME/bin/splunk cmd splunkd fsck scan --one-bucket --bucket-path=/opt/splunk/var/lib/splunk/workday/db/db_1734531949_1734517898_40_50F7C235-43BA-46ED-A4A2-D88973987B9C --include-rawdata
This however, was to no avail as no apparent results were found, as such the bucket was found by looking into the diag by going into the CLI of the Splunkbot since the web GUI would not show any results, the identified bucket was 50F7C235-43BA-46ED-A4A2-D88973987B9C. This only applies to this bucket as at the time only one diag was available, as such it was recommended to run the following command to see if any other bucket showed corruption:
splunk fsck scan --all-bucketsSince no other buckets were found it was then advised to run a repair by doing the following steps:
- Stop the splunkd service on the indexer.
- [Strongly recommended] Make a backup copy of the corrupt bucket(s).
- It is not unusual to move the corrupt bucket(s) to a sandbox environment to minimize downtime in the production indexer. If this is the case, make sure the sandbox server runs an identical Splunk version with an identical index directory structure. The repair procedure is otherwise very similar to in-situ repair.
- Repair the bucket as follows:
splunk rebuild path:*
Or
$SPLUNK_HOME/bin/splunk fsck repair --one-bucket --debug --recover-rawdata --bucket-path=<bucketPath>
This seemed to work on some way, as the repair process was now ongoing, this lasted for about 3 days and it was not finished since the system was interrupted by an OS update, as such the issue was not fixed. A command was ran to see if the number of corrupted buckets had decreased, this was not the case and instead the following message appeared:
[root@splunk-indexer-prod3 ~]# /opt/splunk/bin/splunk fsck scan --all-buckets-all-indexes 2>&1 | grep Corruption | sort | uniq -c
1218 Corruption: Cannot get slices.dat count
2 Corruption: corrupt slicesv2.dat or slices.dat
1 Corruption: count mismatch tsidx=138 source-metadata=3
1 Corruption: count mismatch tsidx=155 source-metadata=61
1 Corruption: count mismatch tsidx=164 source-metadata=369
1 Corruption: count mismatch tsidx=16 source-metadata=1502
1 Corruption: count mismatch tsidx=297 source-metadata=129
1 Corruption: count mismatch tsidx=393 source-metadata=26
Resolution
To solve the issue execute the following command:
splunk fsck repair --one-bucket --include-rawdata --index-name=endpoint --bucket-path=/opt/splunk/var/lib/splunk/endpoint/db/db_1737562214_1737449630_9701_50F7C235-43BA-46ED-A4A2-D88973987B9C --ignore-read-error/--recover-rawdataWhere "--bucket-path=<bucket path>" and "--index-name=<affected index name>"
This repair took a couple minutes but after that a search was performed on the index and the error message was no longer present.
Revision History
| Revision | Publish Date | Comments |
|---|---|---|
1.0 |
29-Sep-2026
|
Initial Release |
 Feedback
Contact Cisco
- Open a Support Case

- (Requires a Cisco Service Contract)