Search Head replication issue in SHC
Available Languages
Applicability
Splunk EnterpriseDescription
The Search Head Cluster can fall out of sync with what the captain has listed as configuration updates for various reasons: unsuspected outages, network issues, and large size for replication are just a few of the reasons this issue can occur.Running the following below command will re-sync the SH cluster:
./splunk resync shcluster-replicated-config
Note: The above command should be run on every SH member excluding the captain.
Investigation
Found the below ERROR logs under Splunkd.log:
ERROR ConfReplicationThread [124243 ConfReplicationThread] - Error pulling configurations from captain=https://spk-sh02.cc.swin.edu.au:8089, consecutiveErrors=37802 msg="Error in fetchFrom, at=6eaeca38b456d12c02681d86dcf1153682a255f0: Non-200 status_code=500: cannot find op_id=6eaeca38b456d12c02681d86dcf1153682a255f0 in repo=https://spk-sh02.cc.swin.edu.au:8089": Search head cluster member (https://spk-sh03.cc.swin.edu.au:8089) is having problems pulling configurations from the search head cluster captain (https://spk-sh02.cc.swin.edu.au:8089). Changes from the other members are not replicating to this member, and changes on this member are not replicating to other members. Consider performing a destructive configuration resync on this search head cluster member.
WARN AdminHandler:TCP [55495 ConfReplicationThread] - TCP Server configs not changed. Skipping TCP Server reload. To force reload add requireServerRestart=true arg for endpoints /data/inputs/tcp/raw/_reload, /data/inputs/tcp/cooked/_reload, servicesNS/admin/ssl/_reload and data/inputs/tcp/ssl/_reload. Example /services/data/inputs/tcp/raw/_reload?requireServerRestart=true. Reload SSL certificates without terminating existing connections, 'services/data/inputs/tcp/ssl/_reload?requireServerRestart=true&terminateConnections=false'
Ran the following command to check the SH cluster status:
./splunk show shcluster-status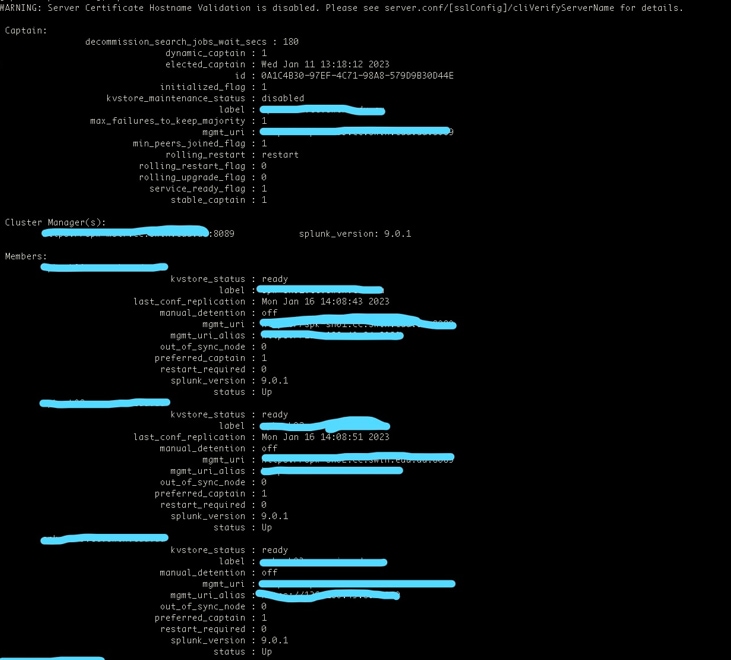
Resolution
Run the below search query:
index=_internal (OR'd SH list) source=*conf.log* data.task=addCommit | spath output=filename path=data.asset_uri{3} |fields filename, data.asset_id |timechart usenull=false limit=0 count by filename
Running the above search query shows 144 events over a 4-hour period. Disabled or slowed down the replication for a lot of the .csv lookup files that were generating. Stopped the SH cluster from out of synchronization.
Related Links
How-to-resolve-error-quot-Error-pulling-configurations
Revision History
| Revision | Publish Date | Comments |
|---|---|---|
1.0 |
29-Sep-2026
|
Initial Release |
 Feedback
Contact Cisco
- Open a Support Case

- (Requires a Cisco Service Contract)