Event Processing Queues Blocked
Available Languages
Applicability
Splunk EnterpriseDescription
On-boarding some data directly to Indexers and some sources are sending the data via heavy forwarders.Investigation
1. In splunkd.log there are linebreaking and AggregatorMiningProcessor errors for few sourcetypes.
WARN  AggregatorMiningProcessor - Breaking event because limit of 256 has been exceeded - data_source="/path/to/the/logs/", data_host="hostname.com",
data_sourcetype="sourcetype_name"WARN  AggregatorMiningProcessor - Breaking event because limit of 1000 has been exceeded - data_source="/path/to/the/logs/"", data_host="other_hostname.com",
data_sourcetype="other_sourcetype_name"
2. The Indexing Performance dashboard shows "Aggregator" Splunk Processor is taking high CPU.
3. Fixing the sourcetypes that were causing the errors didn't resolve (errors gone, issue remains).
4. There is a bottleneck in the aggregation queue, pstack shows the aggregation processor is busy on merging the lines into one events, creating a bottleneck.
This issue happens when the aggregation processor is merging a big number of lines into a single event. From the code, whenever there is one line that needs to be merged to current events, there would string::reserve and memory move happened as the following code. So, if there are 1000 lines for one events, there would 1000 times of reserve and memmovecalled.
void CowPipelineData::appendAndReset(CowPipelineData& other)
{
...
            _pd->_rawAsStr.reserve(_pd->_rawSeg.size() + other._pd->_rawSeg.size() + 1);
            append_other_raw:
            _pd->_rawAsStr.push_back('\n');
            _pd->_rawAsStr.append(other._pd->_rawSeg);
...
}
Collect some of sample events which contains the large number of lines, to know which events are causing the issue, to identify the top three sourcetype which has large number of total lines:
| tstats count where index=* OR index=_* by linecount sourcetype
| where linecount > 2
| stats sum(eval(linecount*count)) as totallines by sourcetype
| sort -totallines
Concept:
The reason is:
- we normally have parsing queue as first queue and aggregation queue as the second one.
- parsing queue is to parse the streaming data into lines by default character \r\n if there is no LINE_BREAKER defined.
- Then, the aggregation queue would merge the lines based on the configuration likeTIME_FORMAT or others
- By setting LINE_BREAKER, it can tell Splunk how to parse the streaming data into lines in the parsing phase and
- By setting SHOULD_LINEMERGE = false would indicate the aggregation process should not merge the lines into events.
- So basically, LINE_BREAKER and SHOULD_LINEMERGE = false would be a solution for customer's issue.
Resolution
1. Enable CPU time metrics for agg_processor for debugging purposes by changing the limits.conf as follows:
.../limits.conf
[default]
agg_cpu_profiling = true
2. Run the below search to identify the sourcetype which is putting more pressure on aggregator processor:
index=_internal source=*metrics.log* per_sourcetype_agg_cpu Metrics
| timechart span=10s avg(cpu) by series
3. Setting SHOULD_LINEMERGE to "false" and writing a regex for "LINE_BREAKER" for each sourcetype coming in into search graph. Exp is below which I took it from the Troubleshooting training document.
Note: Screenshot shows search for regex processor: 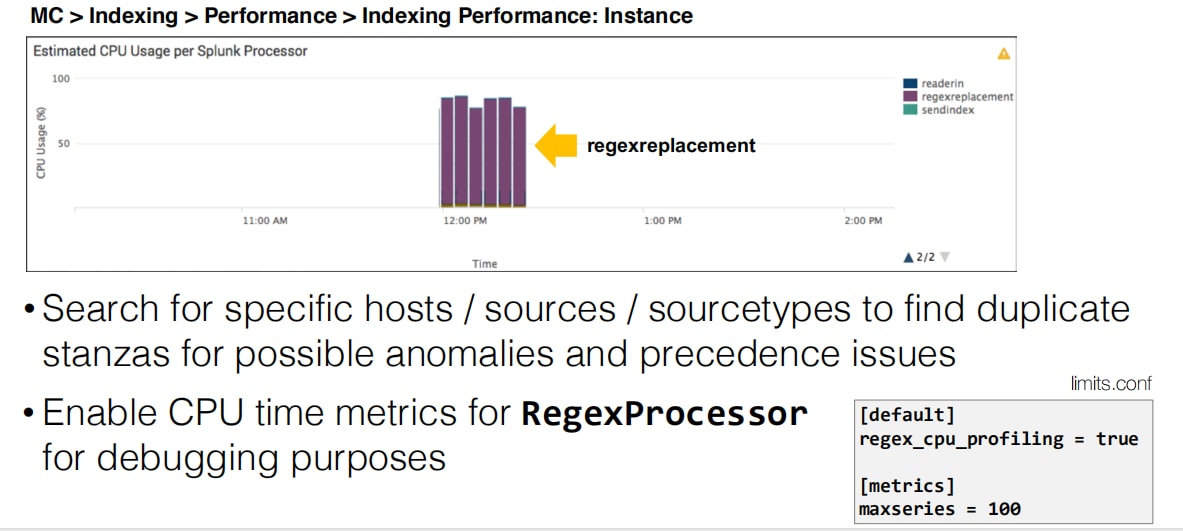
4. Fixing all the sourcetypes like that will resolve the issue of queue fill.
Additional Resource:
The following video from community office hours shows more depth into how to troubleshoot blocked queues.
Related Links
Limits.conf Manualhttps://docs.splunk.com/Documentation/Splunk/7.3.0/Admin/Limitsconf
Revision History
| Revision | Publish Date | Comments |
|---|---|---|
1.0 |
28-Sep-2026
|
Initial Release |
 Feedback
Contact Cisco
- Open a Support Case

- (Requires a Cisco Service Contract)