Bidirectional Forwarding Detection improves path-failure detection for external BGP peers.
Use this reference to understand Bidirectional Forwarding Detection (BFD) support for Border Gateway Protocol (BGP) external routed networks.
Cisco APIC Layer 3 Networking Configuration Guide, Release 6.2(x)
Cisco APIC Layer 3 Networking Configuration Guide, Release 6.2(x)
Bidirectional Forwarding Detection improves path-failure detection for external BGP peers.
Use this reference to understand Bidirectional Forwarding Detection (BFD) support for Border Gateway Protocol (BGP) external routed networks.
A Border Gateway Protocol (BGP) Layer 3 Outside (L3Out) connection enables routing communication between the Cisco ACI fabric and external devices.
Requires router ID and loopback address management to prevent conflicts with L3Out interface subnets.
Supports BGP peers configured under logical node profiles or logical interface profiles.
Uses prefix limits and timer settings to maintain network stability and performance.
Follow these guidelines when you configure a BGP external routed network:
Direct route export: Cisco ACI does not evaluate the originating route type when matching export route map clauses. Explicitly advertise direct routes through the route map. Otherwise, Cisco ACI implicitly denies the routes.
AS override: Use AS override for transit routing between eBGP L3Outs that use the same autonomous system (AS) number. If you enable AS override when the eBGP neighbor uses a different AS number, strip the peer AS from the AS_PATH attribute.
Local AS number: Local AS numbers are supported only for eBGP peering. A local AS number enables a border leaf switch to appear as a member of an additional AS. Control AS-path prepending by using the no-prepend or no-prepend + replace-as setting.
Router ID restrictions: The router ID cannot use the same IP address or subnet as an L3Out routed interface, subinterface, or switched virtual interface (SVI). Beginning with Cisco APIC Release 6.0(4), this restriction does not apply when the Use Router ID for Loopback Address option is disabled.
Multiple L3Outs: If multiple L3Outs that use the same routing protocol are configured on the same leaf switch and in the same VRF, the L3Outs must use the same router ID.
BGP peer definition: Configure a BGP peer under a logical node profile to associate the peer with a loopback IP address. Configure the peer under a logical interface profile to associate it with an interface or subinterface.
Timers: Use the default BGP timers and Bidirectional Forwarding Detection (BFD) for subsecond failure detection. This configuration helps prevent session flapping during CPU-intensive operations.
IPv6 peering: Configure an IPv6 address to enable BGP peering over a loopback interface.
Prefix limits: Use tenant networking protocol policies to monitor and limit route prefixes. The default limit is 20,000 prefixes.
ECMP support: Equal-cost multipath (ECMP) routing is not supported when an L3Out is stretched across parent and tier-2 leaf switches.
Dynamic BGP peering: Overlapping prefixes are not supported. Use the same prefix mask for dynamic peer configurations within the same address range.
When you configure dynamic BGP peering, you cannot use overlapping prefixes that have different masks. For example, 10.10.0.0/16 and 10.10.10.0/24 are not valid because their address ranges overlap and their prefix masks differ.
Use this reference to determine the loopback and routing requirements for each Border Gateway Protocol (BGP) connection type supported by ACI.
|
BGP connection type |
Loopback required |
Loopback same as router ID |
Static or OSPF route required |
|---|---|---|---|
|
Direct iBGP peering |
No |
Not applicable |
No |
|
iBGP loopback peering |
Yes, a separate loopback interface for each L3Out |
No, when multiple L3Outs are configured on the same node |
Yes |
|
Direct eBGP peering |
No |
Not applicable |
No |
|
eBGP loopback peering (multihop) |
Yes, a separate loopback interface for each L3Out |
No, when multiple L3Outs are configured on the same node |
Yes |
Border Gateway Protocol (BGP) peering enables border leaf switches to exchange routing information with external BGP speakers by using internal BGP (iBGP) or external BGP (eBGP).
Supports iBGP and eBGP peering through OSPF, direct connections, or static routes.
Uses the BGP Peer Connectivity Profile to configure supported BGP features.
Applies route control at the BGP protocol level when OSPF provides reachability to the BGP peer addresses.
Cisco ACI supports iBGP and eBGP connections to external peers. Configure the supported BGP features in the BGP Peer Connectivity Profile.
When you use OSPF with BGP peering, OSPF learns and advertises only the routes that provide reachability to the BGP peer addresses. Cisco ACI applies route control configured for the Layer 3 Outside network EPG at the BGP protocol level.
The following table describes the BGP Peer Connectivity Profile features:
Cisco ACI supports only the BGP features listed in the following table. Cisco NX-OS BGP features that are not listed are not supported in Cisco ACI.
|
BGP feature |
Description |
Cisco NX-OS equivalent command |
|---|---|---|
|
Allow Self-AS |
Works with the Allowed AS Number Count setting. |
allowas-in |
|
Disable peer AS check |
Disables the peer AS number check when advertising routes. |
disable-peer-as-check |
|
Next-hop self |
Sets the next-hop attribute to the local peering address. |
next-hop-self |
|
Send community |
Sends the standard community attribute to the neighbor. |
send-community |
|
Send community extended |
Sends the extended community attribute to the neighbor. |
send-community extended |
|
Password |
Configures BGP MD5 authentication. |
password |
|
Allowed AS Number Count |
Specifies the number of occurrences of the local AS number that are permitted in the AS path. This setting works with Allow Self-AS. |
allowas-in |
|
Disable connected check |
Disables the connected-route check for directly connected eBGP neighbors, which permits eBGP peering between loopback interfaces. |
|
|
TTL |
Sets the time-to-live (TTL) value for eBGP multihop connections. This setting is valid only for eBGP. |
ebgp-multihop <TTL> |
|
Autonomous System Number |
Specifies the autonomous system number of the remote peer. |
neighbor <x.x.x.x> remote-as |
|
Local Autonomous System Number Configuration |
Specifies options for the local AS feature, including no-prepend, replace-as, and dual-as. |
|
|
Local Autonomous System Number |
Advertises a different AS number from the AS number assigned to the fabric MP-BGP Route Reflector Profile. This feature is supported only for eBGP neighbors. The local AS number must differ from the AS number in the route reflector policy. |
local-as xxx <no-prepend> <replace-as> <dual-as> |
|
Site of Origin |
The site of origin (SoO) is a BGP extended community attribute that identifies the site from which a route was learned and prevents routing loops. |
soo <value> |
TCP Authentication Option (TCP-AO) is a TCP authentication mechanism that provides cryptographic authentication for TCP segments. In Cisco ACI, TCP-AO is supported for BGP sessions.
TCP-AO improves BGP authentication by supporting:
stronger cryptographic algorithms
multiple active keys in a keychain
send and receive key identifiers
coordinated key rollover
authentication of TCP segments without using TCP-MD5
TCP-AO uses a Message Authentication Code (MAC) to authenticate TCP segments. In Cisco ACI, the default MAC length is 12 bytes, or 96 bits.
TCP-AO uses the following TCP-AO fields during authentication:
| Field | Description |
|---|---|
| KeyID | Identifies the key that the sender uses to authenticate the TCP segment. |
| RNextKeyID | Indicates the next receive key that the sender expects the peer to use. TCP-AO uses this field to coordinate key changes between peers. |
| Message Authentication Code, or MAC | Authenticates the TCP segment. Cisco ACI uses a default MAC length of 12 bytes. |
TCP-AO helps support secure and planned key changes by allowing multiple keys to exist in a keychain. When you configure key lifetimes with an overlap, the BGP session can continue to operate while the peers transition from one key to another.
You cannot configure TCP-AO and BGP password authentication on the same BGP peer. If a BGP peer already uses password authentication, remove the password authentication before you associate a TCP-AO keychain with that peer.
This table compares TCP-MD5 and TCP-AO for BGP authentication.
| Attribute | TCP-MD5 | TCP-AO |
|---|---|---|
| Authentication method | Uses an MD5 digest. | Uses a MAC calculated with a supported cryptographic algorithm. |
| Algorithm support | Supports MD5 only. | Supports AES-128-CMAC, HMAC-SHA-1, HMAC-SHA-256, and HMAC-SHA-256-128. |
| Key rollover | Requires a BGP session reset when the password changes. | Supports coordinated key rollover when key lifetimes overlap. |
| Key management | Uses a single password. | Uses a TCP keychain with one or more keys. |
| Key identifier support | Does not support key identifiers. | Supports send and receive key identifiers. |
TCP-AO uses keychains instead of a single BGP password. A TCP-AO keychain is a tenant-level policy that contains one or more TCP-AO keys. You associate the keychain with a BGP peer to enable TCP-AO authentication for that peer.
Each key defines the authentication parameters that BGP uses to authenticate TCP segments for a specific time period during which the key is valid.
Cisco ACI supports up to 256 keys in a TCP keychain.
A TCP-AO keychain includes one or more keys. Each key includes these parameters.
| Parameter | Description |
|---|---|
| Key ID | Identifies the key within the keychain. Use a unique key ID for each key in the keychain. |
| Key string | Defines the shared secret that TCP-AO uses to generate the MAC. Configure the same key string on both BGP peers. |
| Send ID | Identifies the key that the local peer uses when sending authenticated TCP segments. The supported range is 0 to 255. |
| Receive ID | Identifies the key that the local peer expects to receive from the remote peer. The supported range is 0 to 255. |
| Cryptographic algorithm | Specifies the algorithm that TCP-AO uses to generate the MAC. |
| Include TCP options | Determines if TCP option headers (other than the TCP-AO option itself) are factored into the segment's MAC calculation. Enabling this ensures that modifications to the TCP options header will invalidate the MAC. |
| Start time | Specifies the time when the key becomes valid. |
| End time | Specifies the time when the key expires. You can configure a key to remain valid indefinitely. |
Cisco ACI supports the following TCP-AO cryptographic algorithms for BGP:
AES-128-CMAC
HMAC-SHA-1
HMAC-SHA-256
HMAC-SHA-256-128
Use a SHA-256-based algorithm for stronger authentication unless your deployment requires another supported algorithm for interoperability with the remote peer.
TCP-AO key rollover allows BGP peers to transition from one TCP-AO key to another without resetting the BGP session. Key rollover is useful when you need to rotate keys periodically for operational or security requirements.
TCP-AO uses the KeyID and RNextKeyID fields to coordinate key changes between peers. The sender uses the KeyID field to identify the key used to authenticate the TCP segment. The sender uses the RNextKeyID field to indicate the next receive key that it expects the peer to use.
For a hitless key rollover, the old key and the new key must overlap for at least 15 minutes. During this overlap period, both keys are valid, which allows both peers to transition to the new key without interrupting the BGP session.
If the old key expires before the new key becomes valid, or if the peers do not have matching key information, the BGP session can reset.
When you configure TCP-AO key rollover, follow these guidelines:
Configure the new key before the current key expires.
Configure at least 15 minutes of overlap between the old key and the new key.
Ensure that both BGP peers have matching key configuration.
Ensure that the Send ID on one peer matches the Receive ID expected by the other peer.
Ensure that the Receive ID on one peer matches the Send ID used by the other peer.
Do not allow all keys in a key chain to expire.
The following example shows a planned key rollover with a 15-minute overlap.
| Key | Start time | End time | Purpose |
|---|---|---|---|
| Key 1 | 10:00 | 10:30 | Existing active key |
| Key 2 | 10:15 | Infinite | New key |
In this example, Key 1 and Key 2 overlap from 10:15 to 10:30. This 15-minute overlap allows the peers to transition from Key 1 to Key 2 without resetting the BGP session.
Use this topic to identify which BGP peer types support TCP-AO authentication.
TCP-AO support is consistent with existing BGP password support where applicable. Some BGP peer types do not support TCP-AO in Cisco ACI Release 6.2(3).
| BGP peer type | Configuration support from APIC GUI | BGP password support | TCP-AO support |
|---|---|---|---|
| User VRF L3Out | Yes | Yes | Yes |
| Intra-Pod MP-BGP sessions | No | No | No |
| MPOD overlay sessions | Yes, during initial pod setup | Yes | Not supported in 6.2(3) |
| BGP underlay, spine to IPN and remote leaf to IPN | Yes | Yes | Yes |
| MSITE underlay | Yes | Yes | Not supported in 6.2(3) |
| Multi-Site overlay | Yes | Yes | Not supported in 6.2(3) |
| ACI BGW underlay and overlay towards NX-OS BGW | Yes | Yes | Yes |
| ACI BGW towards spines | No | No | No |
| SR-MPLS underlay BGP-LU | Yes | Yes | Yes |
| SR-MPLS overlay | Yes | Yes | Yes |
| ARL | No | No | No |
| Floating L3Out BGP sessions towards the CN | Yes | Yes | Yes |
TCP-AO uses a TCP keychain and requires matching configuration on both BGP peers. A mismatch in keychain parameters can prevent the BGP session from coming up or can cause the session to reset.
Follow these guidelines and limitations when you configure TCP-AO in Cisco ACI:
Configure the TCP keychain and keys on both BGP peers.
Configure the same key string on both BGP peers.
Configure the same cryptographic algorithm on both BGP peers.
Configure the same include TCP options setting on both BGP peers.
Configure matching key lifetimes on both BGP peers where possible.
Configure the send ID on one peer to match the receive ID on the other peer.
Configure at least 15 minutes of overlap between the old key and the new key for key rollover.
Configure TCP-AO keychains in the same tenant as the BGP peer or in the common tenant.
Use TCP-AO only with BGP. TCP keychains cannot be used by classic keychain or MACsec keychain clients.
Follow these guidelines when configuring TCP-AO keychains:
A TCP keychain supports 256 keys.
The Send ID and Receive ID range is 0 to 255.
The Send ID and Receive ID must be unique for each key in a keychain.
The Key string, Send ID, Receive ID, Send lifetime, and Cryptographic algorithm are required for a key to become active.
The include TCP options setting is optional.
Type-7 keychain encryption is supported.
Type-6 keychain encryption is not supported.
The same keychain name cannot be used for TCP keychains, classic keychains, and MACsec keychains.
Follow these guidelines when configuring TCP-AO on BGP peers:
TCP-AO and BGP password authentication cannot be configured on the same BGP peer.
Changing the TCP-AO keychain name on an established BGP session causes the session to reset.
Modifying the Key string, Send ID, Receive ID, or cryptographic algorithm of the key that is currently used by a TCP-AO session causes the BGP session to reset.
If an incoming packet is authenticated with a key that is not active or installed, segment loss can occur and the BGP session can reset.
If the key currently used for transmission expires before rollover completes, the BGP session can reset.
A TCP-AO keychain configured in the common tenant can be used by BGP sessions in other tenants.
APIC raises a fault when it attempts to push a TCP-AO policy to a node that does not support TCP-AO. Before you downgrade Cisco APIC to a release earlier than 6.2(3), remove all TCP-AO configurations.
For more information refer to Mixed mode compatibility for TCP-AO from Cisco APIC release 62x or later
Use this task to create a TCP-AO keychain policy that can be associated with a BGP peer.
A TCP-AO keychain contains one or more keys. Each key has a send lifetime. To support key rollover, configure at least two keys with overlapping send lifetimes.
You can create the TCP-AO keychain under a user tenant, the infra tenant, or the common tenant. A TCP-AO keychain configured under the common tenant can be used by BGP peers in other tenants.
Ensure the following:
The tenant is configured.
For user VRF L3Out BGP peers, the L3Out and BGP peer are configured.
For BGP infra peers, the infra tenant BGP underlay configuration is configured.
Determine the key string, cryptographic algorithm, send ID, receive ID, and send lifetime for each key.
If you are configuring key rollover, determine the overlap between the current key and the next key. The overlap must be at least 15 minutes.
Follow these steps to configure a TCP-AO keychain using the GUI.
The TCP-AO keychain policy is created. You can associate this policy with a supported BGP peer.
Use this task to enable TCP-AO authentication for a BGP peer by associating a TCP-AO keychain with the BGP peer.
TCP-AO is configured on the BGP peer. The TCP-AO keychain policy must exist in the same tenant or in the common tenant.
TCP-AO and BGP password authentication are mutually exclusive. Remove the BGP password before associating a TCP-AO keychain with the BGP peer.
Ensure the following:
The tenant, VRF, and L3Out are configured.
The BGP peer is configured.
The TCP-AO keychain policy is configured in the same tenant or in the common tenant.
TCP-MD5 password authentication is not configured on the same BGP peer.
The peer router has a matching TCP-AO configuration.
Follow these steps to associate a TCP-AO keychain with a BGP peer.
APIC associates the TCP-AO keychain with the BGP peer. BGP uses the active key in the keychain to authenticate TCP segments for the BGP session.
Use this task to enable TCP-AO authentication for supported BGP infra peers, such as BGP underlay peers between spines and the IPN or between remote leaf switches and the IPN.
Cisco ACI supports TCP-AO for BGP underlay peer types that support BGP password authentication. The configuration flow for infra peers is described as the same TCP keychain creation process, followed by associating the policy under the BGP infra peer profile.
Ensure the following:
The infra tenant BGP underlay configuration is configured.
The TCP-AO keychain policy is configured in the infra tenant or in the common tenant.
TCP-MD5 password authentication is not configured on the same BGP infra peer.
The peer router has a matching TCP-AO configuration.
Follow these steps to associate a TCP-AO keychain with a BGP infra peer.
On the menu bar, choose Tenants infra.
In the Navigation pane, choose Networking L3Outs L3Out_name.
Navigate to the BGP infra peer profile.
Click BGP infra peer that you want to configure.
Verify that BGP password authentication is not configured for the peer.
In the TCP-AO keychain field, choose the TCP-AO keychain policy.
Configure the Include TCP Options setting if required.
Click Submit.
APIC associates the TCP-AO keychain with the BGP infra peer.
Use this topic to verify whether TCP-AO is enabled for a BGP peer and whether the expected keys are active
Use the show bgp ipv4 unicast neighbors peer-ip vrf vrf-name command to verify that TCP-AO authentication is configured for a BGP peer.
Example:
show bgp ipv4 unicast neighbors 192.0.2.2 vrf t1:ctx1
Look for output similar to this:
TCP AO authentication is set: t1:kc1
Active TCPAO Keys:
Sndid: 1 Rcvid: 2 InListenFD InPeerFD RNext CurrUse the show bgp internal neighbor peer-ip vrf vrf-name command to verify TCP-AO keys installed for the peer and listening sockets.
show bgp internal neighbor 192.0.2.2 vrf t1:ctx1
Look for fields such as:
•	Total TCPAO keys for Peer
•	Sndid
•	Rcvid
•	alg_name
•	currentKey
•	nextKey
•	excl-tcp-options
•	Total TCPAO keys for Listening Socket
Use the show bgp internal tcpao command from vsh to display internal TCP-AO key information.
vsh -c "show bgp internal tcpao"
Look for fields such as:
•	Peer
•	VRF
•	Sndid
•	Rcvid
•	alg_name
•	incl-tcp-options
Use the show key chain command to verify TCP keychain status.
BGP additional paths is a routing feature that enables a BGP speaker to advertise or receive multiple paths for the same prefix without replacing the existing path.
Enables BGP peers to negotiate whether they can advertise or receive multiple paths for each prefix.
Adds a 4-byte path identifier to the Network Layer Reachability Information (NLRI) to distinguish multiple paths for the same prefix.
The following limitations apply to BGP additional paths:
Cisco APIC supports only the receive capability.
If the BGP session is already established, changes to the receive configuration take effect only after the session is reset.
The following figure shows the BGP additional paths receive capability:
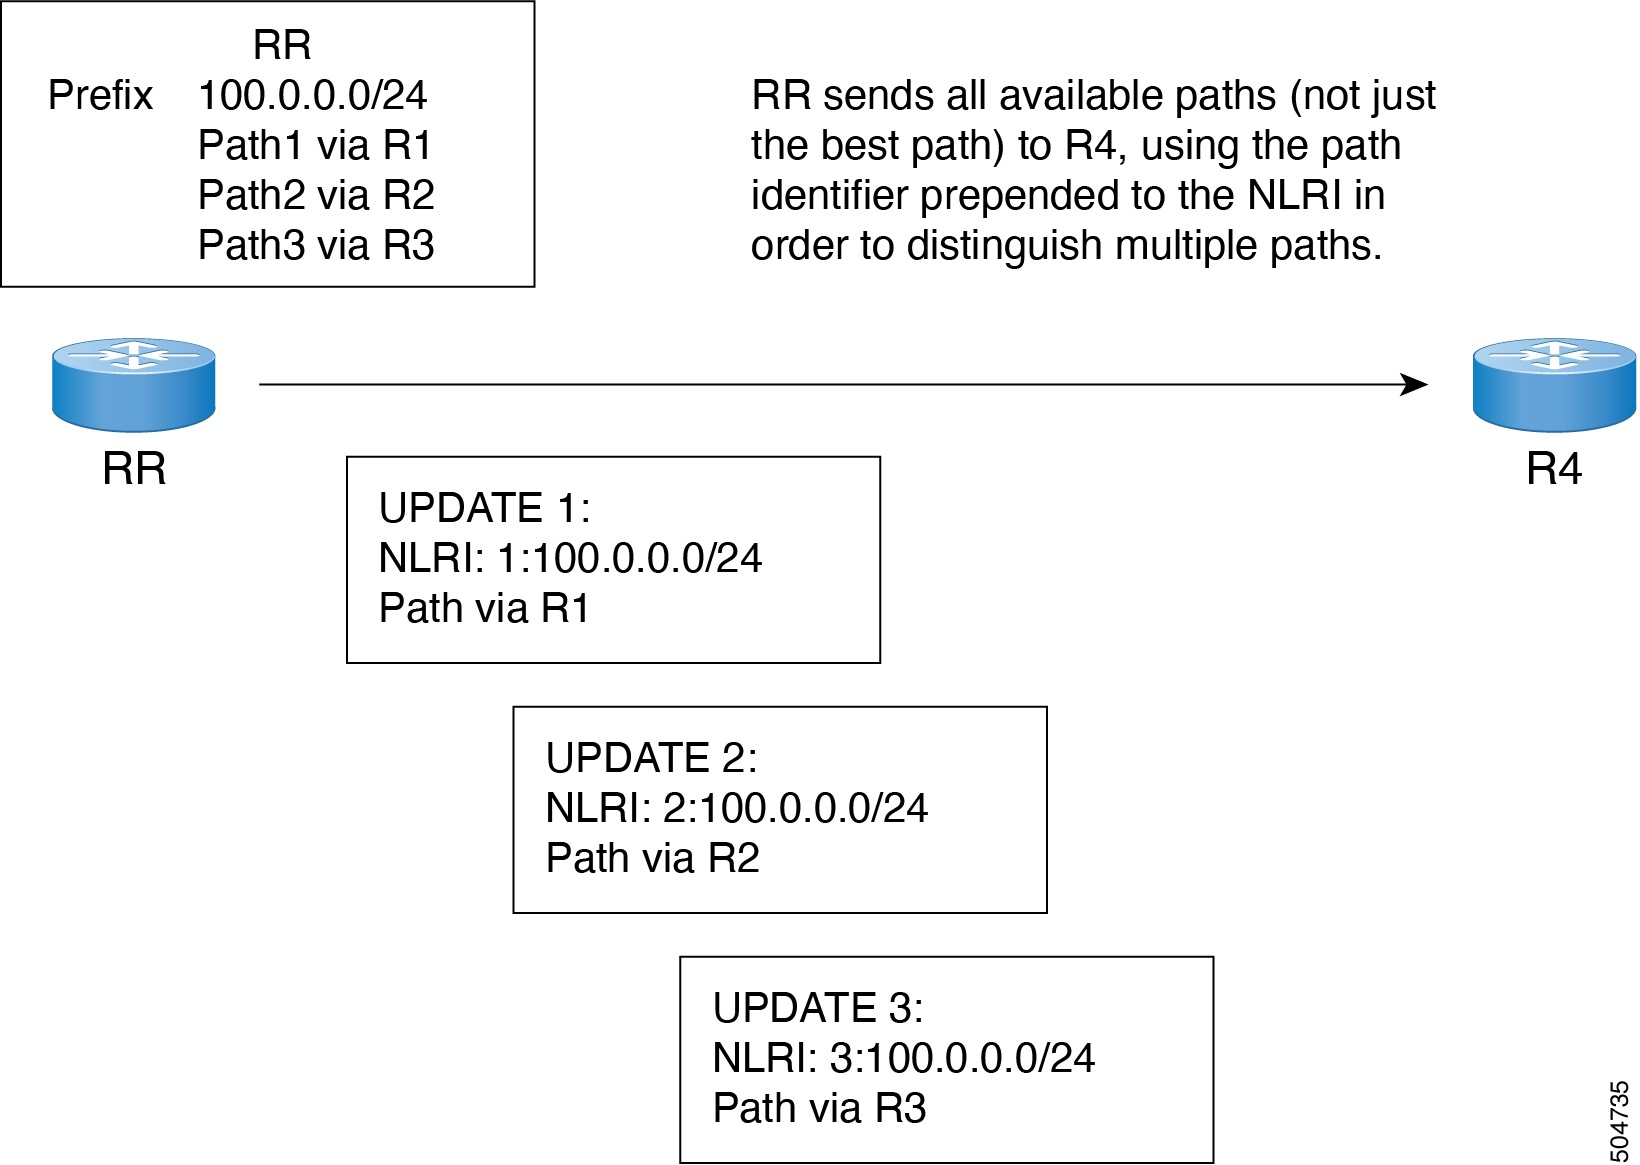
Before support for the additional paths receive capability, BGP advertised only the best path, and a BGP speaker accepted only one path for a prefix from each peer. If the speaker received multiple paths for the same prefix during the same session, the most recent advertisement replaced the previous path.
Use the procedures in this reference to configure BGP external routed networks.
Create the tenant, VRF, and bridge domain for the BGP L3Out. When you create the VRF, check the Configure BGP Policies check box.
eBGP Max Path: Defines the maximum number of equal-cost paths the fabric installs in the routing table for routes learned from external eBGP peers.
iBGP Max Path: Defines the maximum number of equal-cost paths the fabric installs in the routing table for routes learned from external iBGP peers. This setting also controls the maximum number of equal-cost paths the fabric installs in the routing table for routes learned internal to the fabric via MP-BGP from border leaf switches.
BGP Local Max ECMP: Specifies the maximum number of next-hops the fabric propagates when redistributing static or OSPF routes into BPG. This setting is used with next-hop propagation.
iBGP Max ECMP also applies to internal BGP routes redistributed in the fabric via MP-BGP. For example, the maximum number of next-hops that will be installed on a non-border leaf switch for an external prefix.
It allows the fabric to perform load balancing across multiple BGP paths to the same destination prefix. If you have multiple BGP paths to a destination, BGP will select up to the configured number of paths (e.g., 8) and install them as equal-cost paths in the routing table. It is found under the BGP Address Family context as eBGP Max ECMP and iBGP Max ECMP.Local Max ECMP is used with the Next Hop Propagation and Multipath route-map actions. By default, when a border leaf redistributes a static or OSPF route into MP-BGP, it replaces the route's next hop with its own tunnel endpoint (TEP) address. When Next Hop Propagation is enabled, the border leaf preserves the route's original next-hop information during redistribution. Enabling Multipath allows it to redistribute multiple eligible equal-cost next hops, up to the value configured for Local Max ECMP.
The default Local Max ECMP value is 0, which disables local multipath redistribution. Releases earlier than Cisco ACI 6.2(3) support a maximum value of 16. Beginning with release 6.2(3), the maximum value is 64. Values greater than 16 should be used only when the APIC cluster and every leaf and spine switch in the fabric run release 6.2(3) or later.
The policy is configured under:
Tenantstenant Policies Protocol BGP BGP Address Family Context.
It is then associated with the appropriate IPv4 or IPv6 address family under the VRF's BGP Context Per Address Family configuration.
Preserving and advertising multiple external next hops allows other fabric leaf switches to forward traffic toward those next hops without first sending it through the redistributing border leaf. This can improve path diversity, load distribution, and resiliency while avoiding suboptimal hairpinning. Although commonly associated with Floating L3Out designs, Local Max ECMP can also be used in other designs that require multipath redistribution and next-hop propagation.
The 64-way ECMP support is version-dependent. Nodes running firmware 6.2.3 or later support the full range (0-64). For the nodes running firmware prior to 6.2.3, the Policy Manager will automatically clamp the value to 16, even if you configure a higher value, regardless of the APIC configuration.
For more information refer to Mixed mode compatibility for ECMP scaling from release 62x and later
Create the appropriate tenant and BGP external routed network.
Use this reference to configure AS path prepending and influence inbound routing paths.
AS path prepending is a BGP mechanism that increases the length of the AS-path attribute by adding one or more autonomous system (AS) numbers to the beginning of the path.
Applies only to outbound route advertisements through route maps.
Supports eBGP sessions but not iBGP sessions.
Influences the best-path selection process of a remote BGP peer.
A BGP peer can influence best-path selection on a remote peer by increasing the length of the AS-path attribute. The remote peer typically prefers a route with a shorter AS path over an otherwise equivalent route.
AS path prepending supports the following methods:
|
Method |
Description |
|---|---|
| Prepend |
Prepends the specified AS number to the AS path of a route matched by the route map.
|
| Prepend-last-as |
Prepends the last AS number in the path from 1 through 10 times. |
The following table describes the selection criteria for AS path prepending:
|
Criterion |
Value |
Behavior |
|---|---|---|
| Prepend | 1 | Prepends the specified AS number. |
| Prepend-last-as | 2 | Prepends the last AS number to the AS path. |
| DEFAULT | Prepend(1) | Prepends the specified AS number. |
Create the tenant in which you want to configure the route map set rule.
Use the procedures in this reference to configure AS override for BGP external routed networks.
BGP autonomous system (AS) override is a routing feature that replaces the AS number of the originating router in the AS path of an outbound route with the AS number of the sending BGP router.
Prevents BGP loop-prevention mechanisms from rejecting routes when different sites use the same AS number.
Requires the Disable Peer AS Check option to be enabled at the same time.
Supports separate configuration for IPv4 and IPv6 address families.
BGP prevents routing loops by examining the AS path of each received route. If the receiving router finds its own AS number in the AS path, it rejects the route because the route might have passed through the same AS previously.
This loop-prevention behavior can prevent connectivity between sites that use the same AS number and connect through another autonomous system. When one site advertises a route, another site with the same AS number rejects the route because its AS number appears in the AS path.
Beginning with Cisco APIC Release 3.1(2m), you can enable BGP autonomous system override to prevent this route rejection. You must also enable Disable Peer AS Check.
AS override replaces the AS number of the originating router in the AS path of an outbound route with the AS number of the sending BGP router. You can enable the feature separately for the IPv4 and IPv6 address families.
AS override is supported with GOLF and non-GOLF Layer 3 configurations.
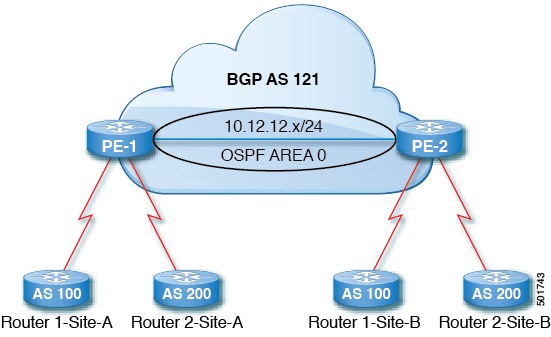
Router 1 and Router 2 represent two customers with multiple sites, Site-A and Site-B. Customer Router 1 uses AS 100, and Customer Router 2 uses AS 200.
The figure shows the following AS override process:
Router 1-Site-A advertises route 10.3.3.3 with AS 100.
Router PE-1 propagates the route internally to PE-2 with AS 100 in the AS path.
Router PE-2 replaces AS 100 in the AS path with AS 121 and advertises prefix 10.3.3.3.
Router 2-Site-B accepts the update for prefix 10.3.3.3.
Create the tenant, VRF, and bridge domain.
Create the non-GOLF external routed network, logical node profile, and BGP Peer Connectivity Profile.
On the menu bar, choose .
In the navigation pane, choose the applicable BGP Peer Connectivity Profile.
In the work pane, under Properties for the BGP Peer Connectivity Profile, configure the BGP Controls:
Click Submit.
Use the procedures in this reference to configure BGP timer values for individual VRFs and nodes.
The per-VRF and per-node BGP timer feature provides granular control of BGP timer values for a specific VRF on an individual node.
Supports different BGP timer configurations for individual nodes in the same VRF.
Uses bgpProtP and bgpCtxPol to manage BGP timer policies.
Stores timer attributes such as holdIntvl, kaIntvl, and maxAsLimit in the bgpDom managed object (MO).
The system selects the BGP timer policy for a node by using the following hierarchy:
If bgpProtP references a bgpCtxPol, use that policy.
Otherwise, if the corresponding fvCtx references a bgpCtxPol, use that policy.
Otherwise, use the default policy under the tenant, such as uni/tn-<tenant>/bgpCtxP-default.
If the tenant does not have a default policy, use the preprogrammed default policy under the common tenant, such as uni/tn-common/bgpCtxP-default.
A per-VRF and per-node BGP timer configuration requires a valid Layer 3 Outside (L3Out) configuration that includes the following managed objects: fvTenant, fvCtx, l3extOut, l3extInstP, LNodeP, and bgpRR.
A node-specific BGP timer policy overrides the BGP timer policy associated with the VRF for that node.
Create the tenant and VRF.
A BGP timer policy conflict causes a fault when different Layer 3 Outside (L3Out) configurations associated with the same VRF apply different BGP timer policies to the same node.
Multiple L3Outs are associated with the same VRF.
The same node is configured under the L3Outs.
Each L3Out applies a different BGP timer policy to the node.
Cisco APIC generates a fault when different L3Outs (l3Out) are associated with the same VRF (fvCtx) on the same node and their bgpProtP objects reference different BGP timer policies (bgpCtxPol).
In the following example, L3Outs out1 and out2 are associated with VRF ctx1. Both L3Outs contain node1. Under out1, the node uses BGP timer policy pol1. Under out2, the same node uses BGP timer policy pol2. Because the policies conflict, Cisco APIC generates a fault.
tn1
        ctx1
        out1
        ctx1
        node1
        protp pol1
        out2
        ctx1
        node1
        protp pol2
To clear the fault, change the configuration so that the L3Outs apply the same BGP timer policy to the node.
Use the procedures in this reference to configure BGP neighbor shutdown and perform a soft reset.
BGP neighbor shutdown and soft reset are neighbor-management features that control BGP sessions and routing table updates.
BGP neighbor shutdown disables or enables the administrative state of a neighbor without deleting the peer configuration.
BGP neighbor soft reset uses route refresh to update inbound or outbound routing information dynamically.
These features are supported beginning with Release 4.2(1).
BGP neighbor shutdown provides behavior similar to the neighbor shutdown command in Cisco NX-OS. Use the policy to disable or enable the administrative state of a BGP neighbor. Disabling the administrative state shuts down the BGP session without deleting the BGP peer configuration.
BGP neighbor soft reset uses the BGP route refresh capability to update inbound and outbound routing information dynamically without relying on stored routing table updates. Use the policy to perform a dynamic inbound or outbound soft reset.
Complete the standard L3Out prerequisites, including the following configurations:
Configure the node, port, functional profile, attachable access entity profile (AEP), and Layer 3 domain.
Configure a BGP route reflector policy to propagate routes within the fabric.
Use the BGP neighbor administrative state to shut down or enable a BGP session without removing the peer configuration.
Create the L3Out and enable BGP:
On the Identity page of the L3Out creation wizard, choose BGP as the routing protocol.
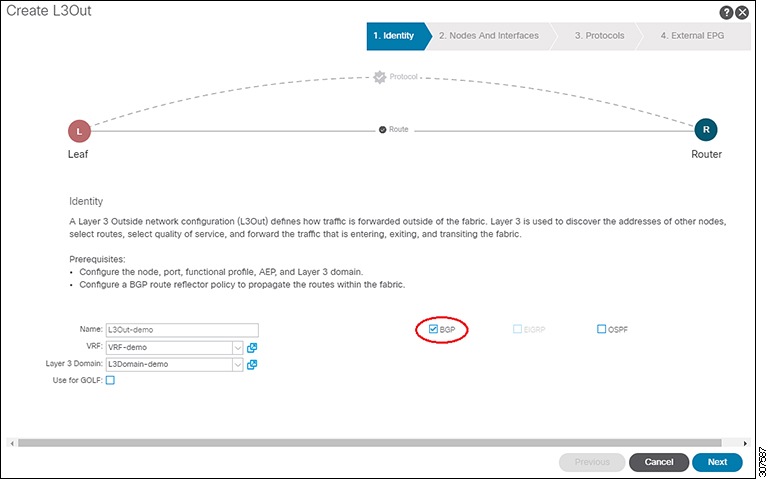
Configure the administrative state of the BGP neighbor:
Complete the standard L3Out prerequisites, including the following configurations:
Configure the node, port, functional profile, attachable access entity profile (AEP), and Layer 3 domain.
Configure a BGP route reflector policy to propagate routes within the fabric.
Create the L3Out and enable BGP:
On the Identity page of the L3Out creation wizard, choose BGP as the routing protocol.
Perform the BGP neighbor soft reset:
Border Gateway Protocol (BGP) graceful restart (GR) helps maintain routing stability while a router restarts its control plane. During the restart, neighboring routers can temporarily retain previously learned routes and continue forwarding traffic while routing protocol updates are suspended.
Cisco Application Centric Infrastructure (ACI) switches operate as GR helpers rather than GR initiators. When a peer performs an operation that triggers graceful restart, such as stateful switchover (SSO), an in-service software upgrade (ISSU), or a BGP process restart, the ACI switch maintains forwarding during the peer's BGP control-plane restart.
During a graceful restart, one router restarts its routing process and initiates the graceful restart operation. A stable peer assists the restarting router by retaining its routes and forwarding state. The stable peer is called a graceful restart receiving device or graceful restart helper.
A graceful restart helper supports nonstop forwarding during a neighboring router's restart. The helper temporarily forwards packets by using stale routing information until the neighbor recovers and the routing adjacency is reestablished. The graceful restart helper capability is enabled by default within a VRF.
Graceful restart uses two primary timers:
Restart timer: The restarting router configures and advertises this timer to indicate the maximum time required to restart its routing protocol. If the timer expires before the restart completes, the helper assumes that the restart failed and removes the stale routes. Because an ACI switch operates only as a helper, you do not configure the restart timer on the ACI switch.
Stale timer: The graceful restart helper configures and uses this timer to determine how long it retains stale routes. For more information, see Stale interval.
During a graceful restart, the helper continues to use routes previously received from the peer but marks them as stale. After the BGP session is reestablished and the routers synchronize their routing information, the helper removes the stale routes and uses the newly received routes.
The Stale Interval timer determines when the helper removes stale routes if the session is not reestablished. This timer is applied locally. The default value is 300 seconds.
Use this reference to identify the peer operations supported by BGP graceful restart helper mode.
In Cisco ACI, BGP graceful restart helper mode supports a peer that performs any of the following operations:
Stateful switchover (SSO)
In-service software upgrade (ISSU)
BGP process restart
During these operations, the Cisco ACI switch acts as the graceful restart helper and maintains forwarding while the peer recovers its BGP state.
BGP peers exchange the graceful restart capability in an OPEN message during initial session establishment. Both the restarting router and its helper, the ACI leaf switch, must exchange this capability to enable graceful restart for the BGP session.
BGP graceful restart (GR) helper mode is enabled by default on Cisco ACI leaf switches. Use this procedure to change the stale interval for all BGP peers in a virtual routing and forwarding (VRF) instance or for a specific node in a VRF instance.
Ensure that the BGP graceful restart capability is exchanged with the peer and that the restart timer is received from the neighbor.
Use the procedures in this reference to configure Bidirectional Forwarding Detection (BFD) parameters.
Bidirectional Forwarding Detection (BFD) is a low-overhead network protocol that rapidly detects forwarding-path failures between two routing devices.
Provides subsecond failure detection.
Provides a consistent timeout mechanism for multiple routing protocols.
Detects failures across different physical media and Layer 2 topologies.
BFD is particularly useful in the following scenarios:
Peering routers connect through a Layer 2 device or cloud that does not make forwarding-path failures directly visible.
The physical medium, such as shared Ethernet, does not provide reliable failure detection.
Multiple routing protocols operate between the routers and require consistent, predictable convergence times.
The following guidelines and limitations apply to BFD:
Beginning with Cisco APIC Release 3.1(1), BFD between leaf and spine switches is supported on fabric interfaces for IS-IS and on spine switches for OSPF and static routes.
Beginning with Cisco APIC Release 5.2(4), BFD supports static routes that are reachable through secondary IPv4 or IPv6 subnets.
BFD is supported on modular spine switches with -EX, -FX, or later-generation line cards and on Cisco Nexus 9364C or later-generation fixed spine switches.
BFD between virtual port channel (vPC) peers is not supported.
Beginning with Cisco APIC Release 5.0(1), leaf switches support multihop BFD.
Beginning with Cisco APIC Release 5.0(1), Cisco ACI supports C-bit-aware BFD.
Beginning with Release 6.2(2), BFD supports multihop and single-hop sessions over eBGP and iBGP prefix peers.
You can enable BFD subinterface optimization in an interface policy.
To change a secondary address that sources a BFD session, add the new address in the same subnet before you remove the existing address.
BFD optimization on subinterfaces consolidates session management by designating the subinterface with the lowest VLAN ID as the master subinterface.
The master subinterface inherits the BFD session parameters from the parent interface.
The remaining subinterfaces use the slow timer for their session intervals.
A failure detected on the optimized subinterface causes all subinterfaces on the physical interface to transition to the down state.
You can enable the BFD echo function on one or both ends of a link. The echo configuration determines the required minimum receive interval associated with the slow timer.
When the echo function is disabled, the RequiredMinEchoRx parameter is set to zero.
When the echo function is enabled, the slow timer determines the required minimum receive interval.
If a subinterface flaps, all subinterfaces on the same physical interface are affected and transition to the down state for approximately one second.
Use this procedure to configure Bidirectional Forwarding Detection (BFD) for a secondary IPv4 address or an additional IPv6 address.
On the menu bar, choose .
In the work pane, double-click the tenant name.
In the navigation pane, choose .
In the work pane, choose , , or , depending on the interface type.
Double-click the interface that you want to configure.
Configure the secondary or additional address based on the interface type:
In the navigation pane, choose .
In the Static Routes table, click + and configure the static route:
Complete the remaining fields as required.
Click Submit.
Create the tenant.
You can configure an explicit Bidirectional Forwarding Detection (BFD) policy on routed Layer 3 interfaces, external switched virtual interfaces (SVIs), and routed subinterfaces. Use an interface override when an interface requires settings that differ from the global BFD policy applied to its switch or group of switches.
When you configure a BFD interface policy on a parent routed interface, routed subinterfaces with the same address family inherit the policy by default. To override an inherited setting, configure an explicit BFD interface policy on the subinterface. If Admin State or Echo Admin State is disabled on the parent interface, you cannot override that setting on a subinterface.
Bidirectional Forwarding Detection (BFD) consumer protocols require a protocol-specific setting that enables them to use BFD.
The BGP, OSPF, and EIGRP protocol policies are available in the navigation pane under .
Create the tenant.
Bidirectional Forwarding Detection (BFD) multihop detects forwarding failures across multiple network hops.
Supports IPv4 and IPv6.
Establishes sessions between specific source and destination addresses instead of between interfaces.
Supports paths of up to 255 hops.
The default and minimum transmit and receive intervals are 250 milliseconds.
The default and minimum detection multiplier is 3.
BFD multihop does not support echo mode.
You can configure a Bidirectional Forwarding Detection (BFD) multihop policy in several GUI locations, depending on the scope and purpose of the policy.
Global policies : By default, the APIC creates global BFD multihop policies when the system starts. You can modify the attributes of these policies in the work pane. Changes to a default global policy affect all switches. To use different settings for a specific switch or group of switches, create a switch profile and modify the BFD multihop settings in that profile.
You can create or modify global BFD multihop policies for IPv4 or IPv6 in the following GUI locations:
Fabric > Access Policies > Policies > Switch > BFD Multihop > BFD Multihop IPv4 : Right-click and choose Create BFD Global IPv4 MH Policy .
Fabric > Access Policies > Policies > Switch > BFD Multihop > BFD Multihop IPv6 : Right-click and choose Create BFD Global IPv6 MH Policy .
Node policies : A BFD multihop node policy applies to the interfaces under a node profile.
You can create or modify BFD multihop node policies in the following GUI location:
Tenants > tenant > Policies > Protocol > BFD Multihop > Node Policies : Right-click and choose Create BFD Multihop Node Policy .
Interface policies : A BFD multihop interface policy applies to the interfaces under an interface profile.
You can create or modify BFD multihop interface policies in the following GUI location:
Tenants > tenant > Policies > Protocol > BFD Multihop > Interface Policies : Right-click and choose Create BFD Multihop Interface Policy .
Override policies : To override the default global configuration for specific switches or interfaces, create a BFD multihop node or interface policy and associate it with the appropriate profile.
You can create or modify BFD multihop override policies for a node profile or interface profile in the following GUI locations:
Tenants > tenant > Networking > L3Outs > l3out > Logical Node Profiles > logical_node_profile : Right-click, choose Create BFD Interface Protocol Profile , and specify a BFD multihop node policy.
Tenants > tenant > Networking > L3Outs > l3out > Logical Node Profiles > logical_node_profile > Logical Interface Profiles > logical_interface_profile : Right-click, choose Create MH-BFD Interface Protocol Profile , and specify a BFD multihop interface policy.
Tenants > infra > Networking > SR-MPLS Infra L3Outs > l3out > Logical Node Profiles > logical_node_profile > Logical Interface Profiles > logical_interface_profile : Right-click, choose Create MH-BFD Interface Profile , and specify a BFD multihop interface policy.
Micro BFD enhances BFD by establishing an individual BFD session on each member link of a port channel.
Detects failures faster on individual member links.
Identifies the specific failed links in a port channel.
Automatically removes failed links from port-channel forwarding.
The following guidelines and limitations apply to micro BFD:
Micro BFD is supported on both Link Aggregation Control Protocol (LACP) and non-LACP port channels.
Micro BFD can run simultaneously with multihop BFD on the same port channel, but it cannot run with single-hop BFD on the same port channel.
Micro BFD functions as a single-hop BFD implementation. It does not operate if a Layer 2 switch is located between the main port channel and the peer.
Micro BFD can run on a parent port channel while single-hop BFD runs on subinterfaces of the same port channel.
Micro BFD is not supported on first-generation leaf switches whose product IDs do not have an -EX or -FX suffix.
Micro BFD is supported only on a routed interface over a port channel.
Client protocols can run on a subinterface of the same port channel on which micro BFD is enabled.
Micro BFD is not supported on fabric extender (FEX) ports or fabric ports.
BFD echo mode is not supported for micro BFD sessions.
On a dual-stack port channel, configure micro BFD with either an IPv4 address or an IPv6 address, but not both.
Creating or deleting a Layer 3 port-channel main interface causes the physical member ports to flap. This behavior can cause traffic loss if subinterfaces are active.
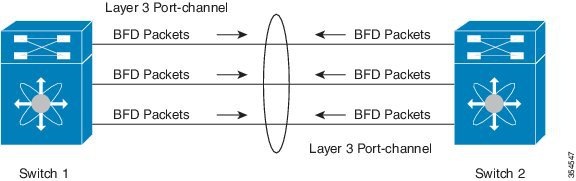
Configure a direct port channel for the L3Out interface.
This procedure enables Micro BFD on an L3Out port-channel interface. Micro BFD establishes an individual BFD session on each member link of the port channel.
Verify the Micro BFD sessions by using the CLI commands shown in the following example:
leaf4# show port-channel database interface port-channel 3
                port-channel3
                Last membership update is successful
                4 ports in total, 4 ports up
                First operational port is Ethernet1/44
                Age of the port-channel is 0d:22h:46m:03s
                Time since last bundle is 0d:22h:42m:43s
                Last bundled member is Ethernet1/44
                Ports: Ethernet1/41 [on] [up]
                Ethernet1/42 [on] [up]
                Ethernet1/43 [on] [up]
                Ethernet1/44 [on] [up] *
                leaf4# show bfd neighbors vrf tenant1:vrf1
                OurAddr NeighAddr
                LD/RD RH/RS Holdown(mult) State Int Vrf Type
                2003:190:190:1::1 2003:190:190:1::2
                1090519041/0 Up 6000(3) Up Po3 tenant1:vrf1 singlehop
                2003:190:190:1::1 2003:190:190:1::2
                1090519042/2148074790 Up 180(3) Up Eth1/44 tenant1:vrf1 singlehop
                2003:190:190:1::1 2003:190:190:1::2
                1090519043/2148074787 Up 180(3) Up Eth1/41 tenant1:vrf1 singlehop
                2003:190:190:1::1 2003:190:190:1::2
                1090519044/2148074789 Up 180(3) Up Eth1/43 tenant1:vrf1 singlehop
                2003:190:190:1::1 2003:190:190:1::2
                1090519045/2148074788 Up 180(3) Up Eth1/42 tenant1:vrf1 singlehop